By the time you write a post-mortem, you already paid for the lesson in cash, reputation, and calendar time.
Every team I have worked with calls itself careful. Ask the same team to name the failure mode of the thing they shipped last quarter, and the room goes quiet.
I own the system of record under InMobi’s demand-side platform and ad exchange, processing 200 million-plus devices’ worth of ad events a day. Nothing in that pipeline gets a second chance at a clean number once the month closes. This post is the ritual I run before a launch to buy that second chance while it is still free.
So that’s today’s post.
Today’s Post
The meeting that runs before the launch, while the failure is still imaginary and still preventable, in six sections.
- Why a pre-mortem is triage and a post-mortem is an autopsy
- The incentive problem forward planning never fixes
- Why a narrated disaster beats a risk register
- The thirty-minute structure, run with discipline
- The quiet risks that get expensive
- What has to happen after the meeting, or none of it counts
1. Post-mortems are autopsies. Pre-mortems are triage.
A post-mortem asks what went wrong after the damage is done. Customers already churned. The team already burned nights fixing what should not have shipped.
A pre-mortem asks a different question. Assume you failed. Assume it was loud and expensive. Now explain how you got there.
That is not pessimism. It is timing. You move the most valuable conversation to the one point where the fix is still cheap.
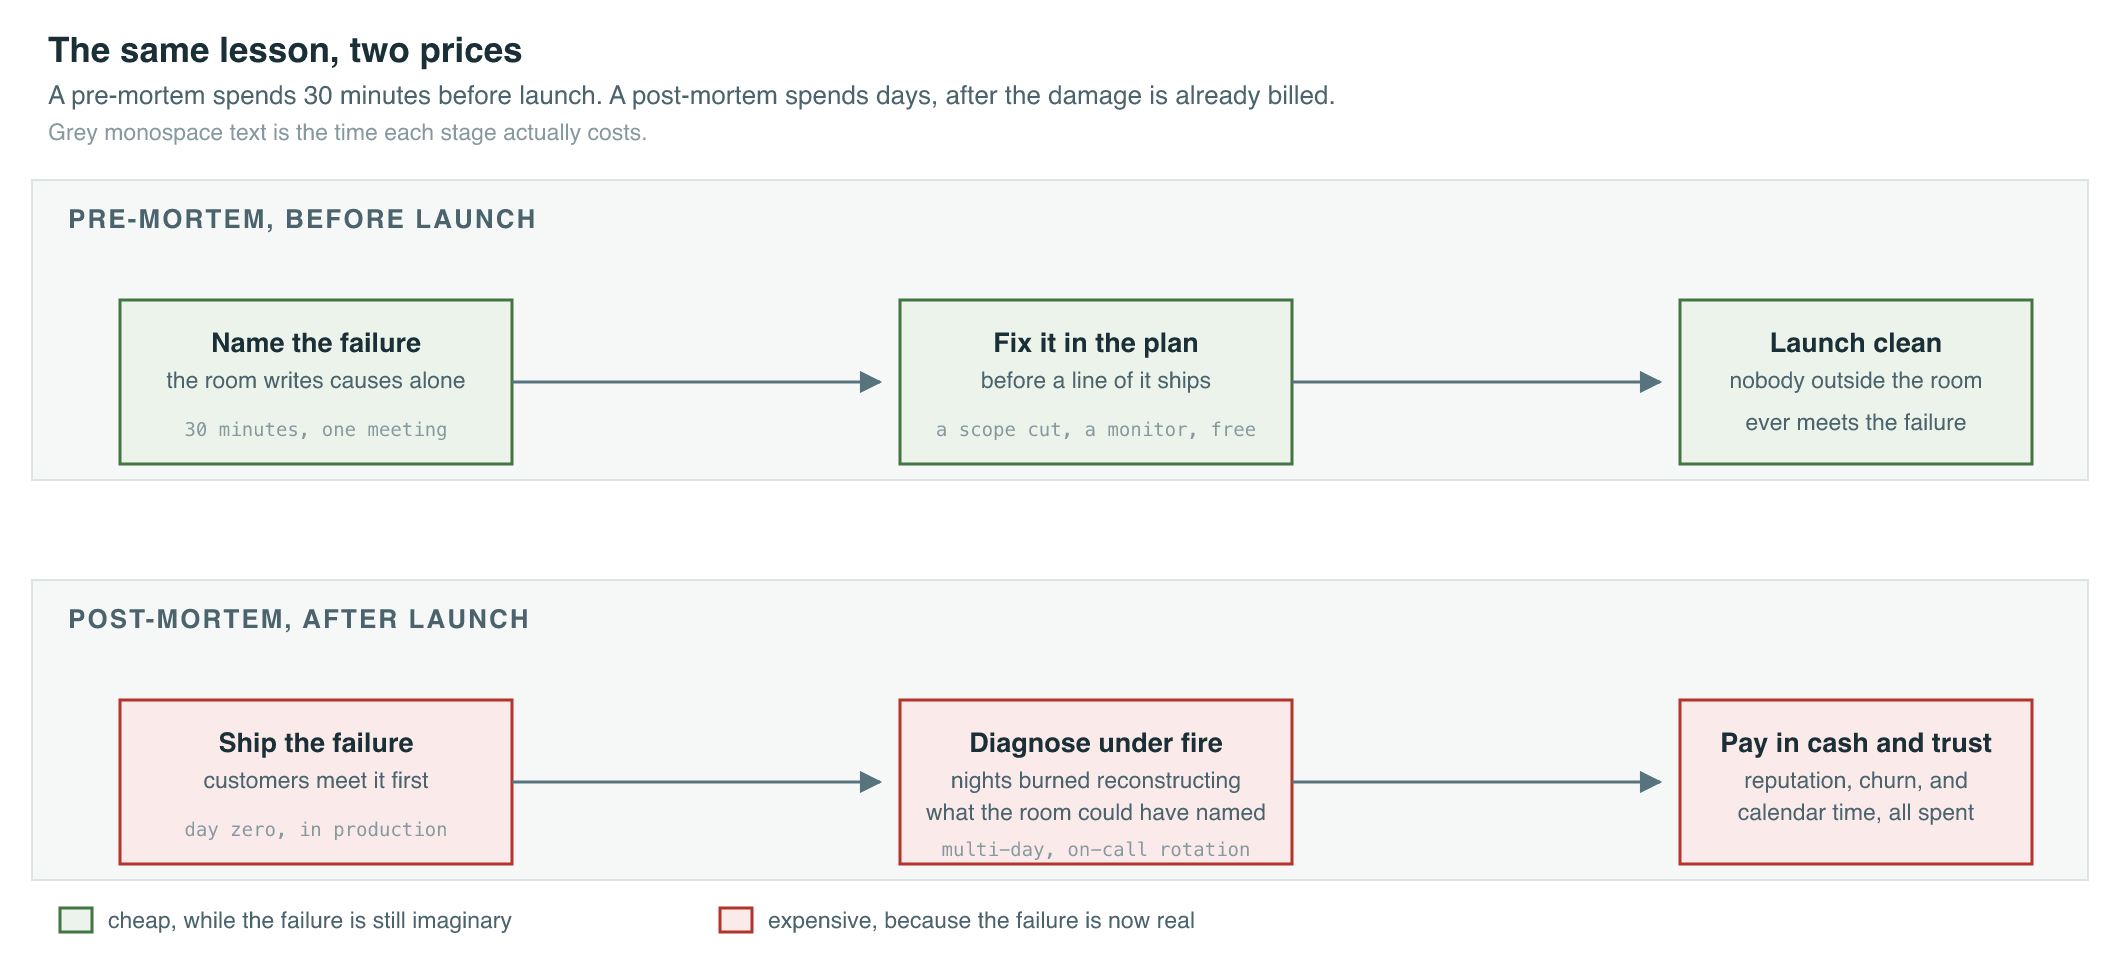
At InMobi, the close on that 200-million-device pipeline runs every month whether anyone asks for it or not. A pre-mortem borrows that same trick on purpose, on a schedule you set, before the number exists yet to argue about.
2. Forward planning rewards optimism, and punishes doubt
Normal planning meetings carry a hidden bias toward momentum. The roadmap slide is green. Raising a real concern can sound like a lack of conviction, so people smooth the edges and save the doubt for a private chat that never reaches the room that needs it.
A pre-mortem flips the incentive. The most valuable contribution in the meeting becomes the darkest scenario, not the most confident one.
I saw this decision play out directly on Prism, the AI co-pilot I built at Pixis. One-click campaign changes were the whole magic of the product, and also the whole risk. The team’s answer was structural, not a warning nobody acted on: the AI proposes and explains, the human commits. That line exists in the product today because someone was allowed to say the loud version of “what if it’s wrong” out loud, before a customer found out first.
3. A narrated disaster beats a risk register
Human brains explain outcomes better than they generate probabilities. Ask a team for risks in the abstract and you get a shallow list: performance, security, bugs. Ask the same team to narrate a specific failure and you get a trigger, a screenshot, a customer quote.
That specificity is where prevention lives. A vague risk is a category. A storied failure is a causal chain, and a causal chain has a link you can interrupt.
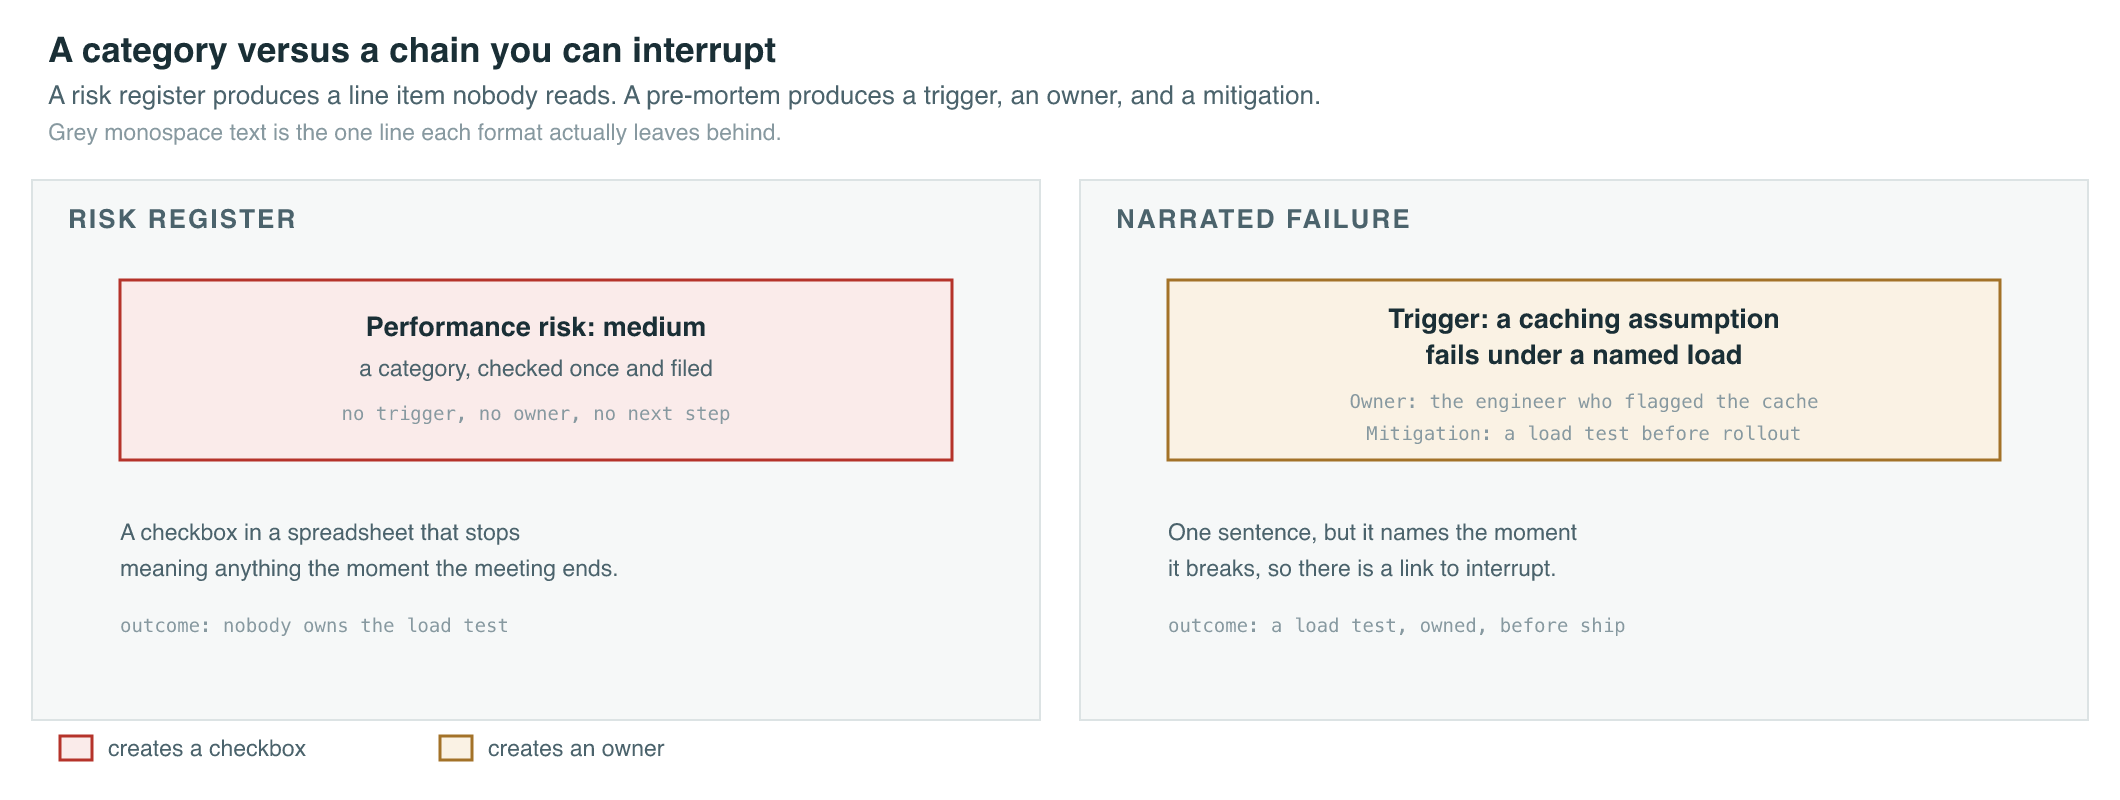
A register says “performance risk, medium.” A pre-mortem says a caching assumption failed under a named load and nobody owned the load test. One of those sentences creates an owner. The other creates a checkbox.
4. The thirty-minute structure
A pre-mortem needs a tight structure and a leader who protects the frame, not a facilitator certification.
State the launch and the definition of success in plain language everyone agrees on. Announce the premise: it is weeks from now, and the project failed, loudly and expensively. Give the room two minutes to write causes alone, so the loudest voice does not anchor everyone else. Collect themes and cluster duplicates until each one is a sentence a stranger could understand. Mark what is already owned against what is not, because teams routinely discover they were worried about a risk nobody owned. Then pick the smallest set of actions that move the top scenarios: a monitor, a scope cut, a rollback trigger, a slower rollout.
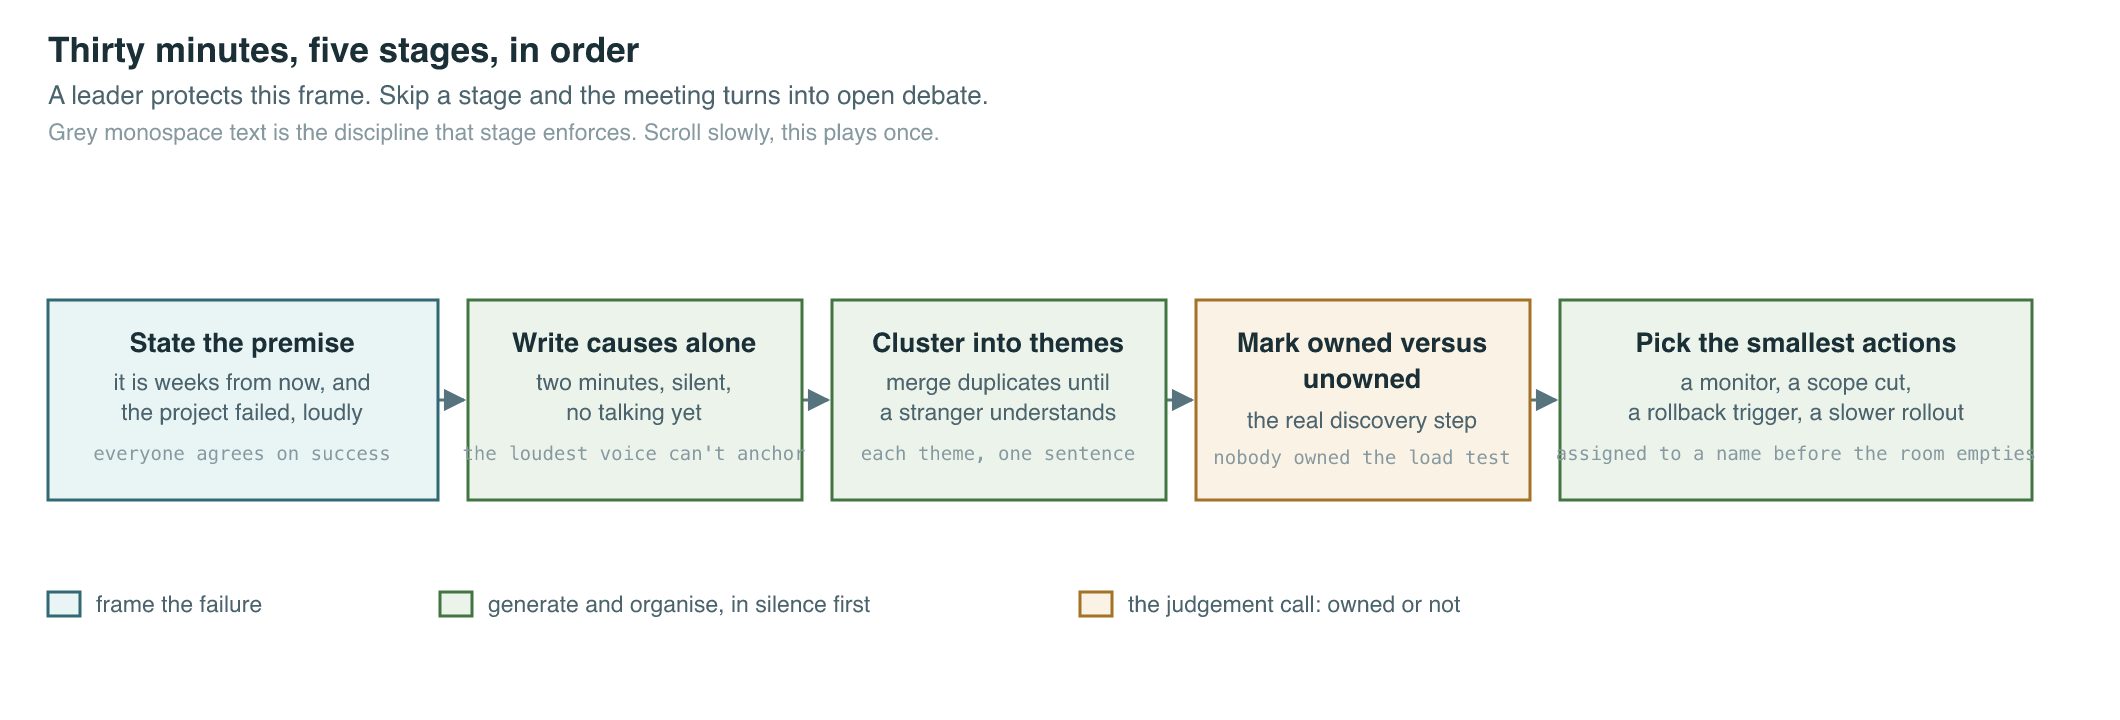
If you walk out with no action assigned to a name, you ran a performance instead of a pre-mortem.
5. The quiet risks are the expensive ones
Post-mortems tend to document failures everyone half-expected. The scalability cliff, the ambiguous metric, the partner dependency that was “probably fine.” Those risks were visible in advance. They were just expensive to say out loud in a normal planning meeting.
A pre-mortem changes who gets to speak first. The engineer who noticed the brittle integration gets to name it without sounding like they are blocking the launch. That is the same shift behind the reliability work I ran at Pixis: making data freshness a number the team was accountable to, instead of a worry nobody wanted to own out loud, cut availability delays on that platform from four hours to under fifteen minutes for 400-plus enterprise customers.
Speed without a pre-mortem is often risk compression. You are not moving faster. You are moving the same risk closer to the customer.
6. A pre-mortem that changes nothing is worse than no ritual
If the team names the same three disasters every launch and leadership always picks speed anyway, people stop bringing their best scenarios. They perform the exercise instead of running it.
The fix is not a longer meeting. The fix is a written decision. My own rule from how I run specs applies here without edits: unwritten means undecided. If a top scenario has no owner, assign one before the room empties. If the mitigation is too expensive, say so and record the accepted risk. If the risk is unacceptable, change the scope or change the date.
A pre-mortem that produces no decision log is a moral license to launch, not a safeguard. Treat it as a fork in the road, not a ritual you check off.
Takeaways
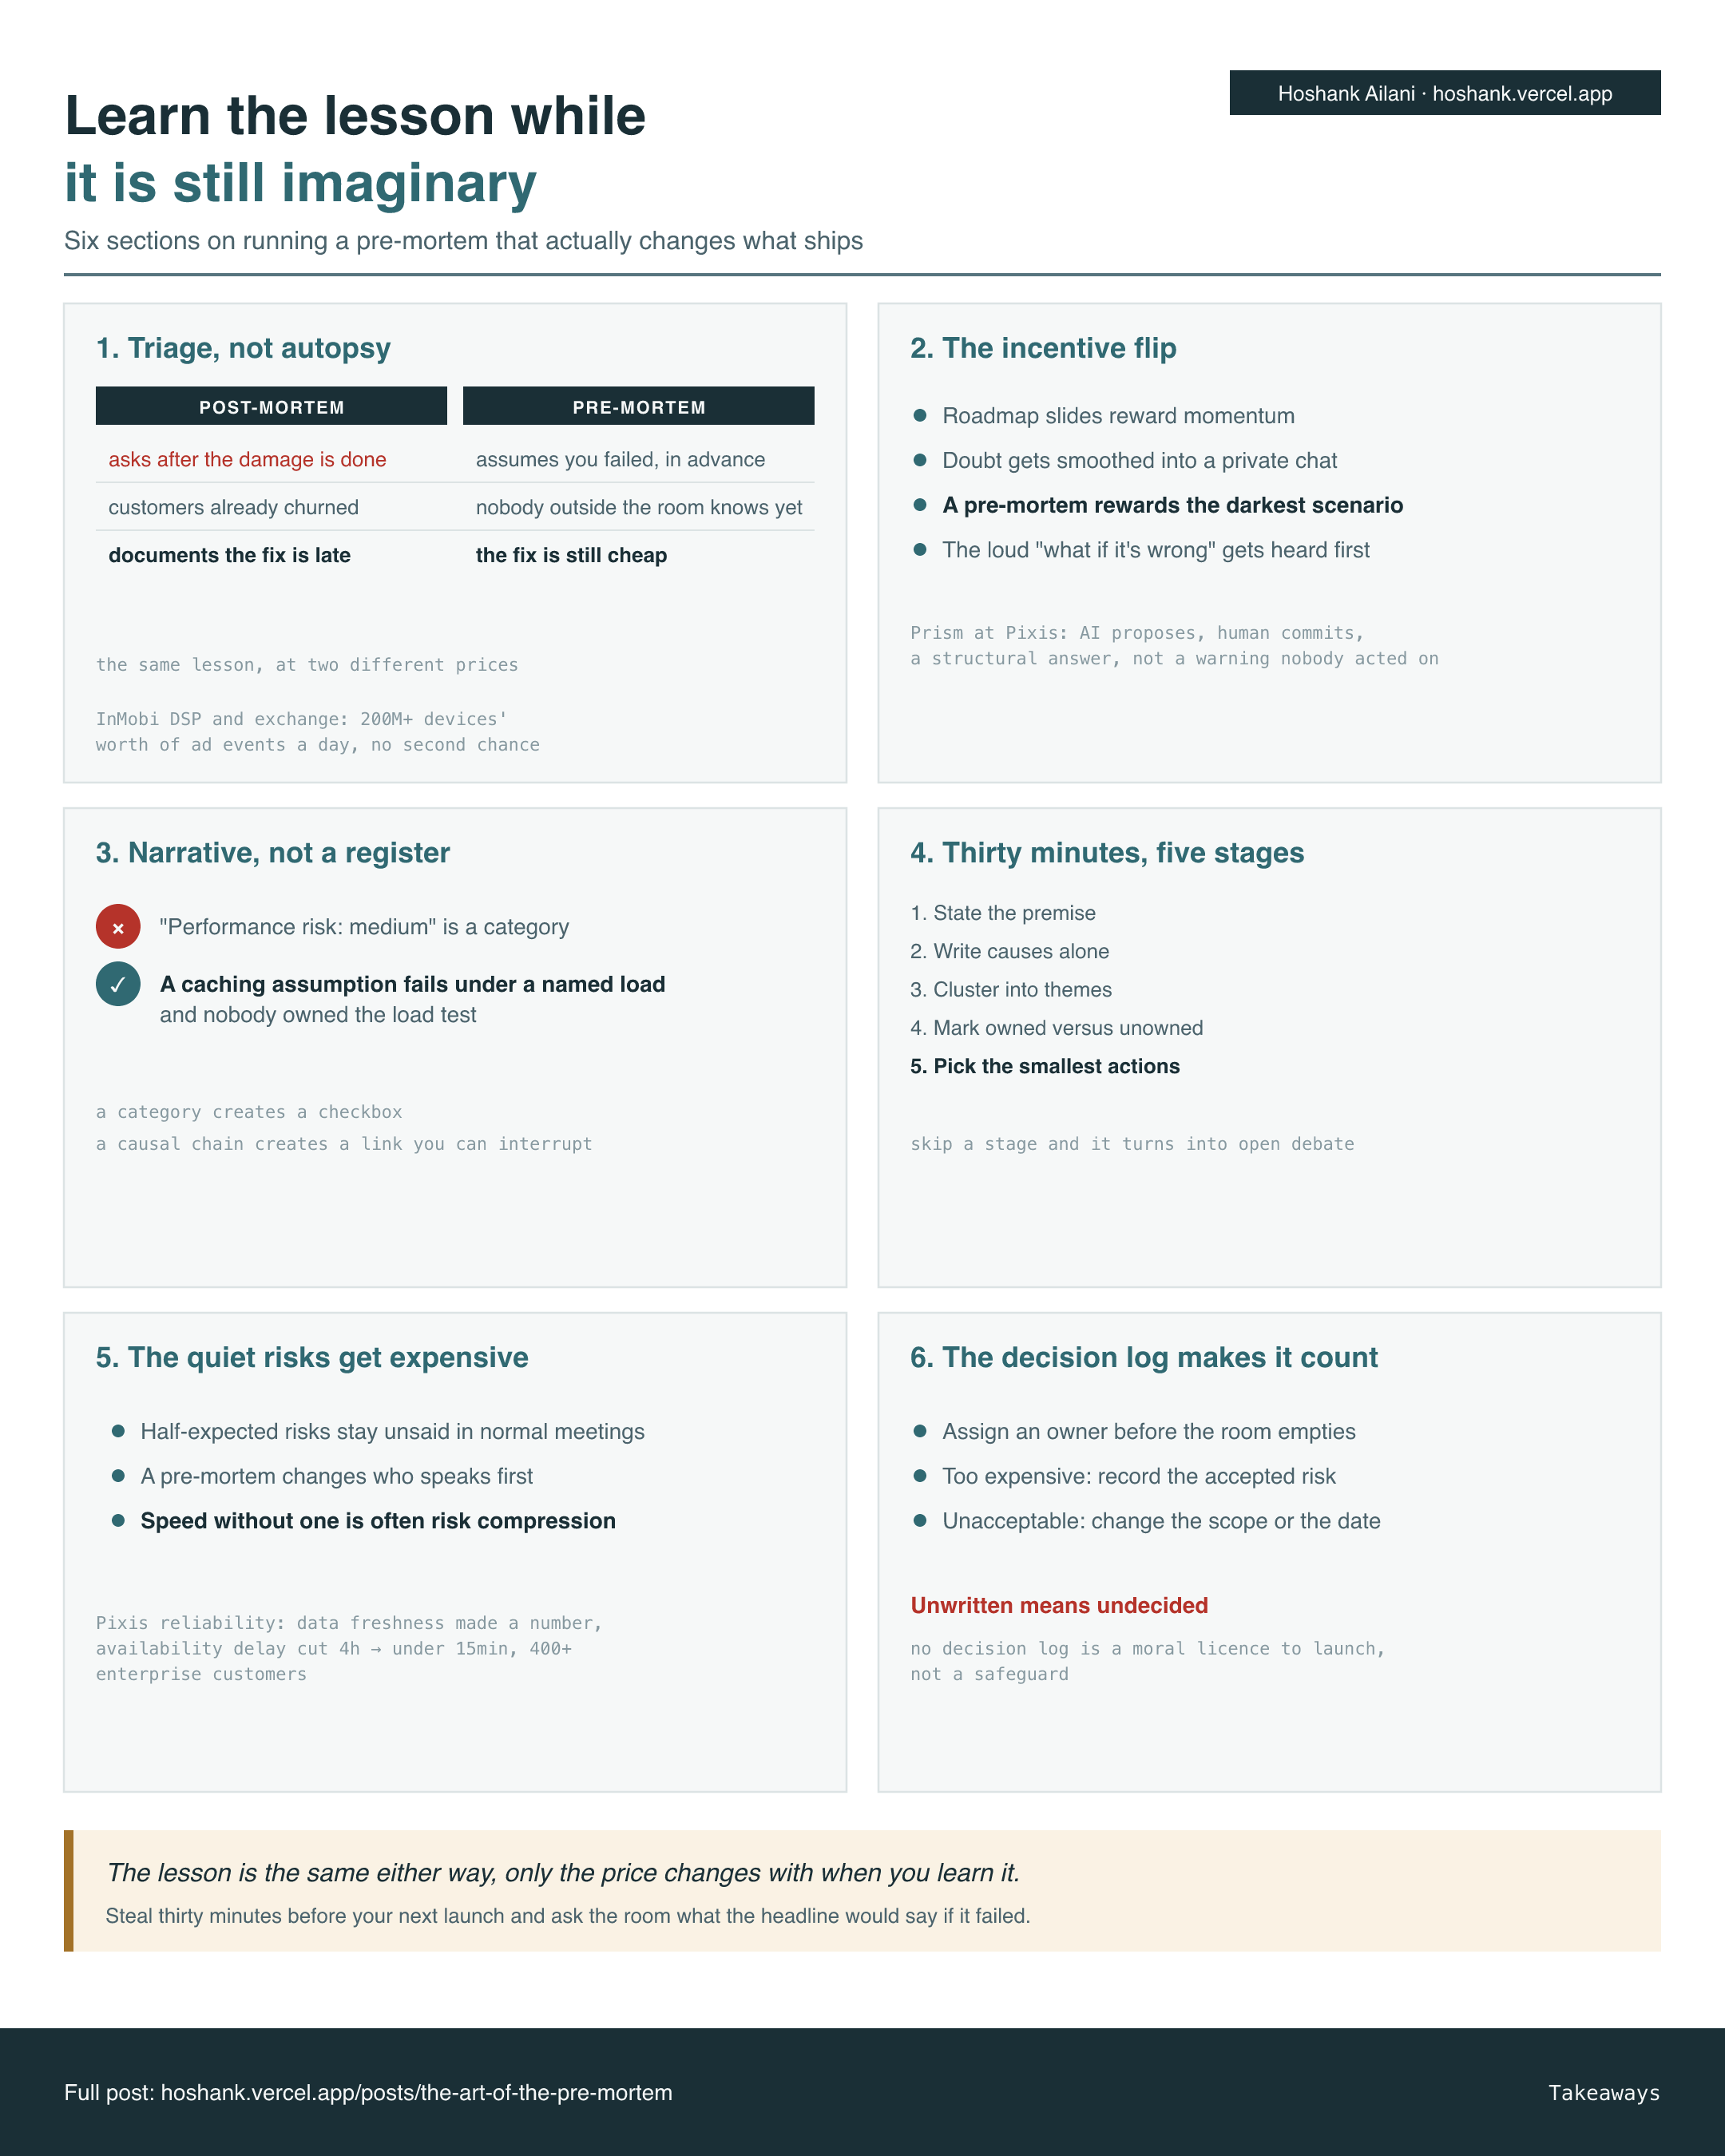
Six panels, one per section. The thesis on the callout: the lesson is the same either way, only the price changes with when you learn it.
Final Words
Most teams will keep treating the post-mortem as proof of maturity, and keep documenting the same class of failure quarter after quarter. Pick your next launch, steal thirty minutes before it ships, and ask the room what the headline would say if it failed loudly. Then write down who owns the answer.
Reply and tell me what your team named. I am collecting the scenarios that actually got an owner.
Cheers, Hoshank