A team with 40 AI licenses and zero decision logs has AI access, not AI adoption.
Every company I’ve worked with declared victory on AI the day everyone got a seat: Dell’s supply-chain org, a 20-person AI team at Pixis, InMobi’s ad exchange. Usage dashboards went up in all three. Ask any of them what changed at the team level, six months later, and the room goes quiet.
I’ve spent the last year building the AI-first version of that answer on this site: a CLAUDE.md, a specs/ROADMAP.md, and a portfolio of drafted Claude Code experiments, instead of a folder of favorite prompts. This post is what building that taught me about the gap between an AI tool and an AI system.
So that’s today’s post.
Today’s Post
Why individual productivity never becomes team capability on its own, in six sections.
- The trap of individual productivity
- Why “everyone has access” is not adoption
- Judgment infrastructure, defined with this site’s own files
- Why most teams treat it as content instead of operations
- The trust problem: every instruction file is a control surface
- What good adoption actually looks like, and the deeper weakness it exposes
1. The individual productivity trap
AI tools make individuals dramatically more productive. That part is not in question.
A PM who knows what to ask gets a first draft, a synthesis, a working diff in minutes instead of a day. On this site’s own spec-driven build, an AI coding agent turns a written spec into a working diff in about fifteen minutes.
Here is the trap. The person getting great results is supplying a mental model built from experience, domain knowledge and a hundred small corrections. The model is a generalist. The person is the judgment, the context and the quality filter, all three, every time.
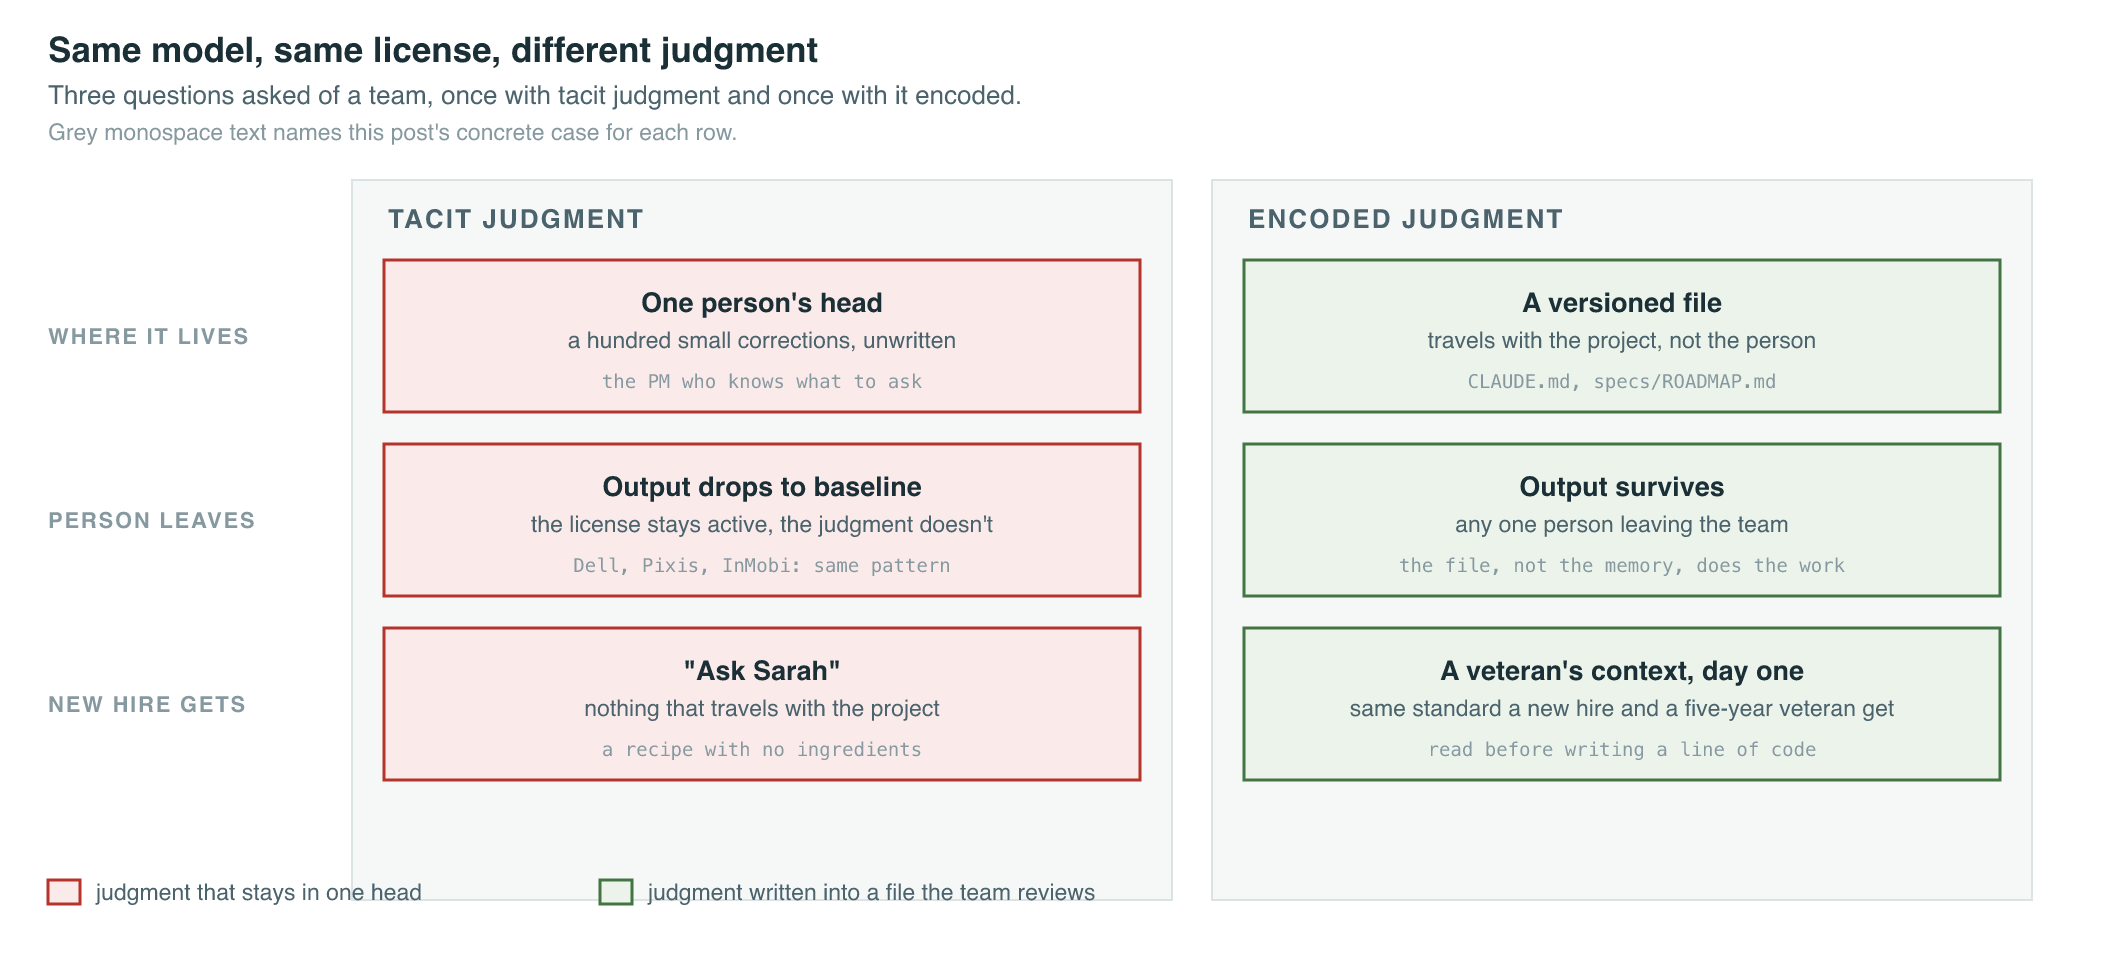
When that person changes roles, the team’s AI output drops back to baseline. The license is still active. The judgment left with the person.
2. Why “everyone has access” is not adoption
True adoption is not “everyone can open the tool.” It is “the tool produces consistent quality without depending on any one person’s expertise.”
That is a much harder bar, and most teams have not cleared it.
The symptom is familiar from every team I’ve sat on: one person’s AI-assisted review is sharp, another person’s is generic, and the tool is identical in both cases. Some teams reach for a prompt library to close the gap. It helps for a week. A prompt without the context that produced it is a recipe without ingredients, correct in the kitchen it was written in, wrong everywhere else.
3. Judgment infrastructure, defined
The missing layer is not a better prompt. It is a way to encode, distribute and maintain the judgment that makes AI useful in your specific context.
Concretely, on this site that layer is two files and a habit. CLAUDE.md states the conventions an AI agent should already know before touching a file, the width prop that defaults to wide, the fact that Biome runs before Prettier, which env vars are secret. specs/ROADMAP.md is the single source of truth for what is drafted, approved and implemented, so a spec written for one feature carries the standard into the next one instead of living only in the PM’s head. Neither file is documentation in the sense of “nice to have.” An agent reads CLAUDE.md before it writes a line of code on this repo, every session.
The Anthropic product-experiments portfolio I built alongside this site names the same idea directly: teams that win with an AI coding agent invest in CLAUDE.md, encoded slash commands, verification loops and MCP servers, not in longer prompts. Six of the seven drafted experiments in that portfolio are bets on exactly that infrastructure layer, not on a smarter model.
4. Why most teams treat this as content, not operations
Most teams collect a folder of useful prompts, share it in a wiki, and call that “AI best practices.”
Three months later, half the instructions describe an architecture that no longer exists. The codebase moved. The process changed. Nobody updated the file because nobody owns the file. This is the exact failure pattern that kills internal documentation, and stale AI instructions are worse than none: they produce output that looks right and is subtly, expensively wrong.
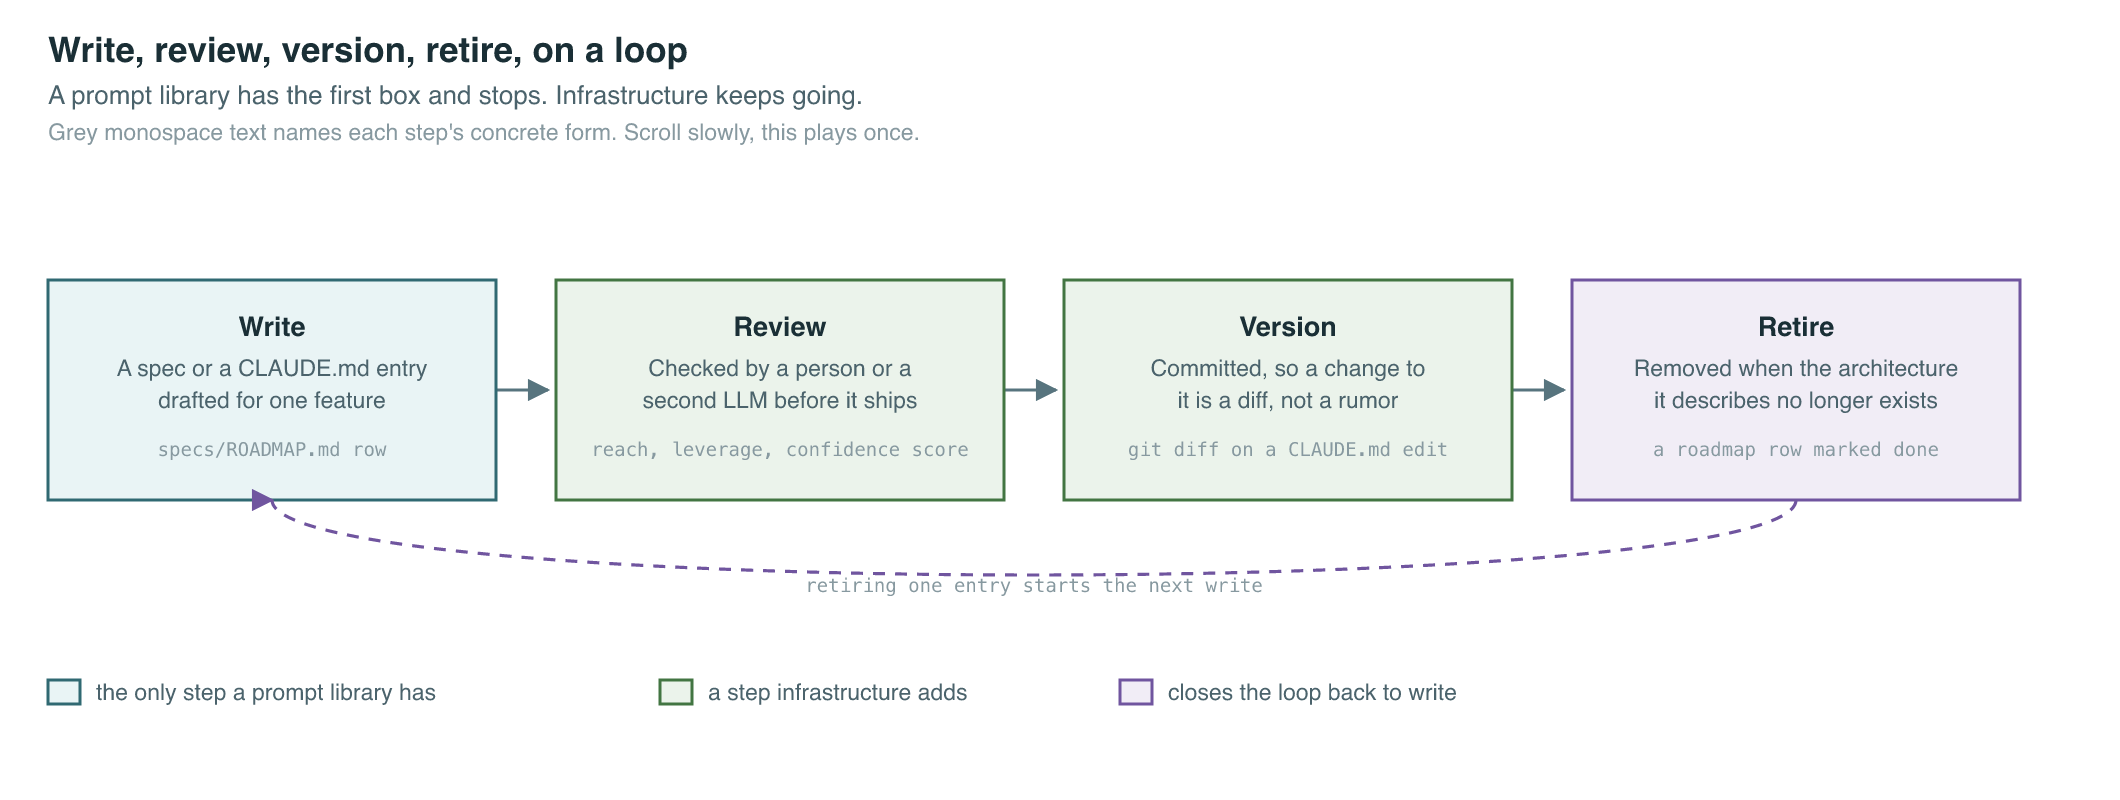
The fix is not more discipline in the abstract. It is treating the instruction layer the way spec-driven SDLC treats a feature spec: written first, reviewed before it ships, versioned so a change is a diff someone approved, and retired when it stops matching reality. This site runs twelve-plus specs through exactly that loop today, and the roadmap row is the only place anyone has to look to know the true state of any of them.
5. The trust problem: every instruction file is a control surface
An AI instruction is not passive documentation once an agent can act on it. In an agentic workflow, an instruction directs code generation, edits files, runs commands.
That makes every CLAUDE.md, every skill, every system prompt a control surface, with consequences a shell script in a build pipeline would also have. Most teams review the shell script and skip the instruction file.
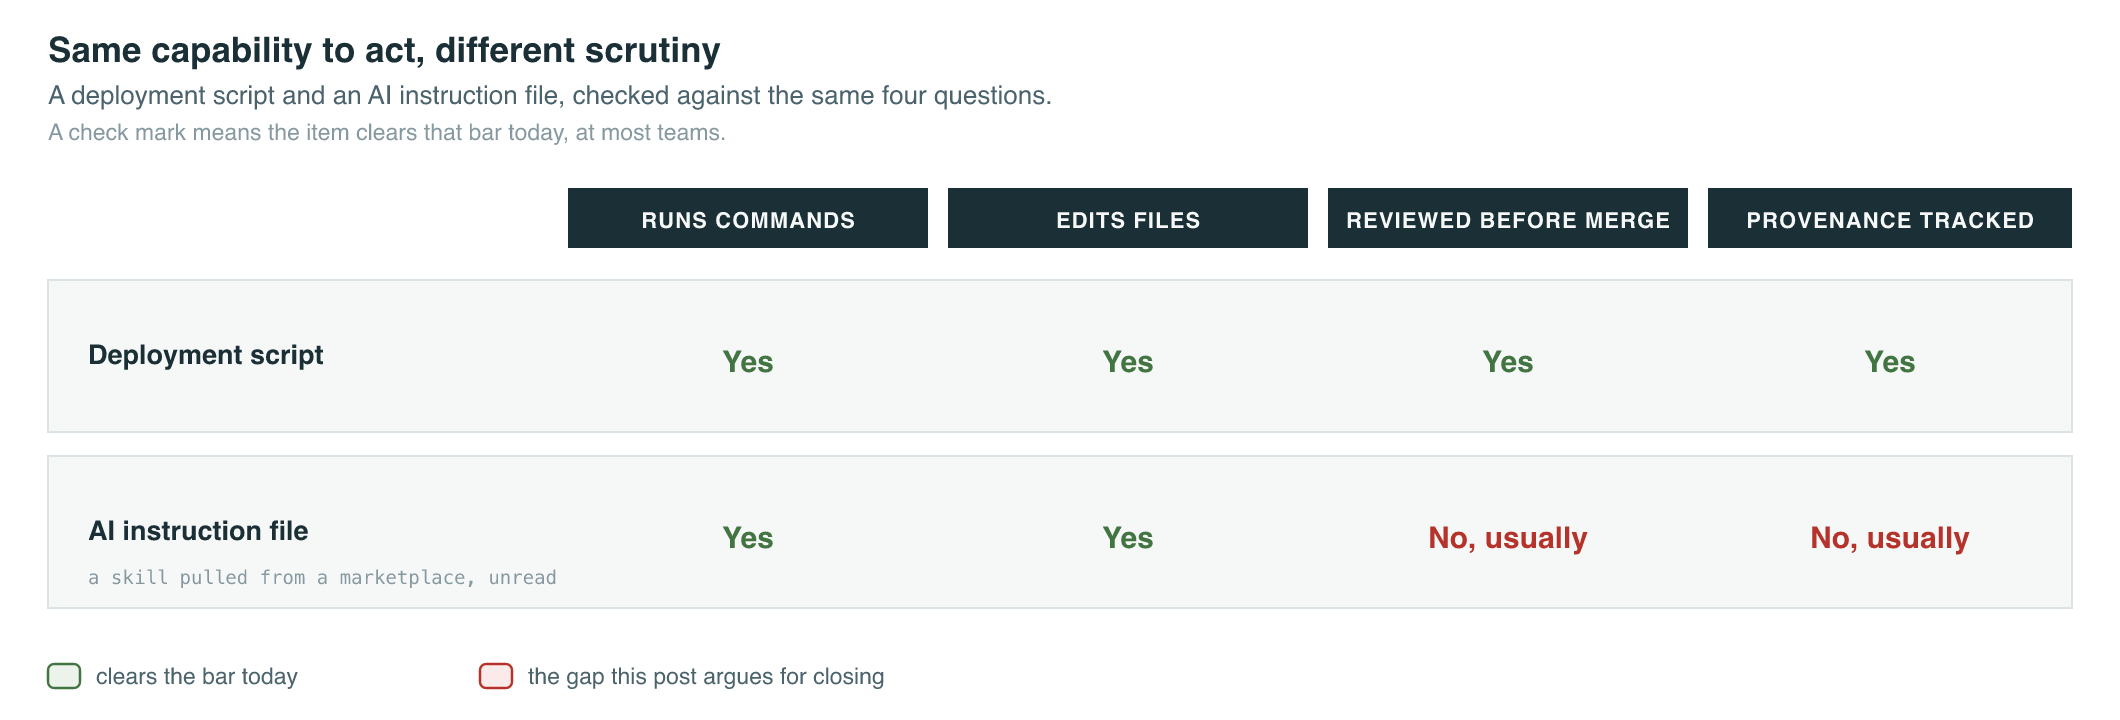
As more teams pull AI skills from marketplaces and shared repositories instead of writing their own, provenance stops being optional. The anthropic-product-experiments portfolio treats this literally: each drafted experiment is scored for reach, leverage and confidence before it gets a run, the same triage a security review gives an unfamiliar dependency, not a vibe check.
6. What good adoption looks like, and the weakness under it
Good AI adoption is boring on purpose. It looks like a team with maintained instructions that travel with the project rather than a person, a review cadence for changes to those instructions, and a way to tell whether the AI-assisted output is meeting a standard, not just whether people are using the tool. It looks like someone whose job includes retiring the instructions that no longer apply.
None of that is a LinkedIn moment. It is the difference between “our team uses AI” and “our team is better because of AI.”
The deeper problem this exposes predates AI by years. Most organizations never turned tacit knowledge into explicit systems. “Ask Sarah, she knows how we handle those edge cases” was already the failure mode before any model existed. AI just forces the choice sooner: encode the judgment into a file that survives Sarah’s next role change, or keep paying full price for rediscovery in every prompt, every review, every new hire’s first month.
That is uncomfortable, which is why most teams buy the tool and skip the harder part. A smaller group will build the file that says what “good” means on their team, review changes to it the way they review a pull request, and treat it like the infrastructure it is.
Takeaways
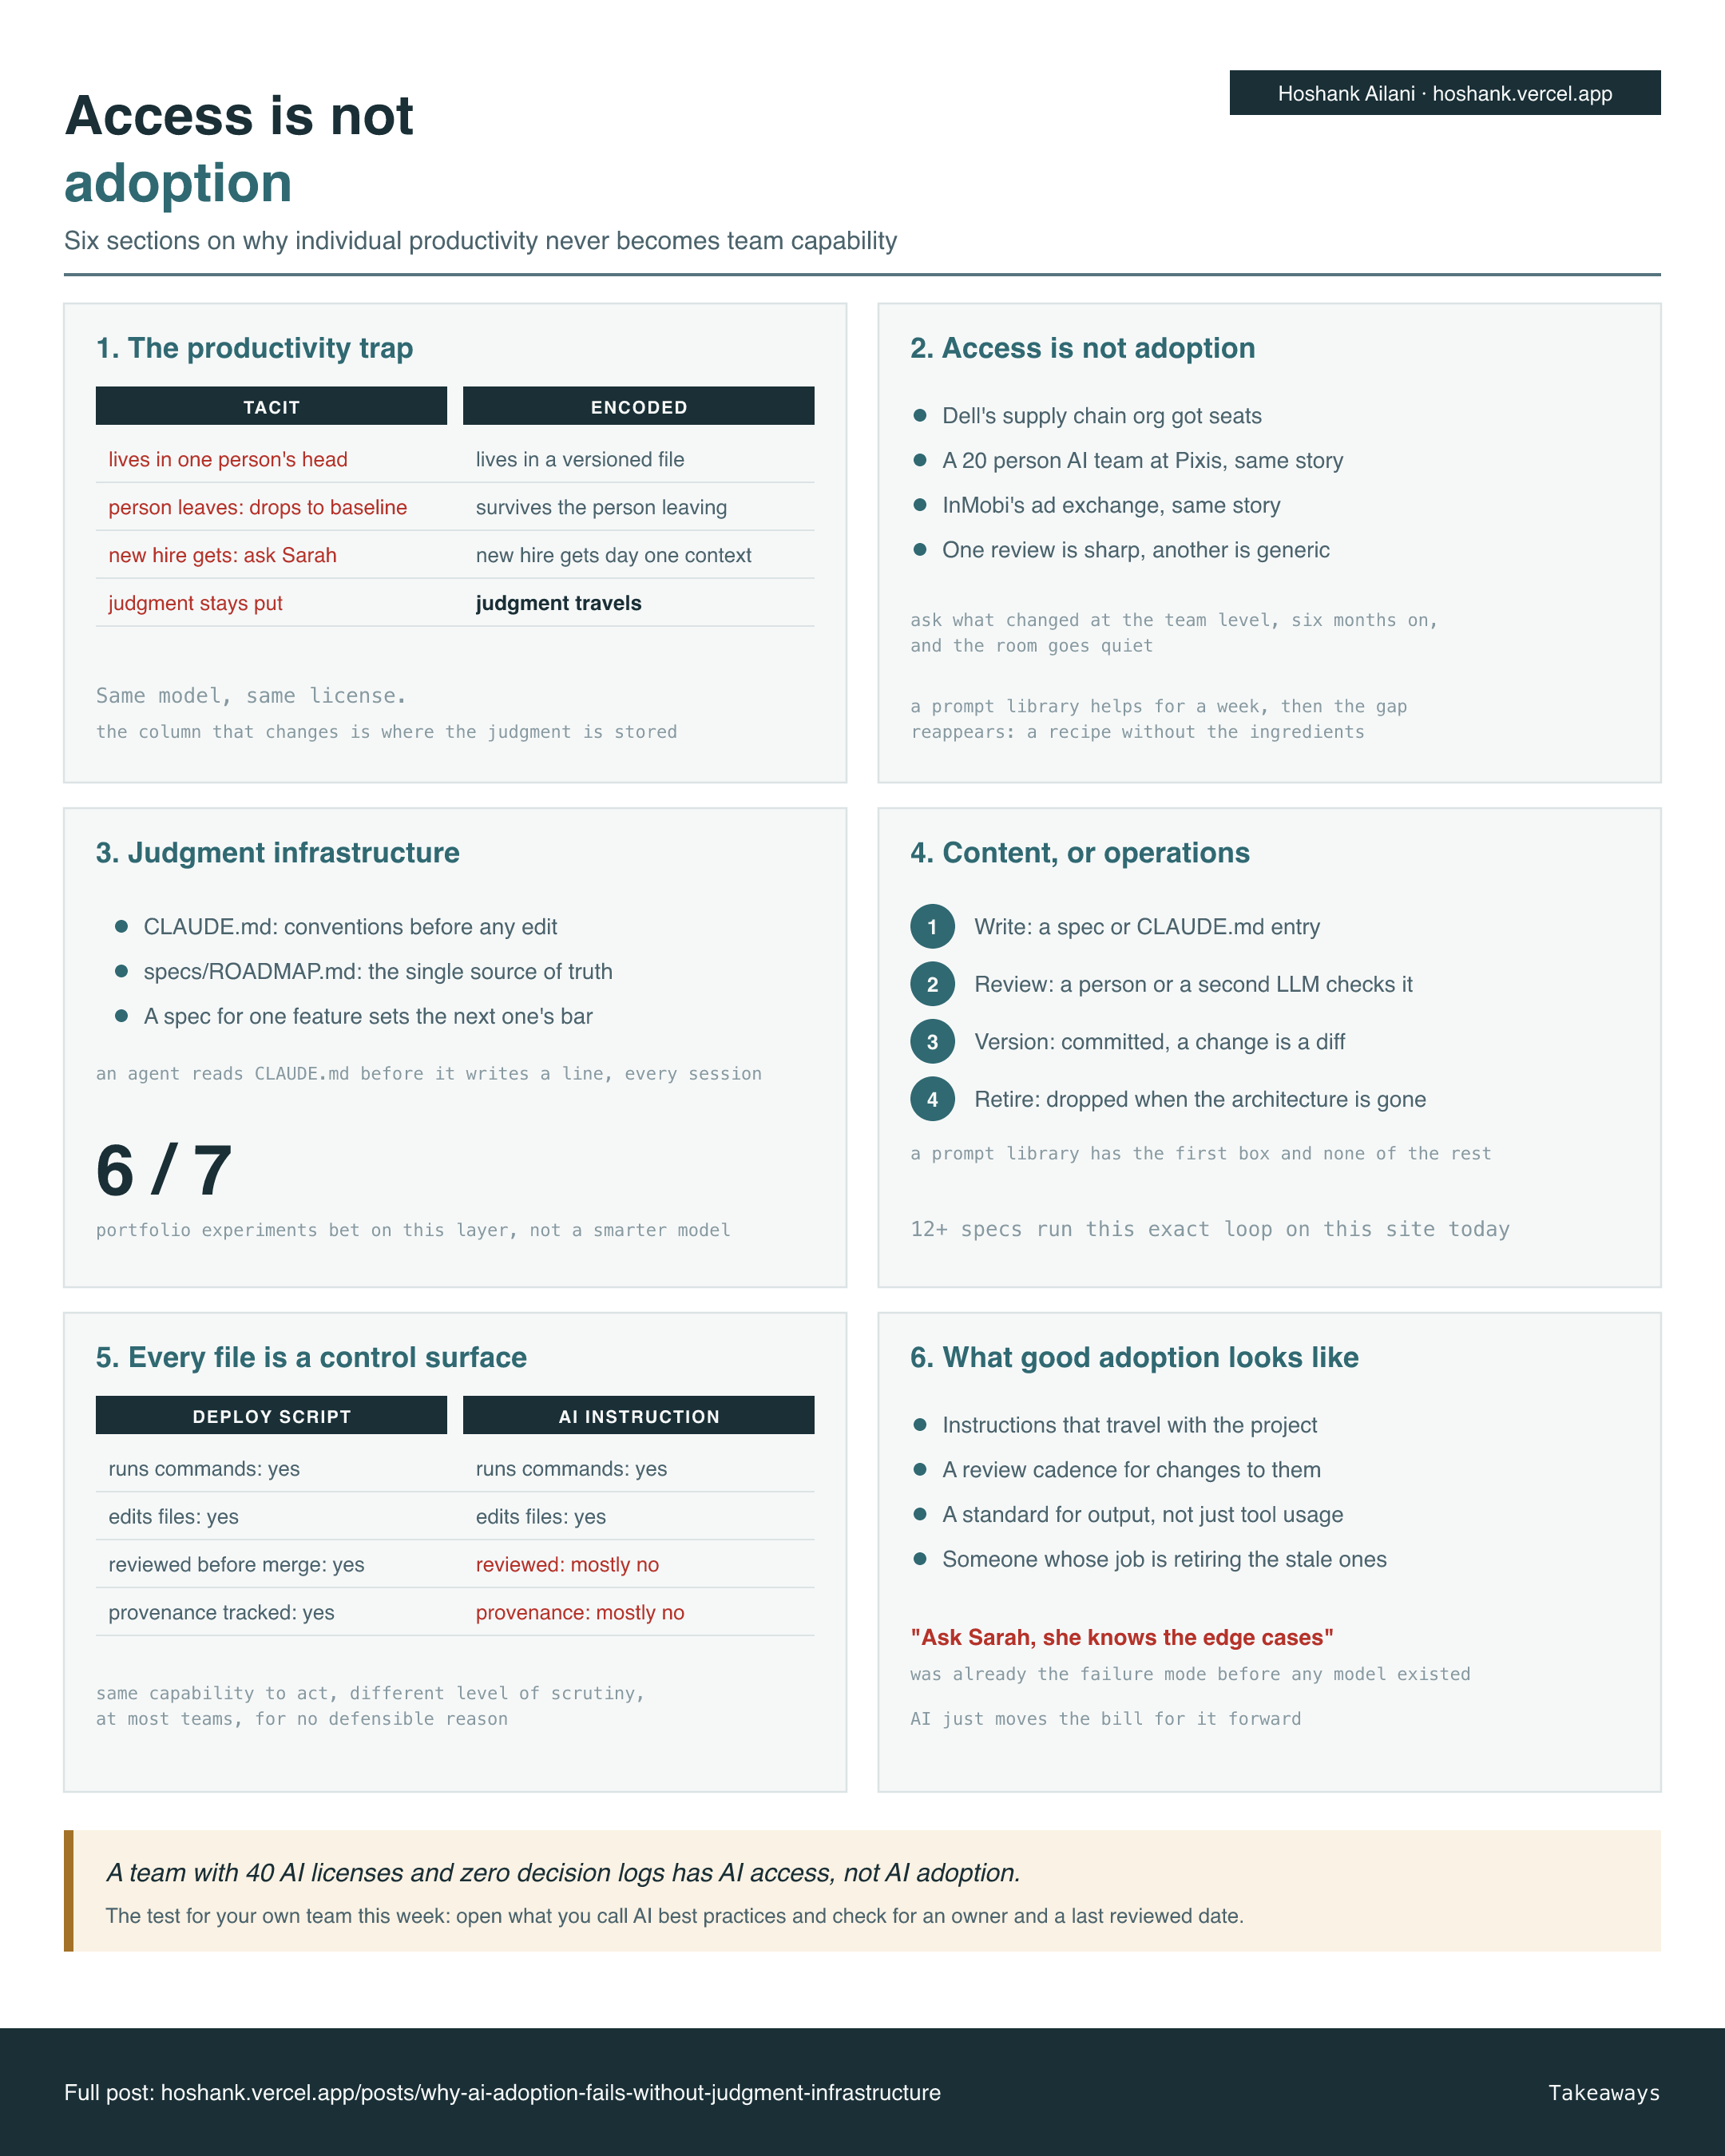
Six panels, one per section. The callout is the thesis, and the test to run on your own team’s AI setup this week.
Final Words
Most teams have the licenses, the dashboards and the lunch-and-learn. What they lack is the file: a versioned, reviewed, owned place where the team’s judgment lives so it travels with the project instead of one person. Open whatever your team currently calls “AI best practices” and check whether it has an owner and a last-reviewed date. If it doesn’t, that’s this week’s fix, not next quarter’s.
Reply and tell me what you found in yours.
Cheers, Hoshank