The moment a hero is required to hit the date, the plan already failed.
I have watched three teams reach for the same fix under deadline pressure: find the person who can carry it, and let them carry it. At Dell it was an engineer who knew the supply-chain integration by heart. At Pixis it nearly became me, the PM standing between every squad and every blocked ticket. At InMobi, the fix that actually worked looked nothing like a hero. It looked like a reconciliation pipeline with a target next to it.
I own the system of record under InMobi’s demand-side platform and ad exchange, which processes 200M+ devices’ worth of ad events a day. The month-end revenue close on that data used to take 5 days. It now takes 12 hours. Nobody stayed up for that number. A rule did.
So that’s today’s post.
Today’s Post
Why the hero is a symptom, not a strength, and what to build instead, in six sections.
- Why the midnight save is a system failure wearing a halo
- What process bought at Pixis that a hero never could
- Why organizations reward intensity and miss reliability
- Why a PM absorbing every escalation is heroics with a spreadsheet
- Why a customer deadline turns heroic without an honest capacity model
- What leadership has to reward instead of the firefighter
1. The midnight save is a system failure wearing a halo
Every team has a version of the same story. The deploy breaks at 11pm and one engineer fixes it before the morning stand-up. Leadership praises the save. The engineer feels indispensable. The calendar quietly normalizes the next 11pm.
Read that pattern from the inside and it looks like commitment. Read it from the outside and it is a system confessing that it cannot hit its own commitments without extracting sleep from one person.
The hero masks a gap that was never closed. Dependencies were unclear. Scope crept without a renegotiation. The plan assumed nobody would get sick, leave, or have a family emergency in the wrong week. When the clock ran out, the organization discovered it had bought insurance in the form of one person’s willingness to suffer.
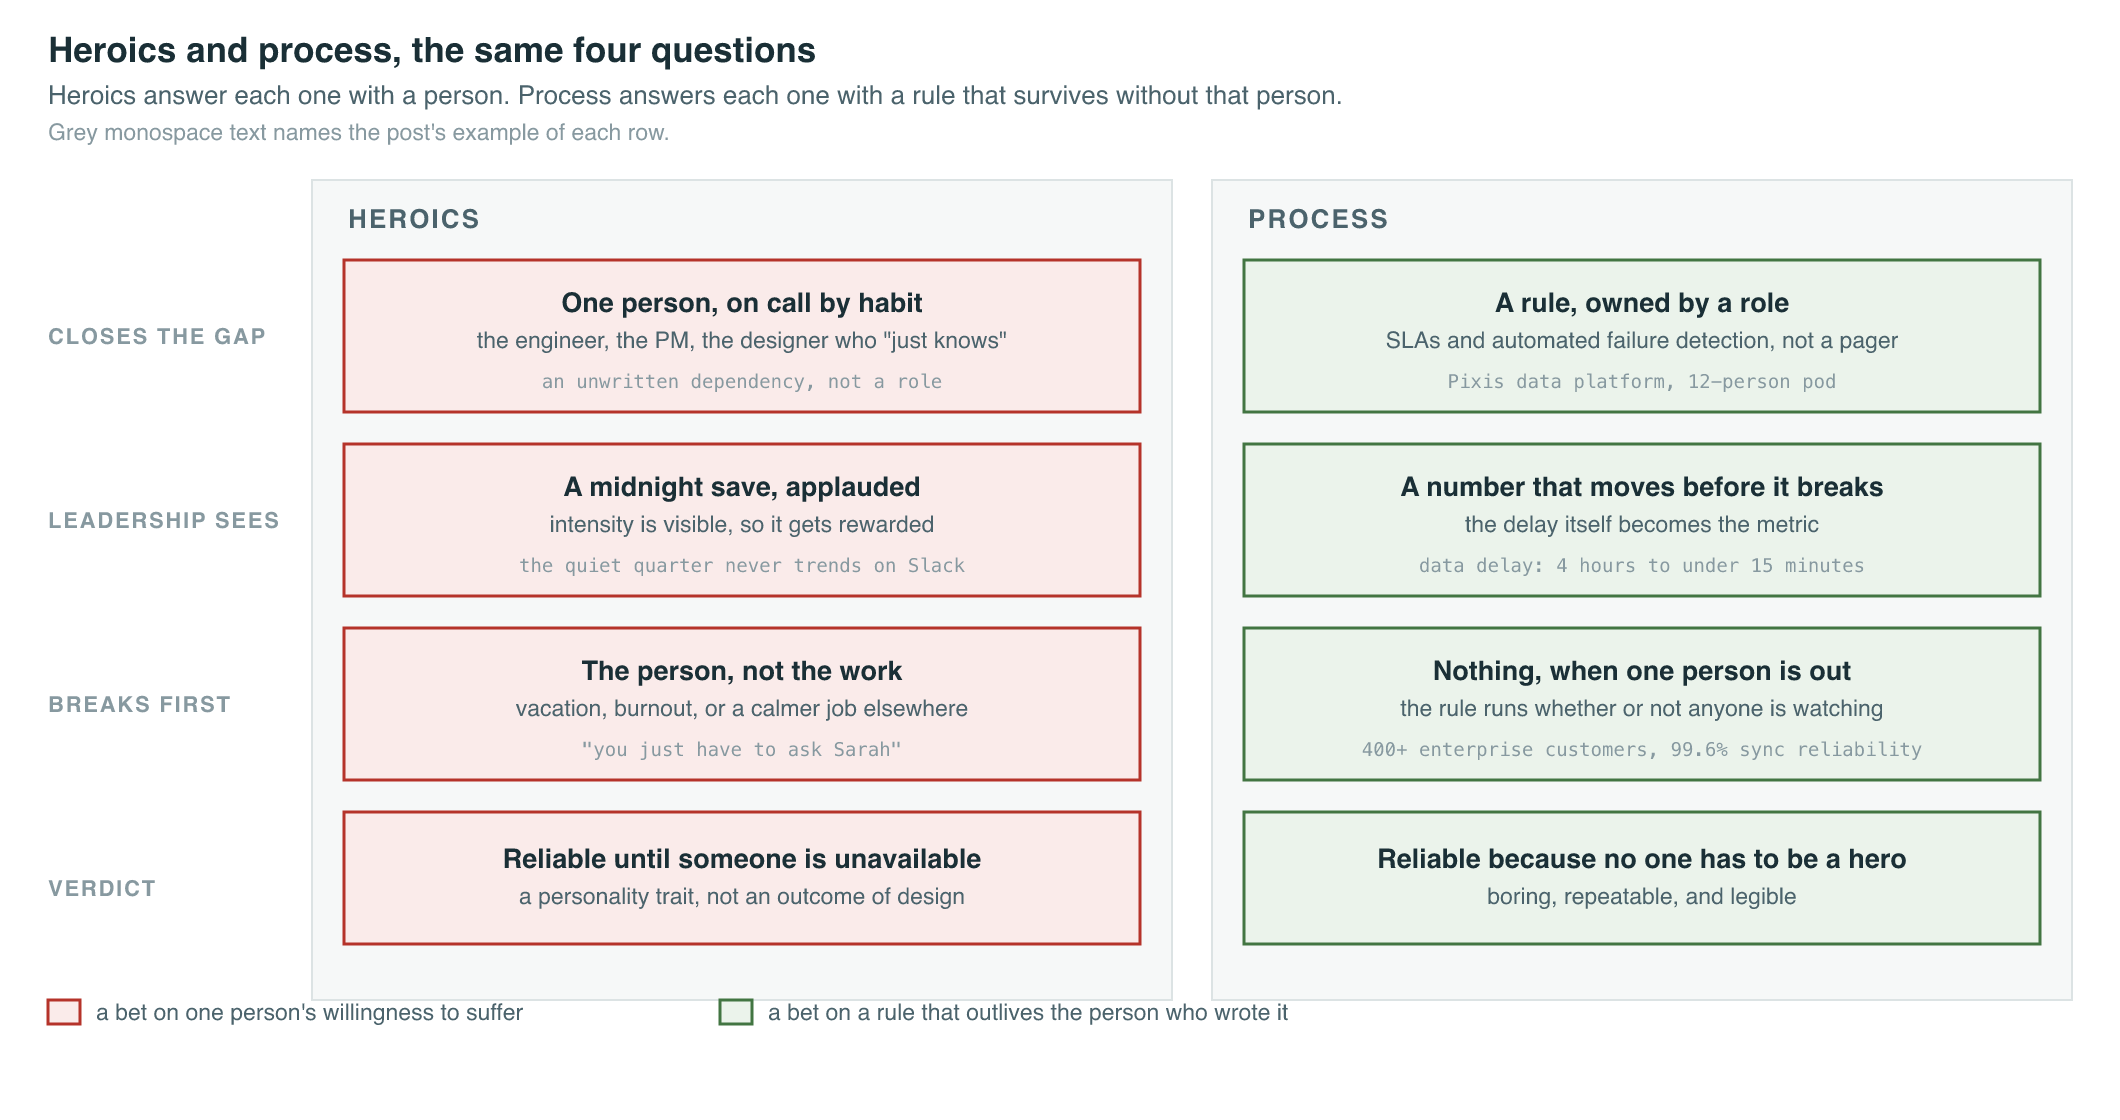
I would grade a plan that only works with one specific person available a 2/10, no matter how good that person is.
2. What process bought at Pixis that a hero never could
Teams resist process for a real reason: bureaucracy is real, and it is exhausting. Forms replace judgment. Meetings replace decisions. But bureaucracy is process without a point, and the fix for that is not heroics. It is better process.
My first mandate at Pixis was not a shiny AI layer. It was the Data Platform and Execution Engine, run by a 12-person pod with an unglamorous thesis: reliability is the product. We set platform SLAs. We automated validation and failure detection instead of asking someone to notice a broken sync at 2am. Data freshness became a target, not a hope.
The result was a number, not a story. Delay dropped from 4 hours to under 15 minutes, across 1M+ keywords a day for 400+ enterprise customers, at 99.6% end-to-end sync reliability. That number is why the recommendations riding on top of the platform were worth acting on.
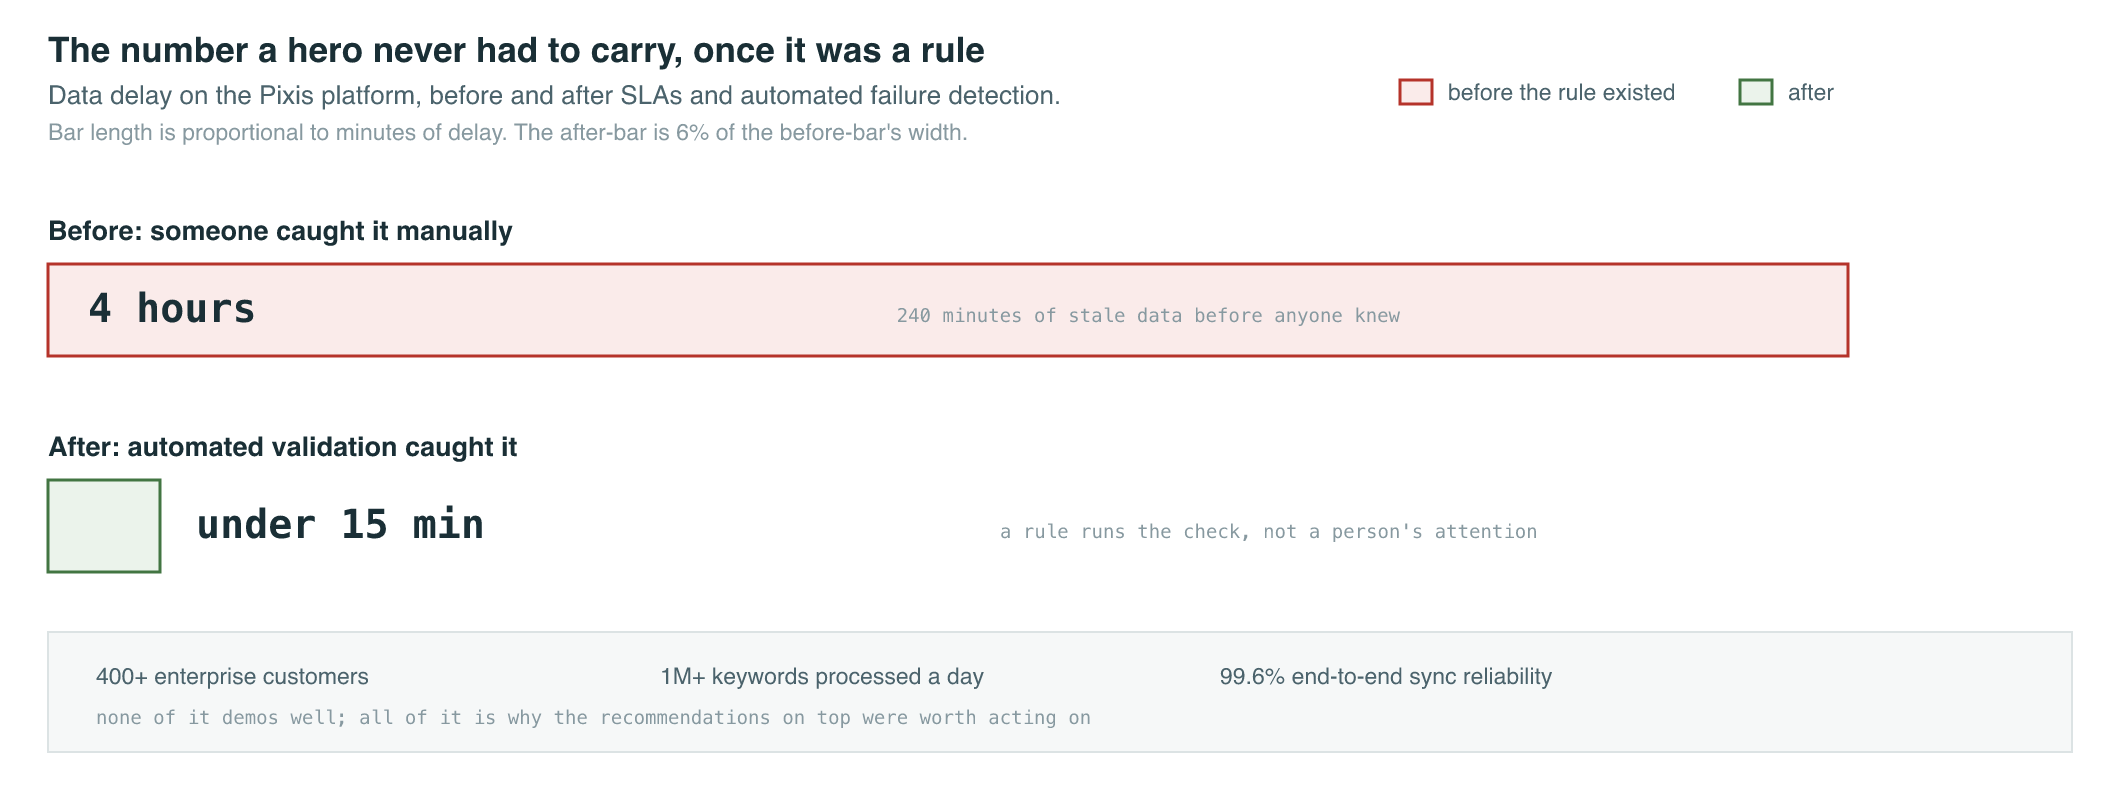
Good process speeds a team up on net. It reduces rework, and it reduces the hidden tax of a coordination that used to run through one person’s inbox. It just does not feel fast in the first quarter, while the organization stops paying interest on chaos.
3. Why organizations reward intensity and miss reliability
Intensity is visible. Reliability is invisible until the day it is tested and holds.
Leadership rewards what it can see in a crisis. The all-hands rescue gets an email of thanks. The quiet quarter where nothing broke because the SLAs held does not trend anywhere. So incentives drift. A team learns to keep a closer in its pocket. A manager learns to read calm as complacency instead of as the goal.
Once heroics stop being exceptional, they become an expectation. People stop raising risks early, because an early flag reads as pessimism, not diligence. The cliff below gets steeper every time a save covers for it.
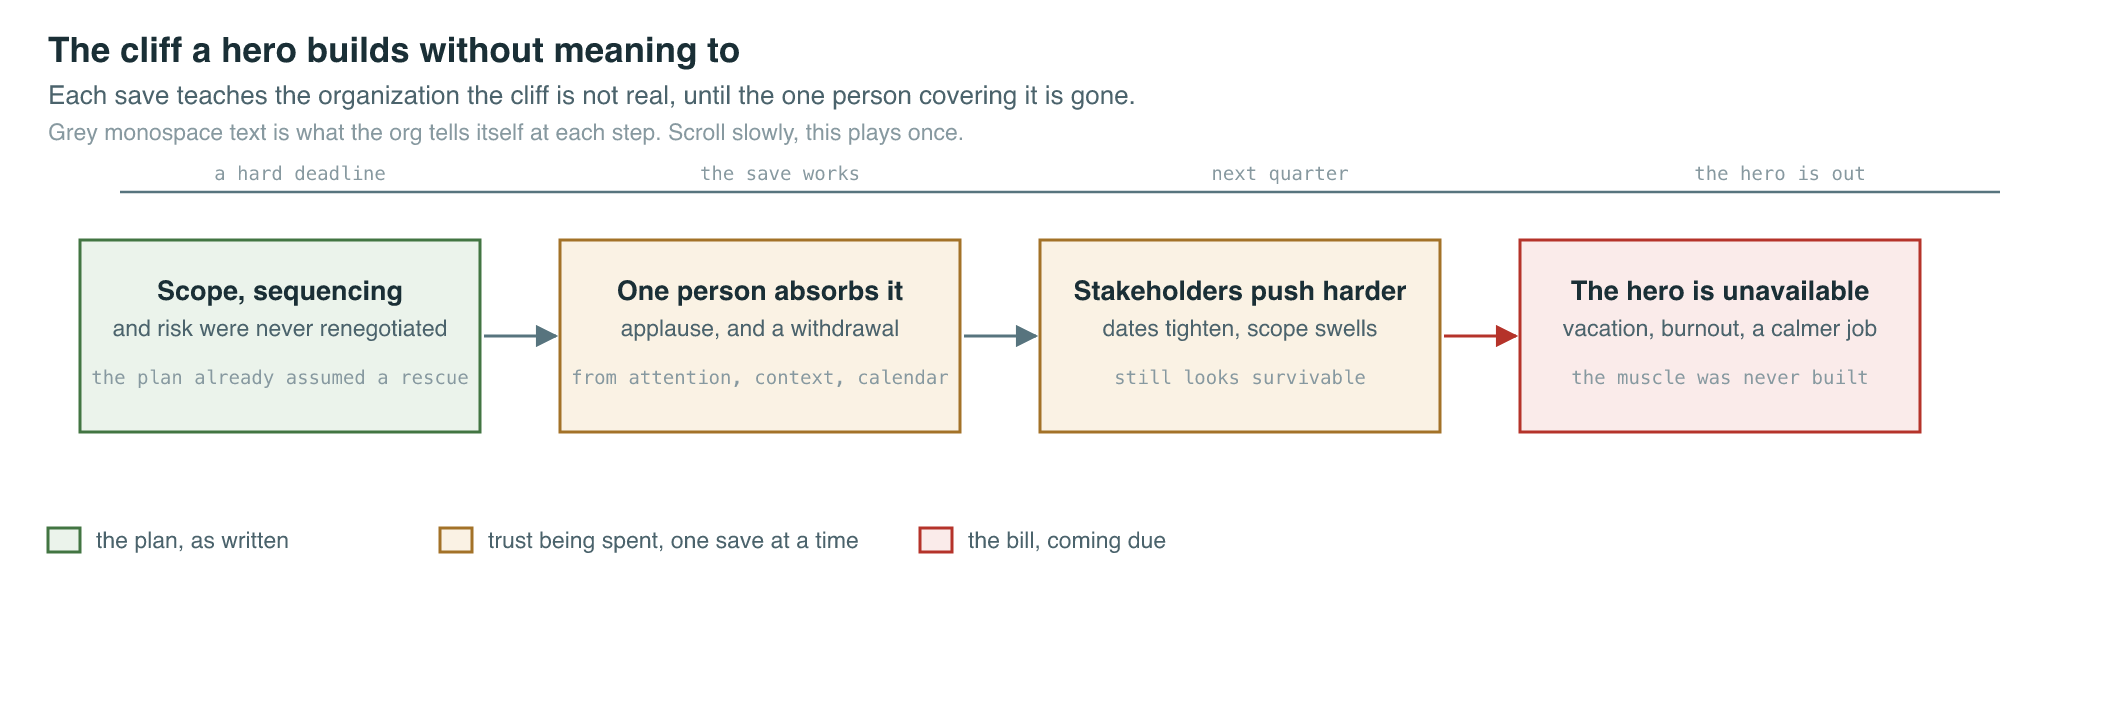
None of this is a character flaw in the hero or in leadership. It is a default nobody chose to override, running on repeat until it breaks somewhere expensive.
4. A PM absorbing every escalation is heroics with a spreadsheet
Heroics do not only show up as a midnight deploy fix. They show up as a PM who has become the human router for every dependency, and the team experiences that as responsiveness right up until it does not scale.
Every quick sync that unblocks a stuck ticket is a withdrawal from the same account: attention, context, and a calendar that fills in fifteen-minute increments. Eventually the PM is not managing a product. They are managing a queue disguised as a relationship, and every answer that should live in a decision log instead lives in one person’s memory.
The InMobi close used to be exactly this kind of queue. Finance could already see the revenue lines from 200M+ devices’ worth of daily ad events; the constraint was never visibility. The constraint was a reconciliation process that ran through people instead of through a pipeline. Once that pipeline had a target next to it, the close stopped needing anyone to route it, and the number, 5 days down to 12 hours, is re-measured 12 times a year whether anyone likes it or not.
Good process replaces a router with clarity: an owner, a written definition of done, and an escalation path that does not require knowing the right person’s phone number.
5. A customer deadline turns heroic without an honest capacity model
Heroics love a deadline tied to revenue. The account is waiting, so the team borrows against sleep and calls it commitment. That borrowing is not professionalism. It is a promise the team cannot actually keep, dressed up as one it can.
The discipline that prevents this is saying no in advance, not staying up later. At Pixis, the Prism team ran 15+ voice-of-customer interviews per launch, and that research turned into exactly 5 roadmap features, not 50. Declining the other 40 was the plan, not a failure of ambition, and it is what let the launch fund of trial-to-paid rise 25% while onboarding time fell 40%, without anyone pulling an all-nighter to hit a date.
A capacity model only works if leadership treats a declined feature as a decision, not as a missed commitment. Treat it as the second and the team quietly starts saying yes to everything again, and the deadline is heroic once more.
6. What leadership has to reward instead of the firefighter
Team-level discipline earns one good launch. The loop survives only when the organization is built to reward it. Three changes matter most.
- Ask who built the rule, not just who fixed the outage. A midnight save and a boring SLA both solve a problem; only one of them solves it twice.
- Promote the quiet quarter. If the only visible wins are rescues, the team optimizes for having something to rescue.
- Staff the pod before the crisis, not after. The 12-person team that built Pixis’s data platform existed before the reliability numbers demanded it, not because a customer escalation forced the hire.
AdRoom is the version of this that worked. The two-week onboarding sprint that seeded it, four brands, activation measured instead of logins, produced $800K ARR in two months. The full motion went from $0 to $10M ARR in five months, with a 20-person team that never needed a hero, because the sprint’s discipline was the process, not any one person’s stamina.
Takeaways
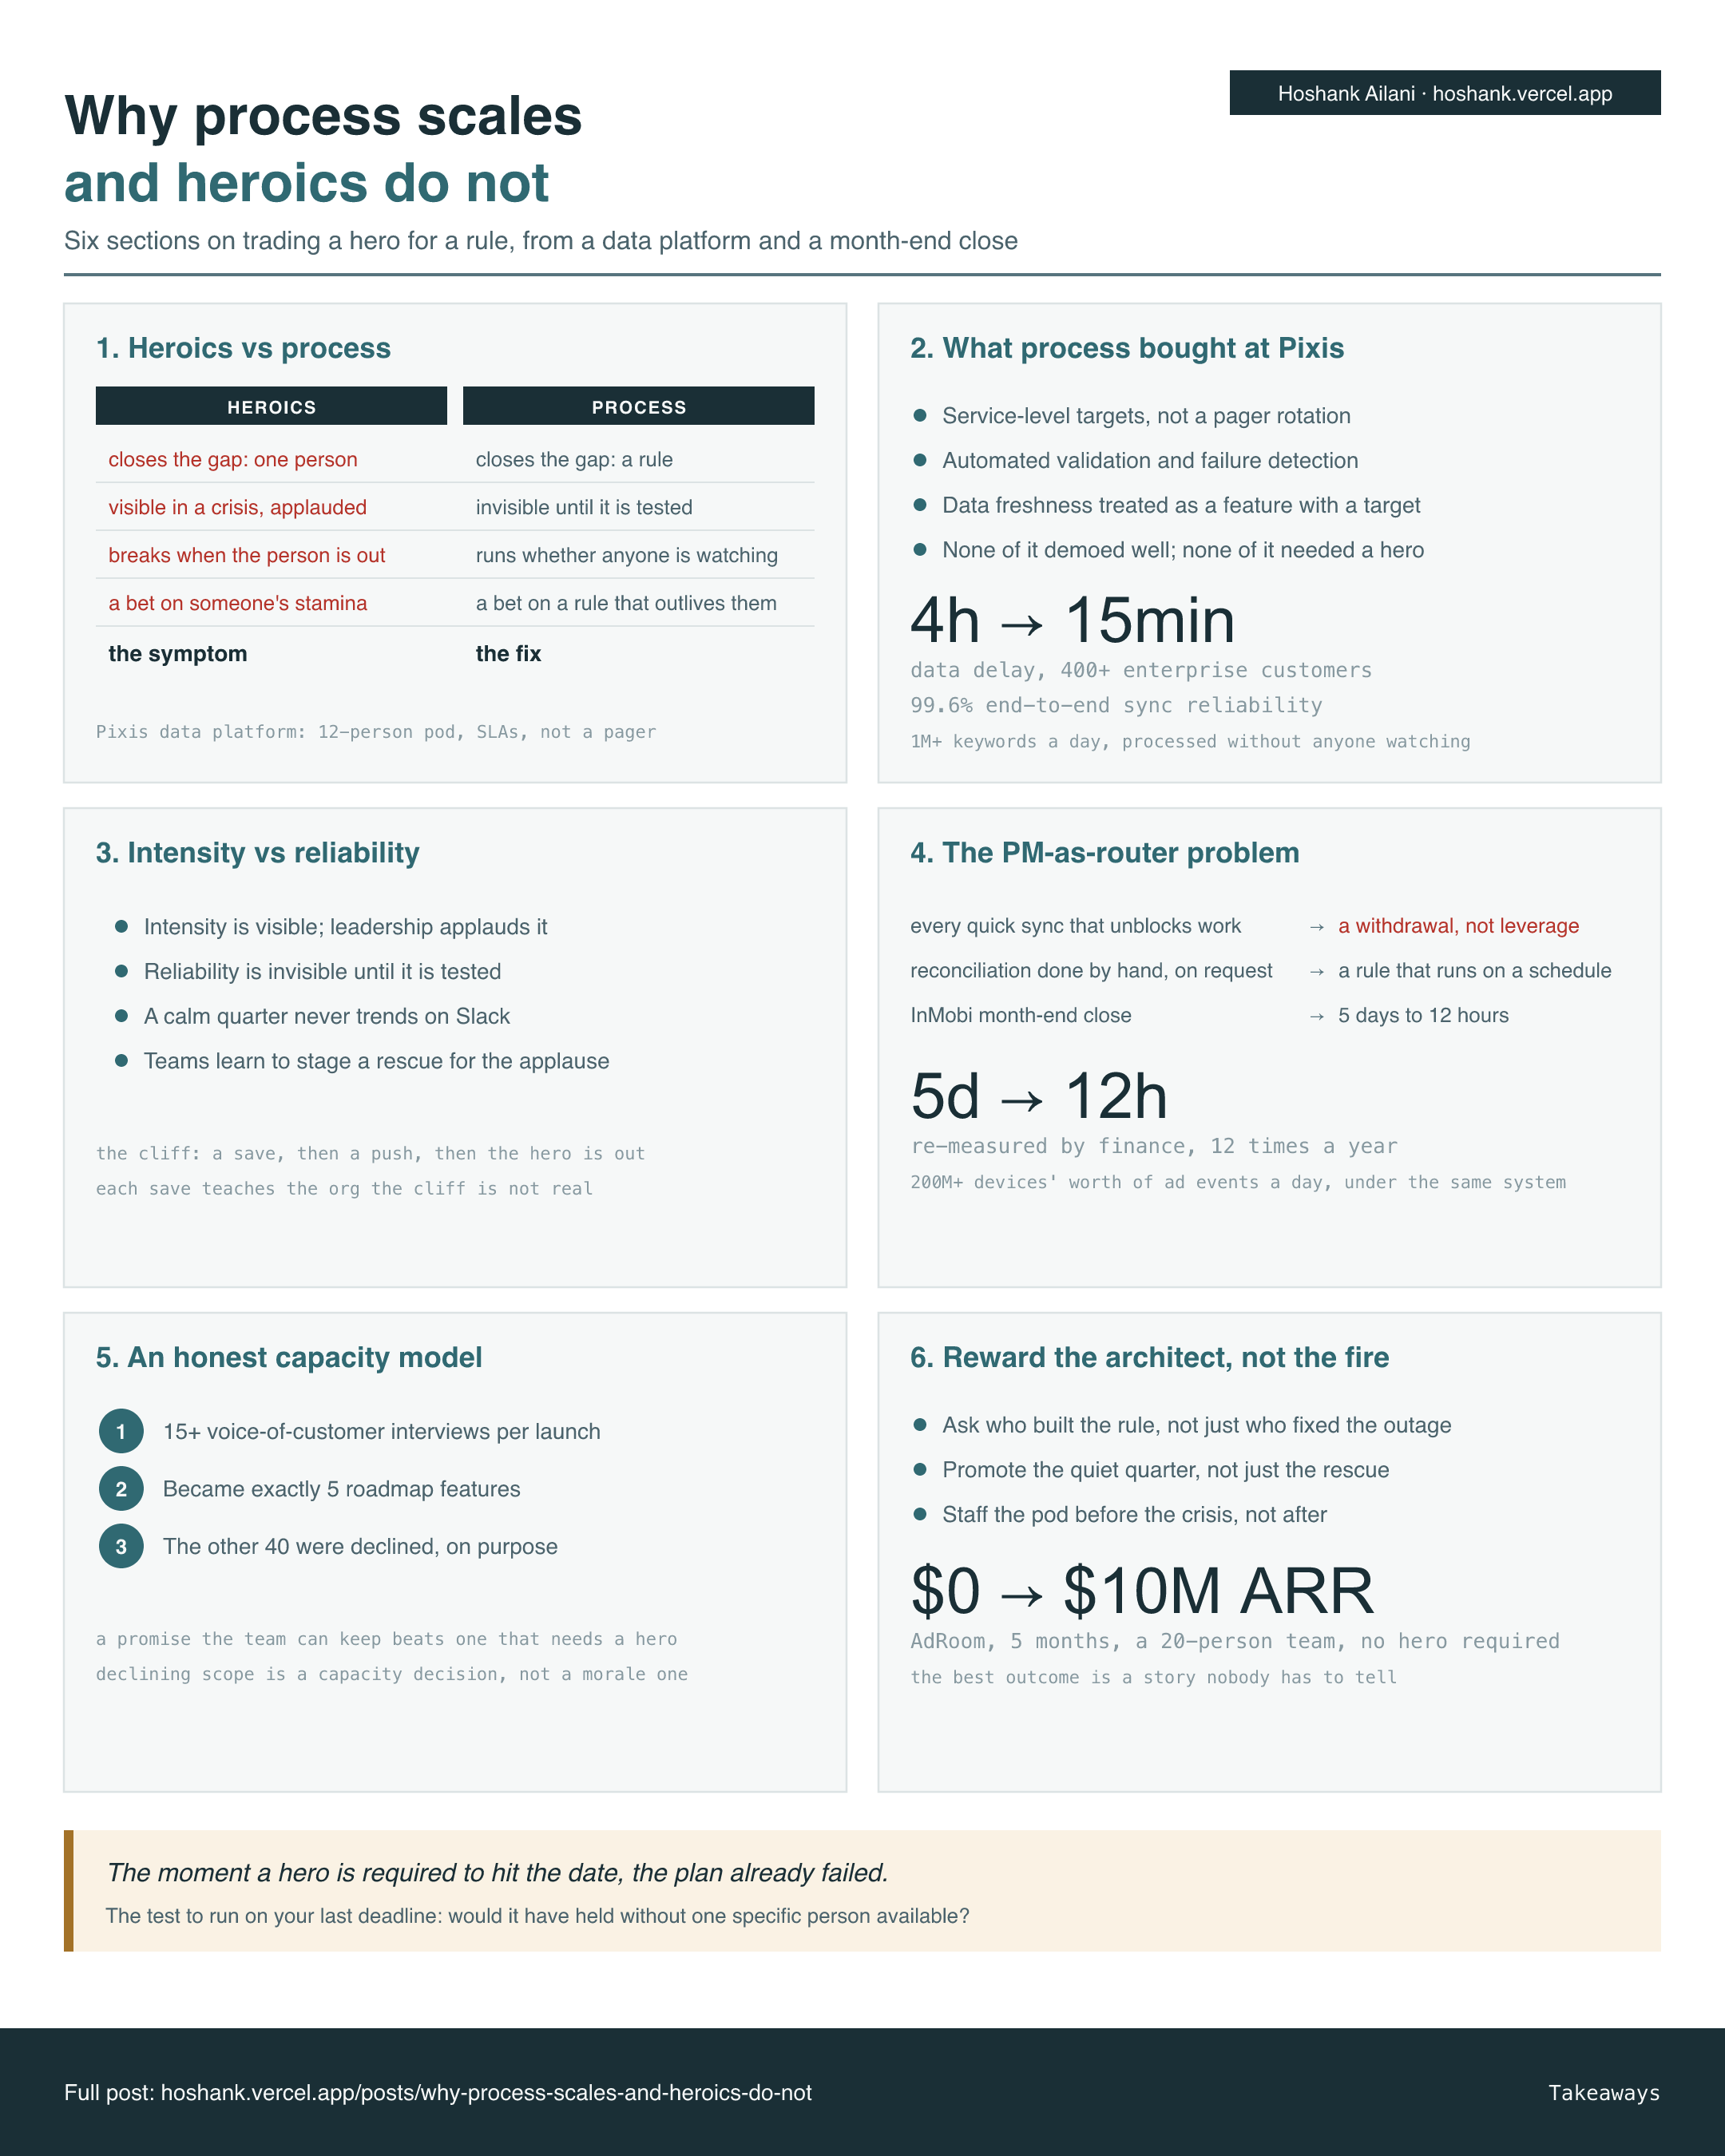
Six panels, one per section. The callout is the test to run on your team’s last deadline.
Final Words
Most teams celebrate whoever saved the launch. The better ones build a world where launches do not need saving, because dates were honest, scope was renegotiated in the open, and reliability was engineered instead of donated by one exhausted person.
Pick your team’s last close call. Ask whether it would have held if the one person who saved it had been on vacation. Write down what would have had to be a rule instead.
Reply and tell me what you found.
Cheers, Hoshank