If you ship and the metric doesn’t move, you didn’t ship.
Every team I have worked on called itself outcome-driven: supply-chain platforms at Dell, a 20-person AI creative team at Pixis, the data platform under InMobi’s ad exchange. Ask any of them what the last three features did to a number, and the room goes quiet.
I sit on the data side of that silence. At InMobi I own the system of record under a DSP and an exchange that measure ad events from 200M+ devices a day, and the month-end revenue close on that data went from 5 days to 12 hours. This post is what that work taught me about the gap between a dashboard and a measurement system.
So that’s today’s post.
Today’s Post
The difference between tracking things and knowing whether your work mattered, in six sections.
- Why a dashboard is not a measurement system
- The four reasons teams never build one
- The vanity metric trap, and the metric I picked instead
- Outputs versus outcomes, with numbers on both sides
- The four-step loop that is the actual system
- What leadership has to change for the loop to survive
1. The dashboard is not the system
Most teams confuse having metrics with having a measurement system.
Having metrics means someone set up analytics and there are charts. People look at them in the Monday meeting.
Having a measurement system means you have a disciplined process connecting what you build to what changes. You define success before you ship. You instrument the signal. You review against the definition. You decide based on what you learned.
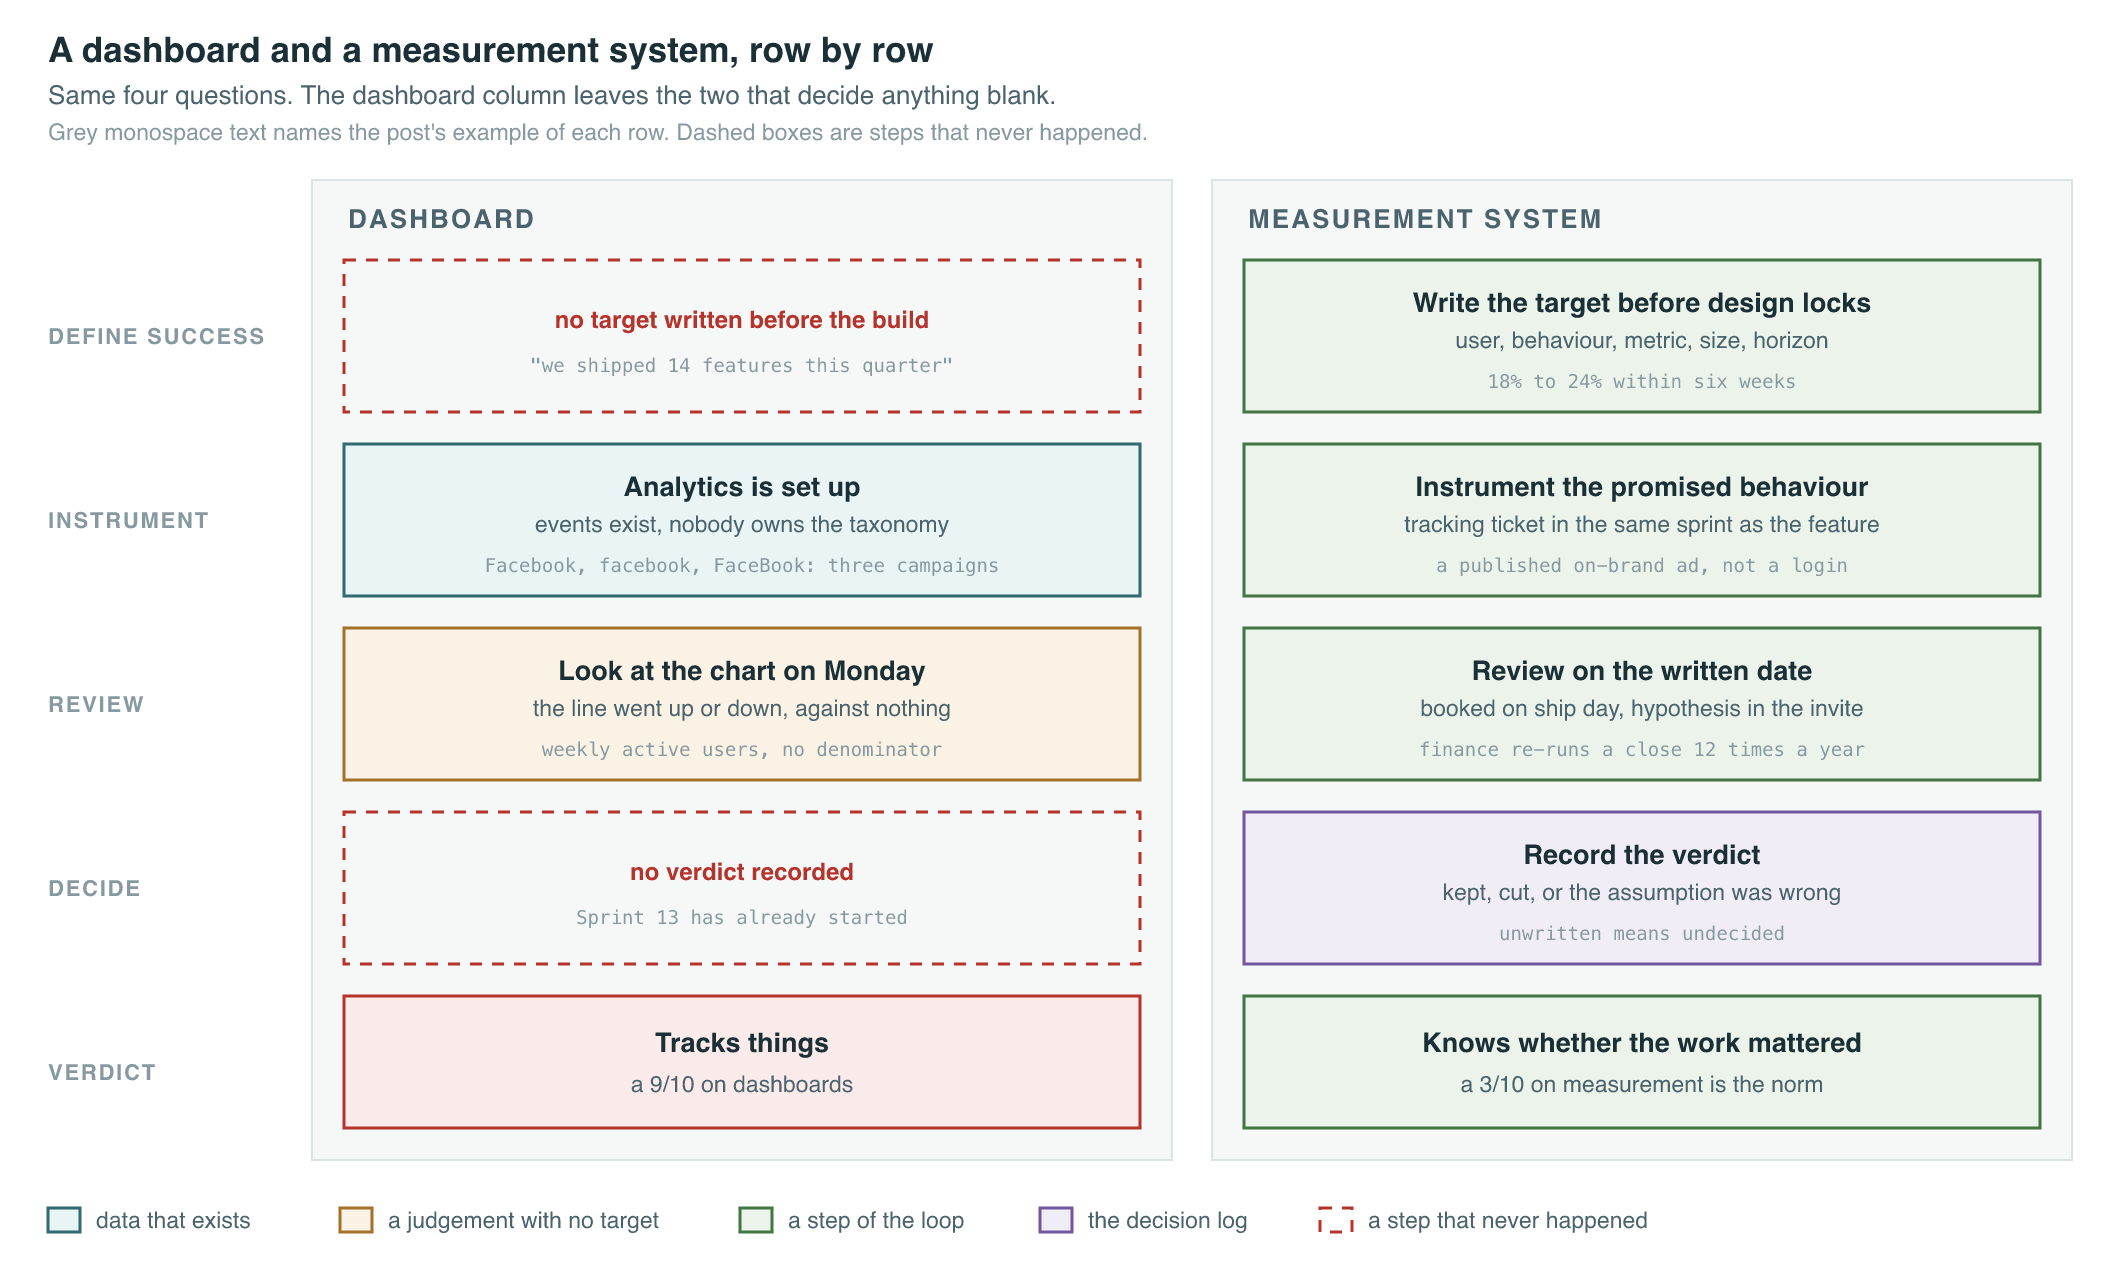
I would grade the average team a 3/10 on measurement and a 9/10 on dashboards, and the two scores have nothing to do with each other.
Here is how to read the InMobi close through that lens. Finance could already see every line of revenue from 200M+ devices’ worth of daily ad events. Dashboards were never the constraint. The system begins the moment the close has a number, days from month end to a signed figure, and a target written next to it.
The outcome today is 12 hours, down from 5 days. Review comes free here, and that is the unfair advantage. Finance runs the close every month, so the outcome is re-measured twelve times a year whether anyone likes it or not. Make your review cadence as unavoidable as a month end.
2. Why teams never build the system
The reasons are predictable and boring. I have watched all four play out at three companies.
Reason 1 - Defining success is a falsifiable claim
Falsifiable claim: “We believe this feature will lift X by Y within Z weeks.” That is a prediction, and predictions can be wrong. So most teams ship first and then hunt for a chart that went up. Anything you find that way is a story.
Compare a hypothesis from the metrics post on this site: inline role editing will cut time-to-first-invite by 20% within four weeks for admins on the Business plan. User, behavior, metric, size, horizon. Written that way, it can fail. That is the point of writing it before the first commit.
Reason 2 - Instrumentation earns no promotions
Event taxonomy: nobody gets promoted for designing one. So instrumentation is perpetually under-invested, and features ship with no way to know whether they worked.
The bill arrives later. It looks like three campaigns named Facebook, facebook and FaceBook that refuse to reconcile at quarter end. At Pixis my first mandate was the data platform under the AI, and the work that mattered most was cutting data delay from 4 hours to under 15 minutes for 400+ enterprise customers. None of it demoed well. All of it is why the recommendations on top were worth acting on.
Reason 3 - Honesty has a cost
The champion problem: measure rigorously and you will find that many features did not work. That is uncomfortable for the person who championed the feature, the team that built it, and the leader who approved it. It is much easier to not look.
Ad-tech solved this years ago. Nobody lets an ad network grade its own installs; the industry calls that marking your own homework and built an entire category, the MMP, to referee. Product teams mark their own homework every quarter and call it a launch review.
Reason 4 - Time horizons are misaligned
The team ships in Sprint 12 and starts Sprint 13 on a different problem. By the time enough data lands to judge the feature, four to six weeks later, the team has moved on. Nobody goes back because the backlog is full.
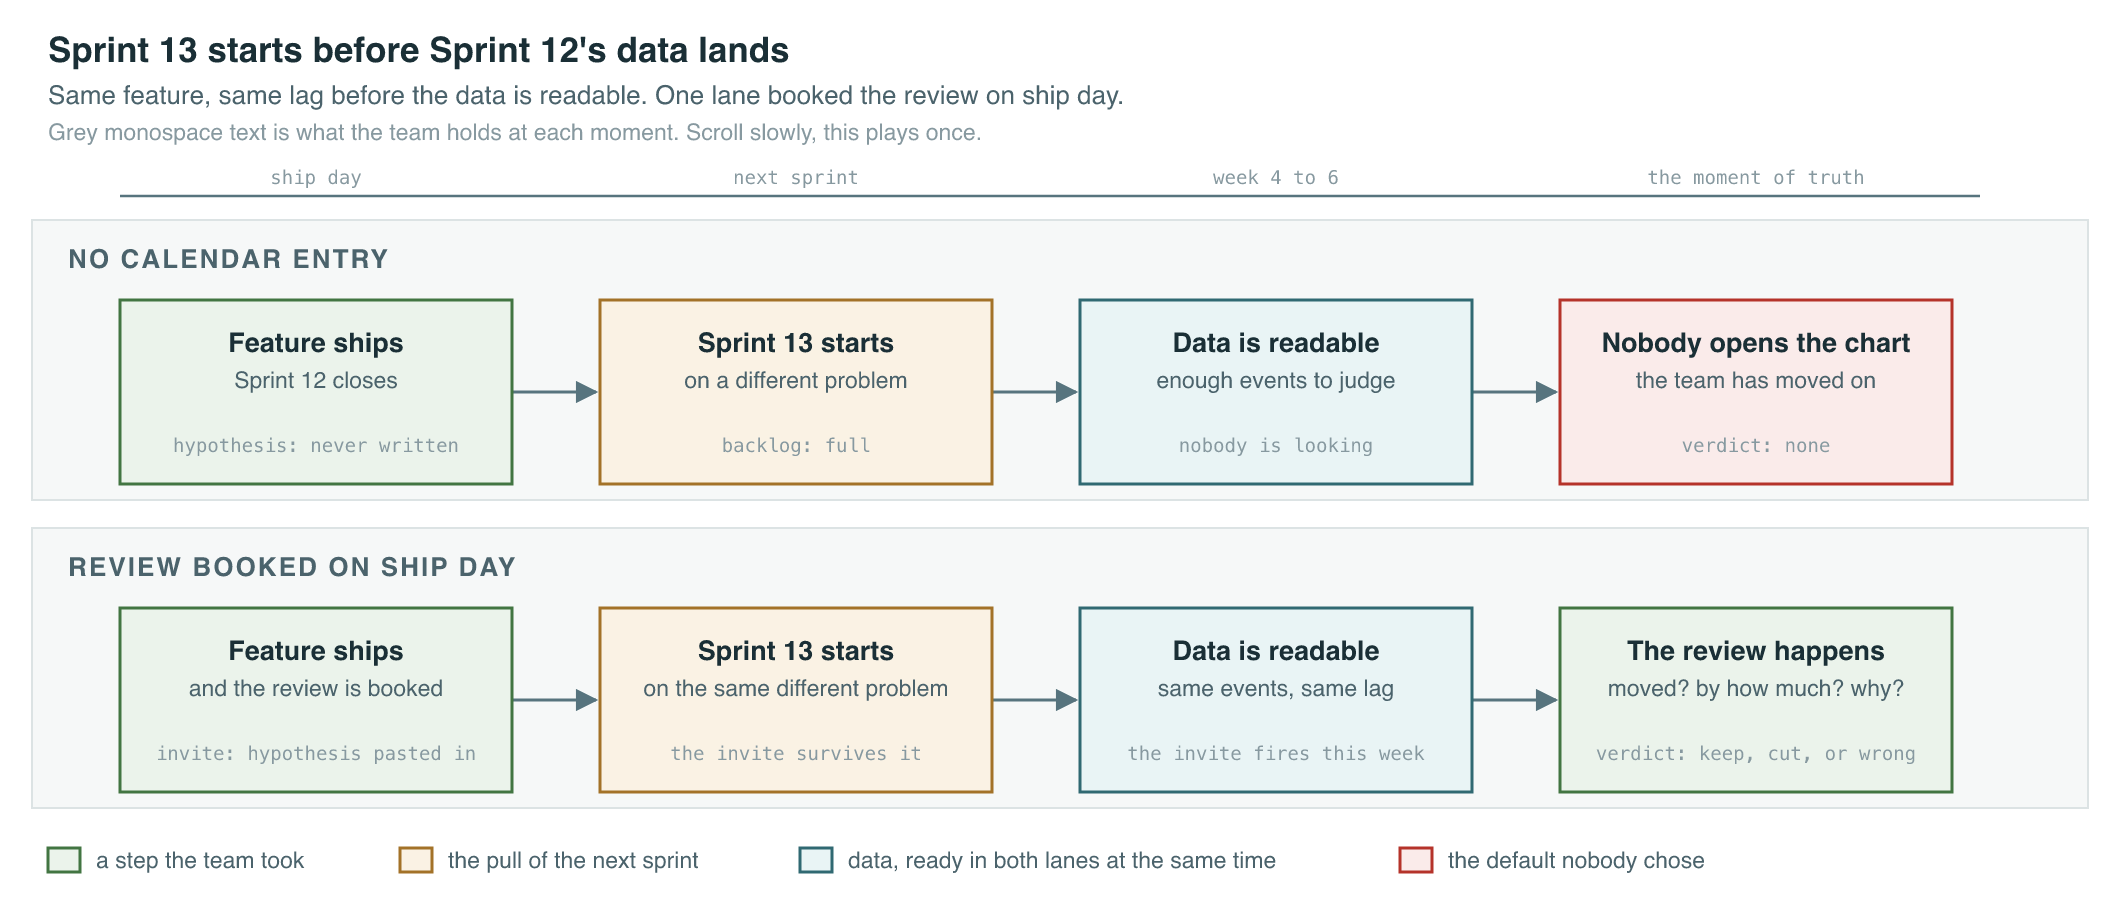
None of these is a character flaw. Each one is a default the organization never chose to override.
3. The vanity metric trap
When teams do measure, they measure usage.
A feature ships. The team watches the usage dashboard. People are using it. Success is declared.
Usage tells you the feature is visible. People use things out of curiosity, habit, lack of alternatives, or because a manager said so. Usage does not tell you the feature is working.
Here is the counter-example I lean on. At Pixis every new AdRoom brand went through a two-week onboarding sprint with one hard goal: the brand self-serving live, on-brand ads inside the window. We instrumented activation, meaning a published on-brand ad, and ignored logins. Four automotive and consumer-tech brands later, the sprint had produced $800K ARR in two months. The full motion went from $0 to $10M ARR in five months with a 20-person team.
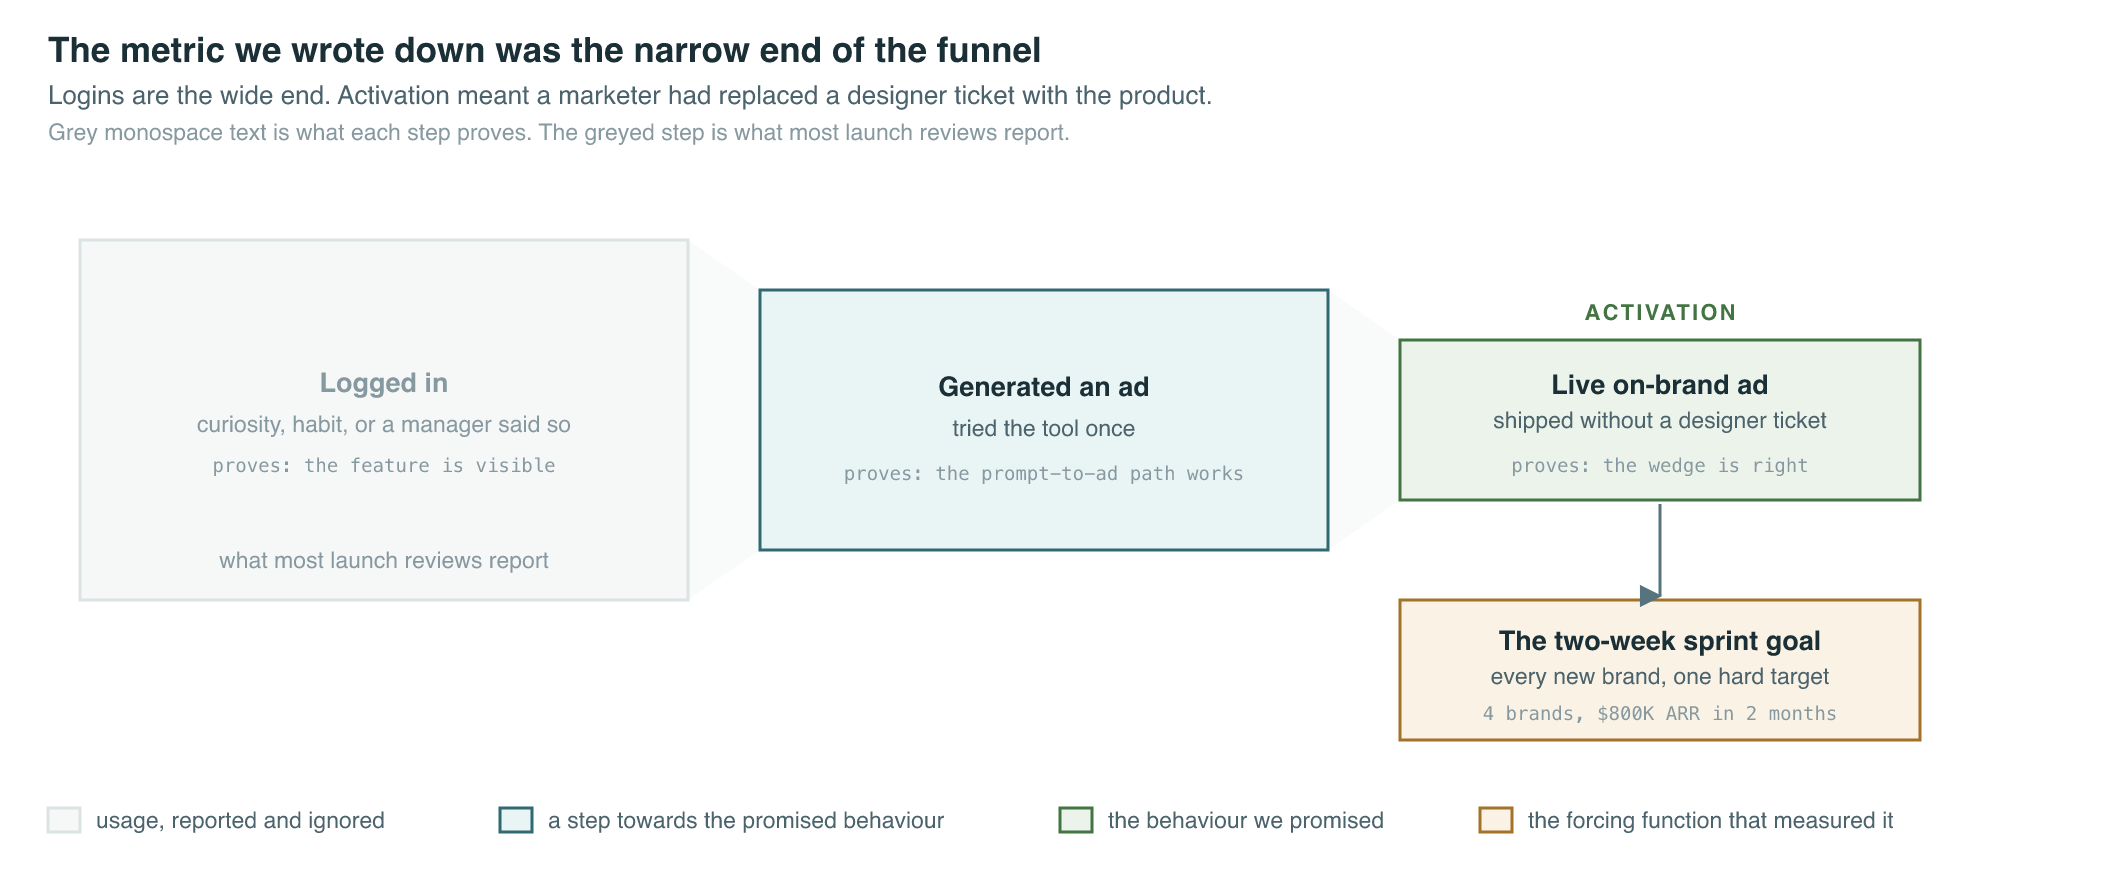
Had we counted logins, we would have declared victory in week one and learned nothing about the wedge.
The harder metrics connect usage to a change: support tickets down, time-to-completion down, retention up in one named segment. They are slower and more ambiguous. That is exactly why they are worth the trouble: they force the team to say what “working” means.
My grade for a launch review that leads with weekly active users: 3/10. I would send it back.
4. Outputs versus outcomes
Outputs are things you produce: features, releases, designs, documents. They are fully within the team’s control.
Outcomes are changes in the world: behavior shifts, revenue growth, cost reduction, a satisfied customer. They are partly within the team’s control and partly hostage to marketing, support, competitors and whether the feature solved the problem at all.
“We shipped 14 features this quarter” is a clean metric. “We improved onboarding completion by 8 points” is a messy one. Teams measure outputs because outputs are easy and controllable.
Put real numbers on both sides and the difference is obvious. At Pixis the output was Prism, a co-pilot with natural-language and voice surfaces. The outcome was +25% trial-to-paid and 40% less onboarding time. At InMobi the output is a reconciliation pipeline. The outcome is a close finance signs in 12 hours instead of 5 days.
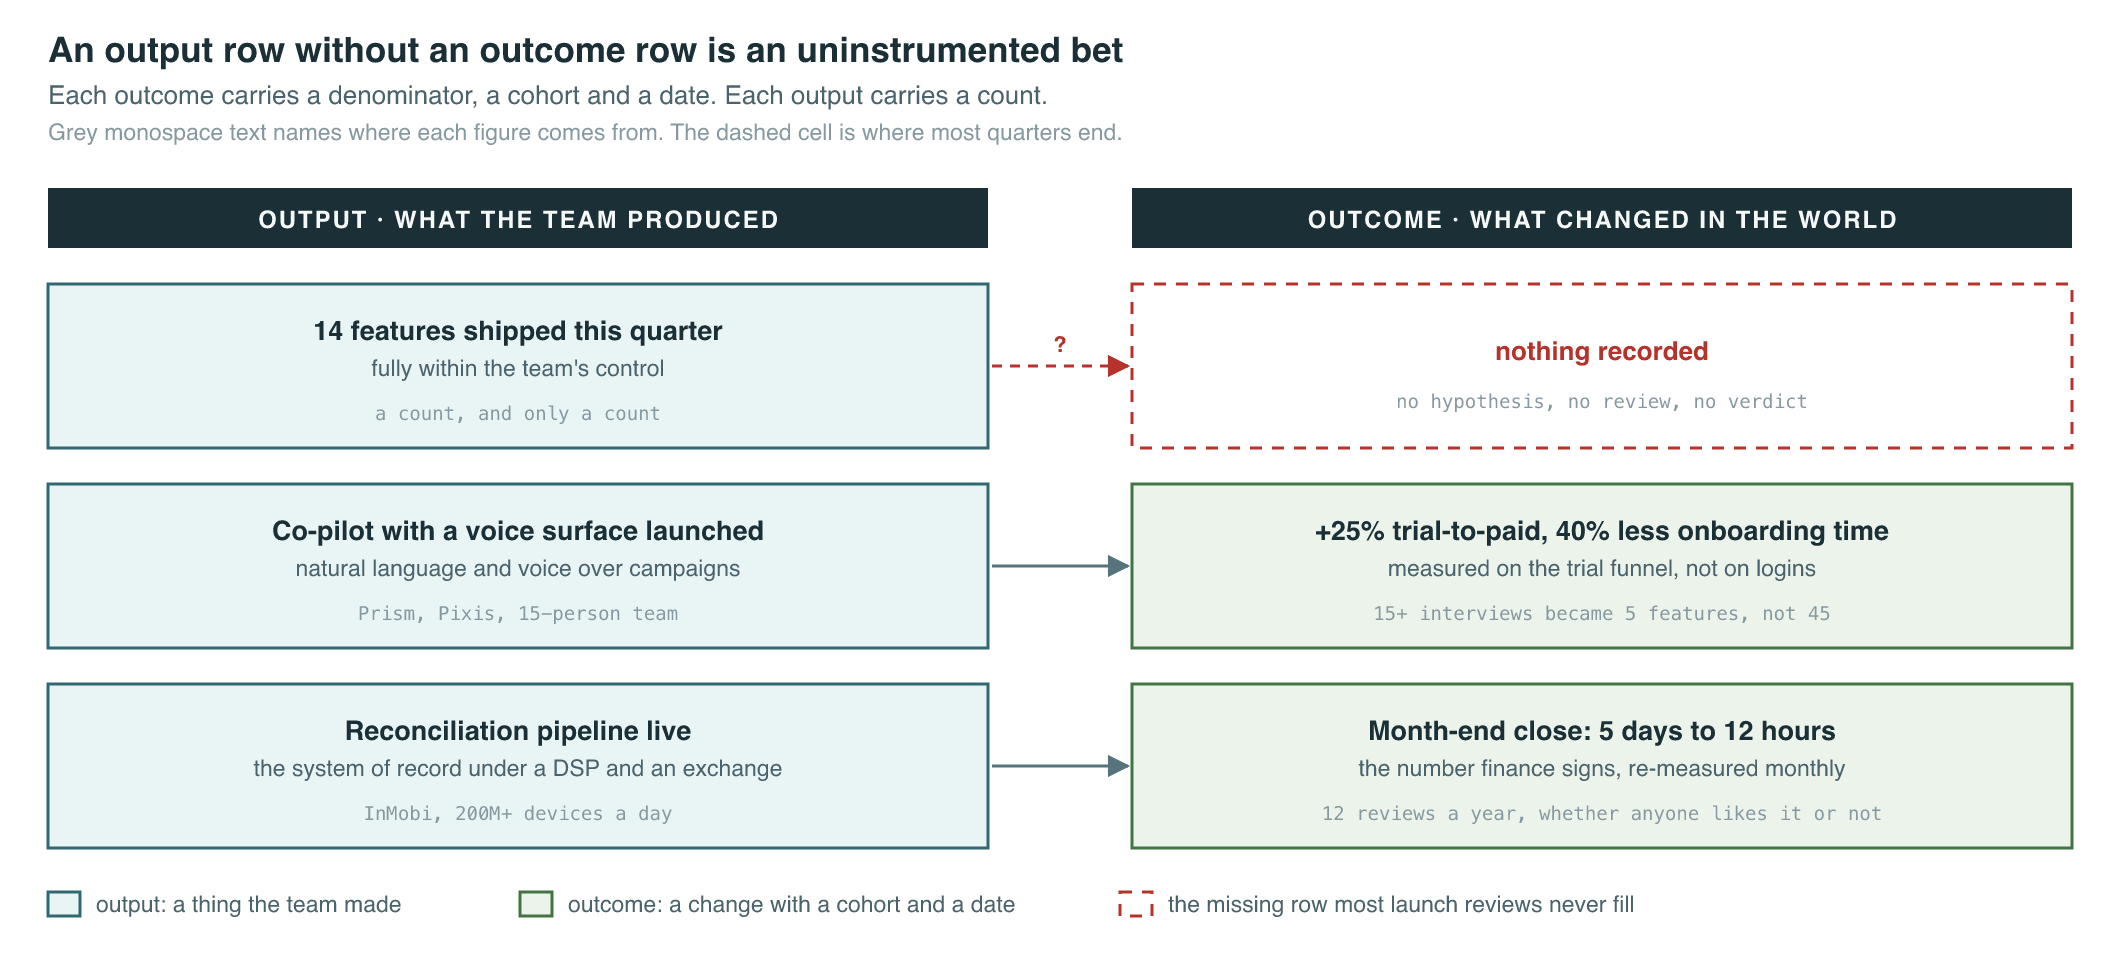
Outcome measurement means accepting responsibility for results you do not fully control. That is an uncomfortable position. It is also the only position from which product decisions improve.
5. The four-step loop
A measurement system is a set of practices. Four of them.
Step 1 - Write the hypothesis before design locks
Success hypothesis: target user, target behavior, primary metric, guardrail, time horizon, minimum detectable effect. One paragraph. The worked version on this site reads: raise the two-visit-in-fourteen-days rate from 18% to 24% within six weeks, without worsening guardrails.
If you cannot write that paragraph, you are not ready to argue for the investment.
Step 2 - Instrument during the build, as part of done
Definition of done includes event names, sampling and a dashboard skeleton. Put the tracking ticket in the same sprint as the feature. If you cannot measure whether it worked, do not ship it. Or say out loud that you are making an uninstrumented bet, and put that sentence in the launch doc.
Step 3 - Review on the date you wrote down
Outcome review: did the metric move, by how much, within the horizon, and if not, why. Separate execution failures (bugs, slow rollout) from assumption failures (users did not want it). Book it the day you ship, with the hypothesis pasted into the invite, because Sprint 13 will not leave room for it otherwise.
The review is also where you learn whether the move came from your change or from something else in the same window. On the InMobi close, that question reads: what else landed in the months the number fell?
Step 4 - Record the verdict
Decision log: a structured history of what you believed, what you tried and what happened. This is the most valuable asset a product team owns. My own rule from the home page applies here: unwritten means undecided.
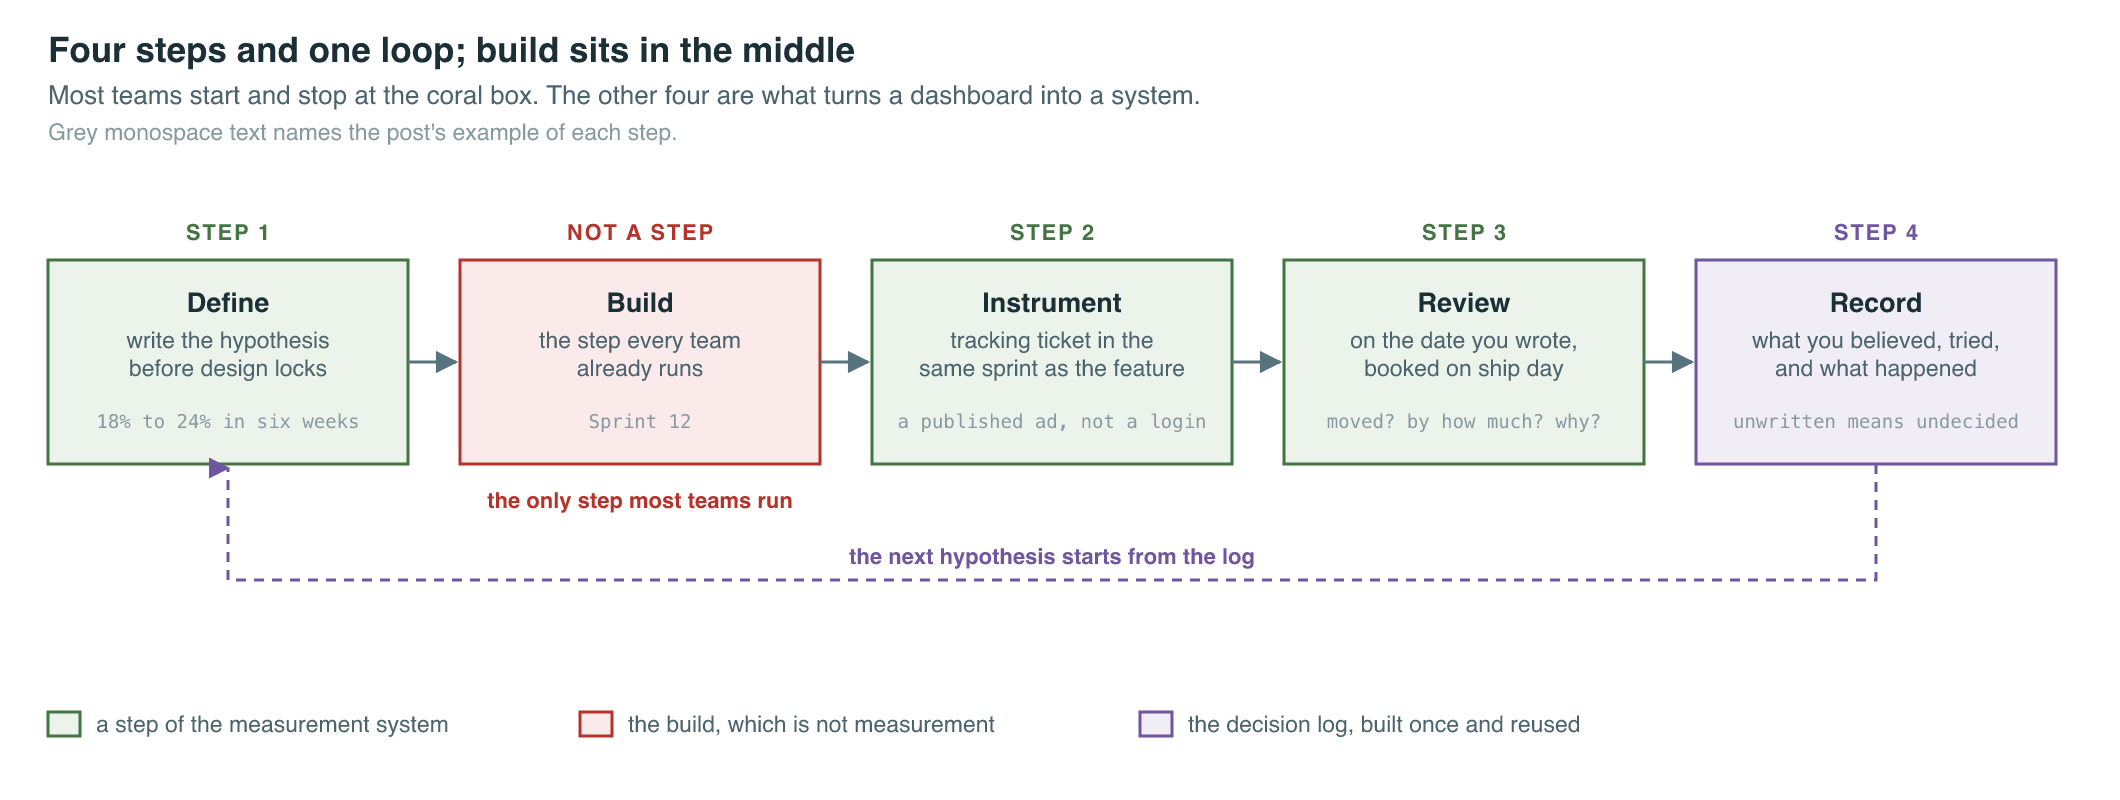
Most teams run only the build. No hypothesis, no instrumentation, no review, no record.
6. What leadership has to change
Team-level initiative gets you one good launch. The loop survives only when the organization is designed for it. Four changes.
- Ask “did it work?”: at every review, alongside “did it ship?” If leadership celebrates launches, the team optimizes for launching.
- Put outcome reviews on the calendar: sprint demos and quarterly planning give the team no structural moment to check results. A six-week review per launch does.
- Reward the kill: if a PM is penalized for killing a feature the data condemned, they stop killing features, and the product accumulates dead weight.
- Tolerate “we were wrong”: if admitting a failed bet is career-damaging, nobody measures honestly, and the whole system is theater.
The saying-no half is where I have seen this work. At Pixis, 15+ voice-of-customer interviews on the Prism launch became exactly five roadmap features. The discipline was declining the other forty. That only happens when a leader treats a killed idea as evidence, and evidence as a win.
One habit makes all four easier: keep the customer in the room. I run 15+ interviews per launch, every launch. Once fifteen people have described the problem to you, “did it work?” stops being abstract.
Takeaways
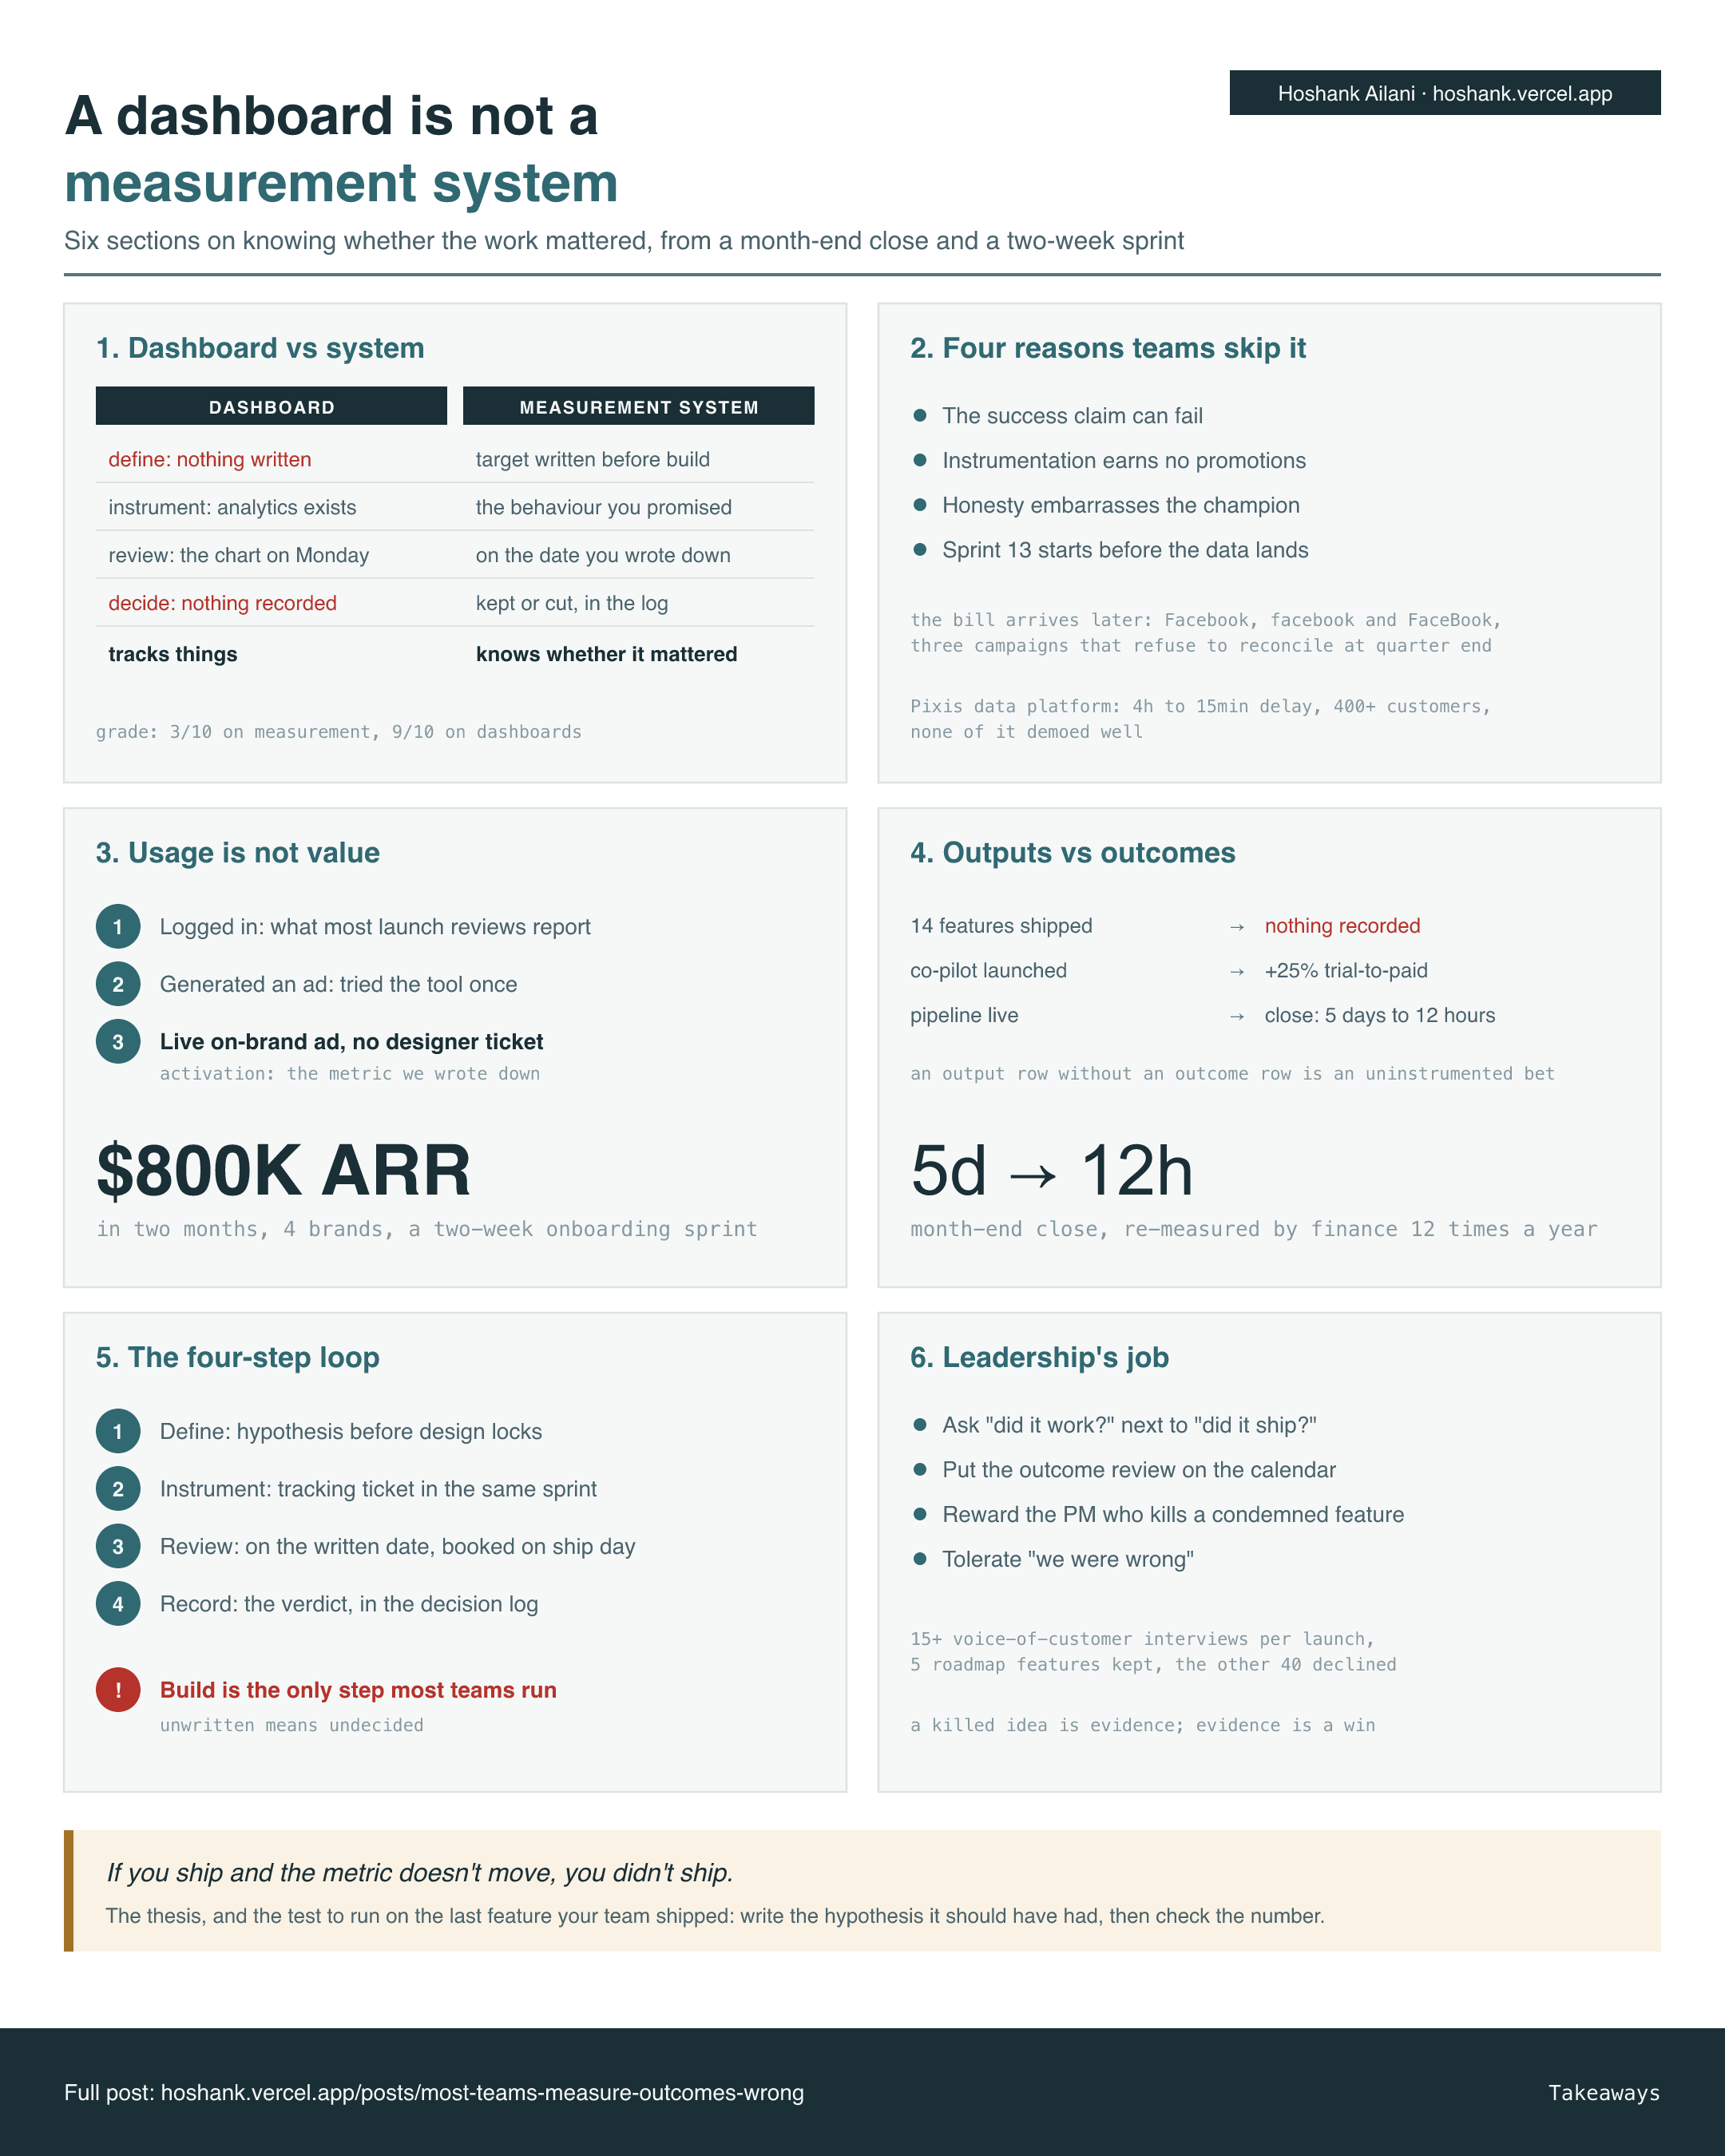
Six panels, one per section. The callout is the thesis, and the test to run on the last feature your team shipped.
Final Words
Most teams have the tools, the data and the dashboards. What they lack is the loop: a definition of success before the build, and a review on the date they promised. Pick the last feature your team shipped, write the hypothesis it should have had, and check the number this week.
Reply and tell me what you found. I am collecting the misses for a follow-up.
Cheers, Hoshank