The bug that shipped last month was written into the roadmap eighteen months ago.
Every postmortem I have sat through at InMobi, Pixis, and Dell names the same kind of cause: a bad estimate, a missed edge case, a customer who churned in week three. Nine years into product work across those three companies, I have learned to distrust that name. The real fork is usually two or three decisions back, and nobody wrote it down.
At Pixis, I own the decision that let a team kill a manual QA gate for good, and the decision that made killing it safe was made months earlier, for a different reason entirely. This post is about the gap between those two moments, the question that closes it, and a fourth-order example still resolving on a product I shipped this month.
So that’s today’s post.
Today’s Post
The question that turns a guess into a chain, and the four reasons organizations refuse to ask it, in six sections.
- Why the postmortem stops at the last click
- The question, asked twice: “and then what?”
- Why organizations punish the people who see the next ripple
- A decision still paying rent four steps later, on a product live today
- Reactive product management versus strategic product management
- What leadership has to change for the discipline to survive
1. The postmortem that stops at the last click
Most postmortems name the last click: a wrong estimate, a slow rollout, a customer who churned in week three. Ask what made that click cheap, and the room goes quiet.
Churn is rarely the first fork. It is usually the third or fourth, downstream of a packaging call, an onboarding shortcut, or a support commitment nobody costed at the time. The measurement post on this site covers the review half of this problem: define success, instrument, review, record. This post is about the fork upstream of all four, the decision that made the eventual review necessary in the first place.
My own rule from the home page applies here too: unwritten means undecided. A team that cannot point to the fork two quarters back is not learning from its postmortem. It is narrating one.
2. The question, asked twice: “and then what?”
The practice is one question, asked twice. For any decision that ships, ask what it changes beyond the metric on the slide that approved it. The first answer is usually obvious. The second is where the real trade lives.
At Pixis, the first-order decision on AdRoom was narrow: enforce brand guidelines at generation time, not after a human check. First answer to “and then what”: the manual QA gate that used to sit between a marketer and a live ad could go. Second answer: designer workload dropped 80% company-wide, and marketers using AdRoom stopped routing work back through design at all.
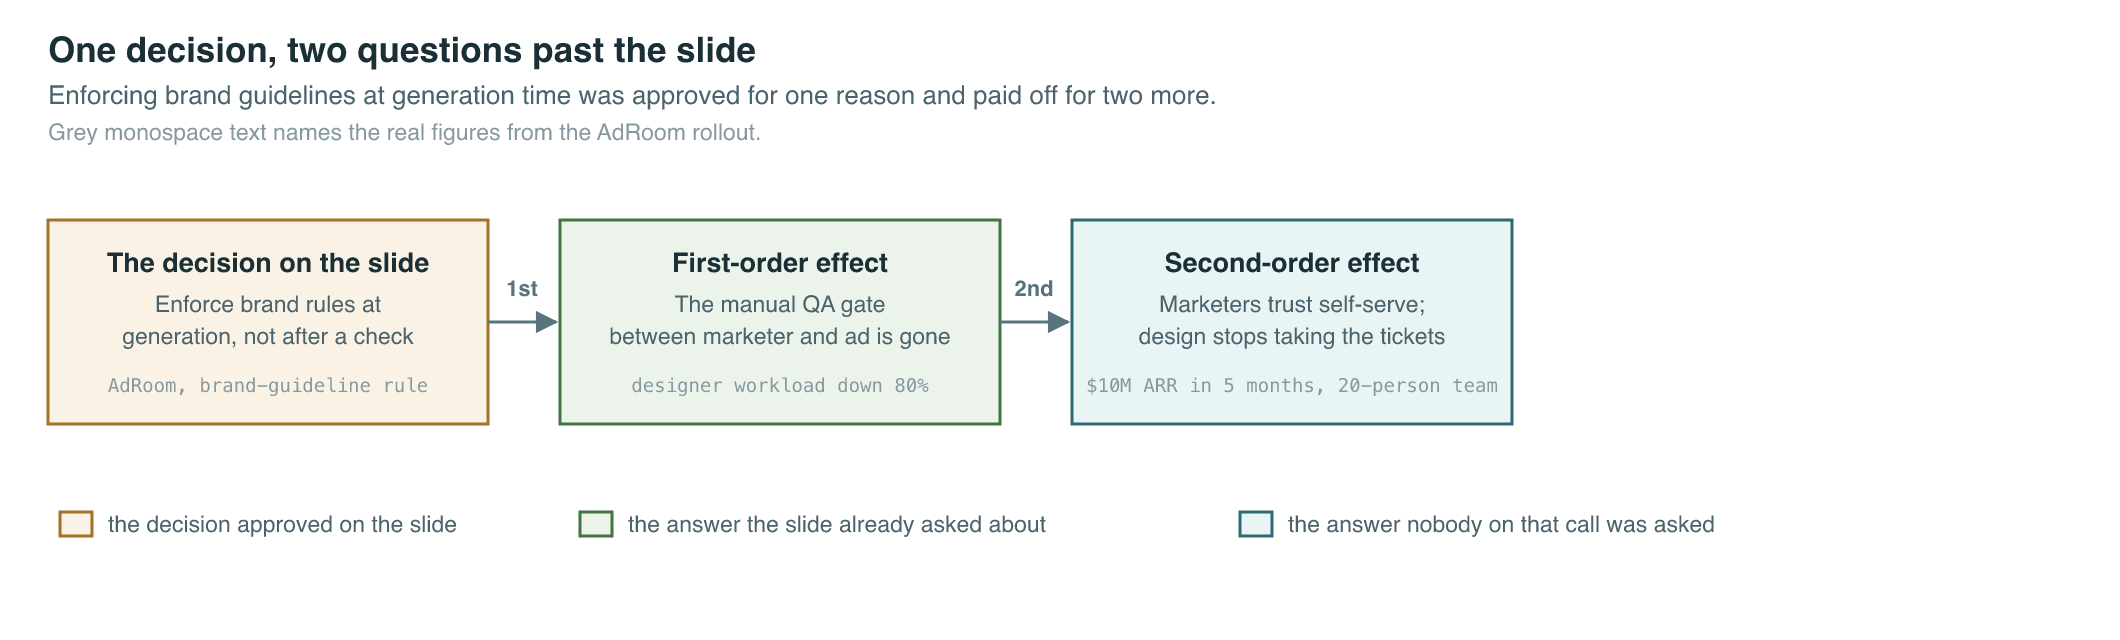
Neither the 80% figure nor the trust shift showed up on the slide that approved the brand-guideline rule. Four automotive and consumer-tech brands into the rollout, the same decision had already produced $800K ARR in two months, and the wider motion ran to $10M ARR in five months with a 20-person team. None of that traces to the AI model underneath AdRoom. It traces to the fork about where the check happens.
3. Why organizations punish the people who see the next ripple
Second-order thinking should be common if it is this valuable. Four forces keep it rare.
It is slower in the room. A leader wants a recommendation crisp enough to fit a thirty-second slide. A second-order answer sounds like a preamble with contingencies attached, even when the person raising it is right.
It is harder to explain upward. A first-order story maps cleanly onto a hero arc: we saw a problem, we shipped, it worked. A second-order story implicates a hiring plan or a roadmap quarter that has not happened yet.
It costs something to say out loud. At Pixis, fifteen-plus voice-of-customer interviews on the Prism launch surfaced 55 requested features. Five made the roadmap. The discipline was declining the other 40, in front of the customers who asked for them, and that is not a comfortable Tuesday for anyone in the room.
Accountability is misaligned. The person who approves the first-order win rarely owns the third-order bill. By the time the bill lands, the champion has rotated roles, and the retro calls it “execution.”
4. A decision still paying rent four steps later
Some chains run long enough that you can watch every link resolve on a real product, live today. VocalApply, a voice agent I built this month to fill out job applications by conversation, is one.
The first-order decision was architectural: no backend holds the applicant’s data, so the app runs on WebMCP calls straight from the browser. Second order: a browser cannot hold an API key safely, so the app needs a way to reach a voice model without ever shipping that key to the page. Third order: OpenAI’s Realtime path has an answer, a server mints a token that expires in minutes, so the audio still never crosses a server I control. Fourth order: Gemini Live has no equivalent path on that same kind of socket. Every combination of a minted token, a key, and an API version was tried, and each one closes with error 1008, “unregistered callers.”
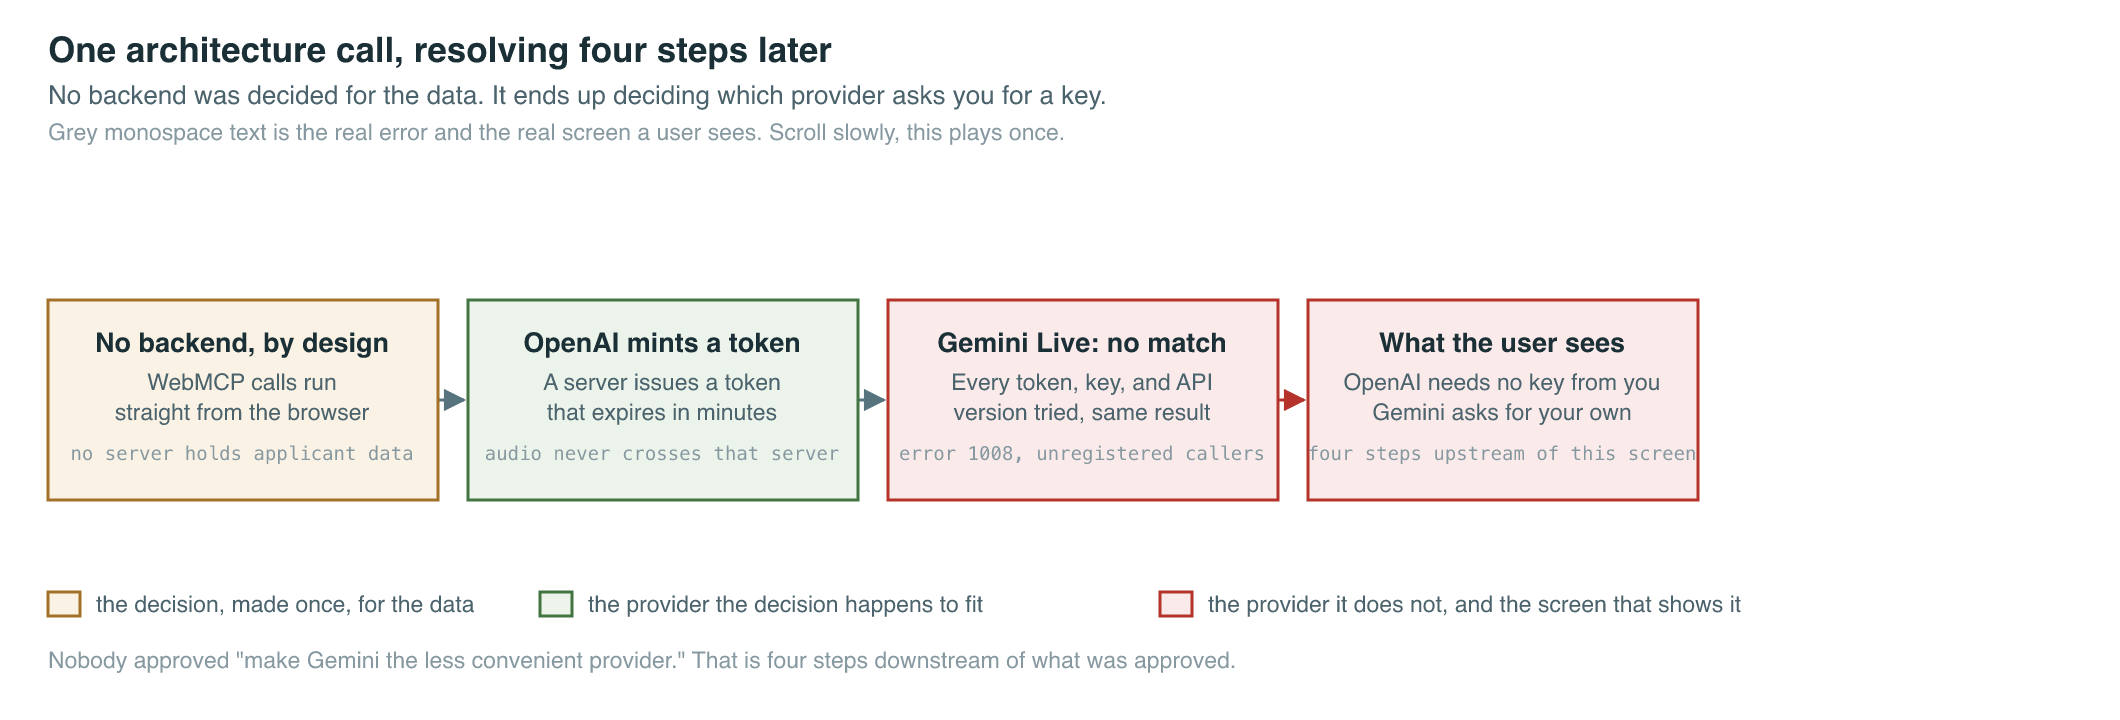
The decision made at the start of the build resolves onto the fourth screen a user sees: Gemini asks the reader for their own key, and OpenAI does not. That difference is documented on VocalApply’s own project page rather than smoothed into a changelog line, because the honest version is more useful than the tidy one.
5. Reactive product management versus strategic product management
Reactive product management treats a constraint as a command. The customer is loud, the quarter is ending, the lever closest to the pain gets pulled, and it works, once.
Strategic product management treats the same constraint as data. It still ships on the same clock. It asks what kind of team and what kind of product this decision manufactures six months out, before agreeing to pull the lever.
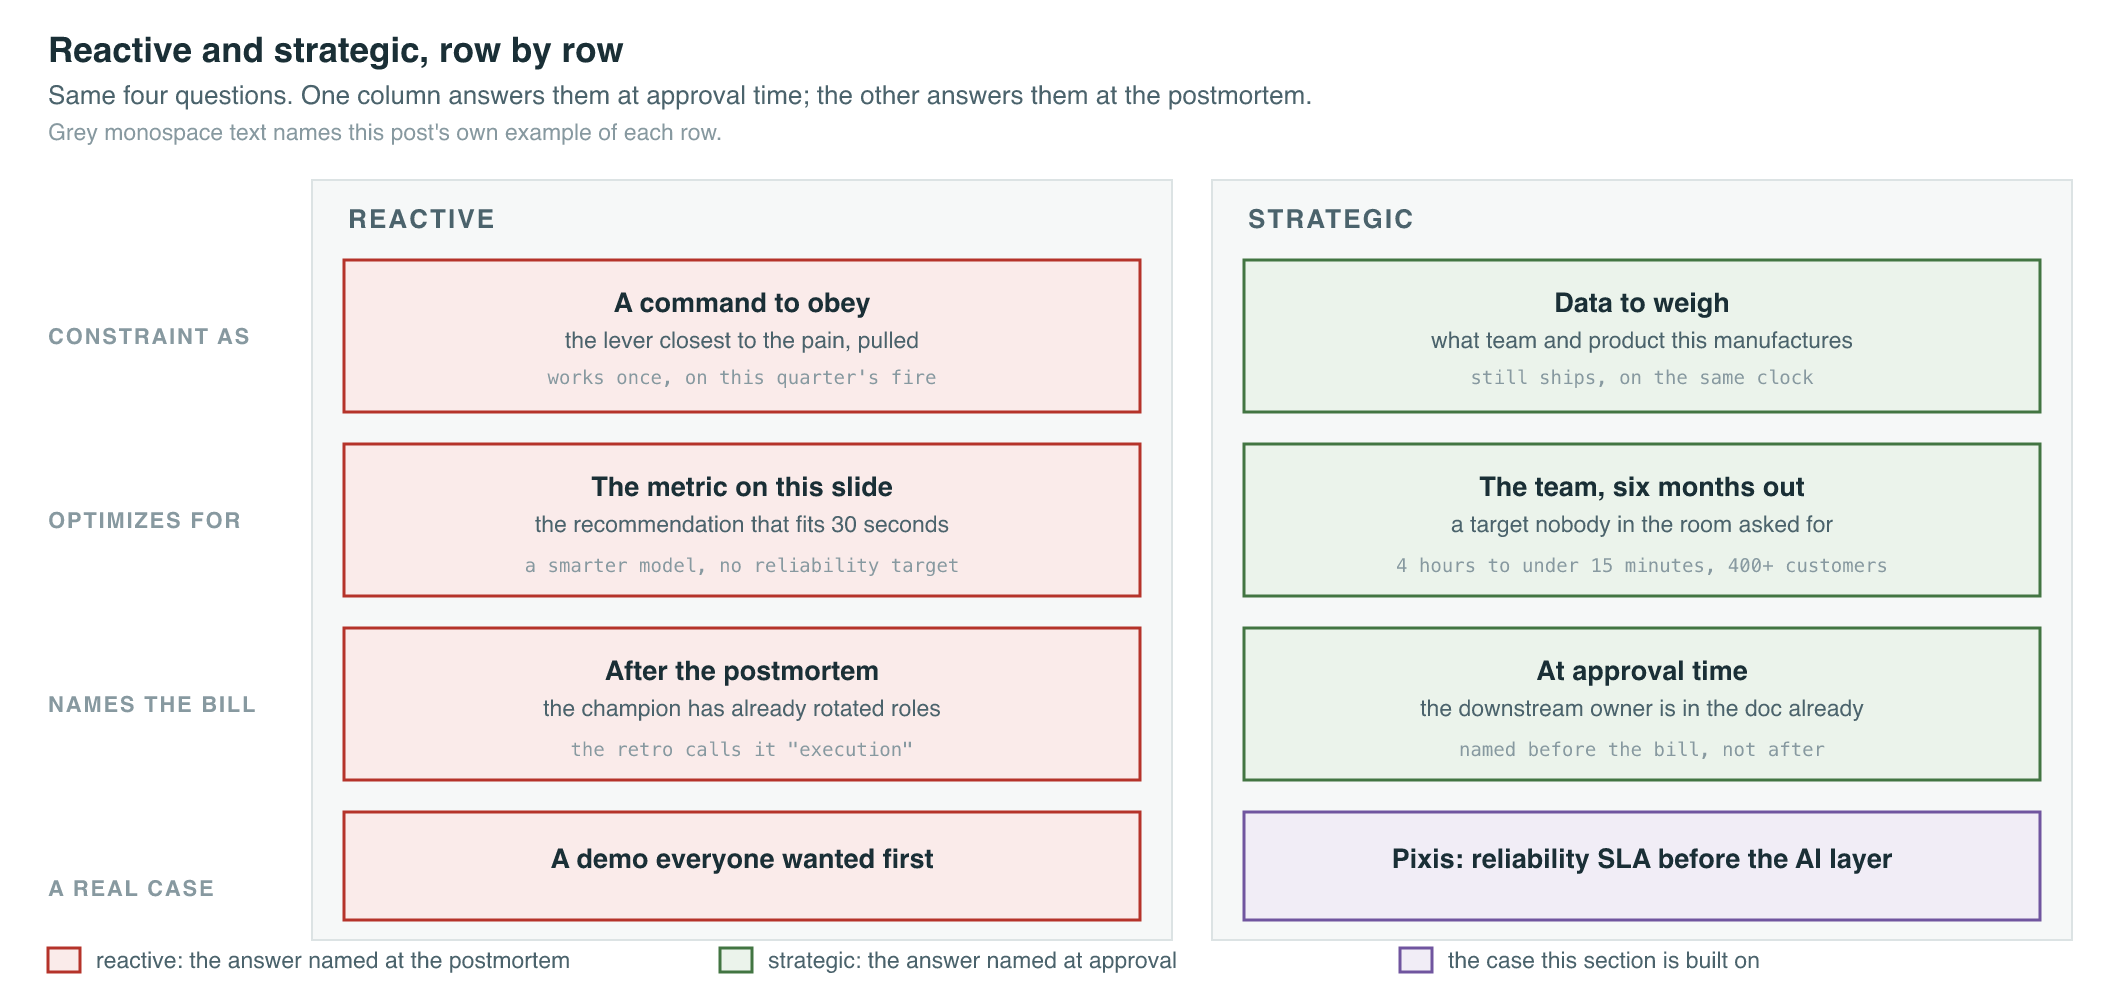
The Pixis reliability bet is the clearest case I have run personally. Advance, the optimization layer on top, was the part that demoed well. The first mandate I gave the twelve-person data pod underneath it was not a model improvement. It was a service-level target: cut data availability delay from four hours to under fifteen minutes across 400-plus enterprise customers. Nobody in the room asking for a smarter model was asking for that target. It is the reason the smarter model’s recommendations were worth acting on a year later.
6. What leadership has to change
Second-order thinking does not need a rare mind. It needs a rare tolerance for writing something down before it is interesting.
A decision record with four fields beats a good instinct every time: what we decided, what we believed would happen next, what would prove that belief wrong, and who owns the downstream effect if it does. That fourth field is the one most teams skip, and it is the one that keeps a launch from becoming a “we thought” six months later.
Four changes make the record worth keeping:
- Ask “and then what,” not just “did it ship.” A launch review that stops at ship date optimizes the team for launching.
- Reward the decline. Fifteen-plus voice-of-customer interviews only produce five good features if declining the other 40 carries no penalty for the PM who says no.
- Put the third-order owner in the doc, not just the first-order approver. The name closest to the eventual bill should be visible at approval time, not discovered at the postmortem.
- Tolerate “we were wrong.” VocalApply’s Gemini limitation lives on its own project page instead of a buried changelog line. That is the same habit, at a smaller scale, that a decision record asks a whole team to keep.
Takeaways
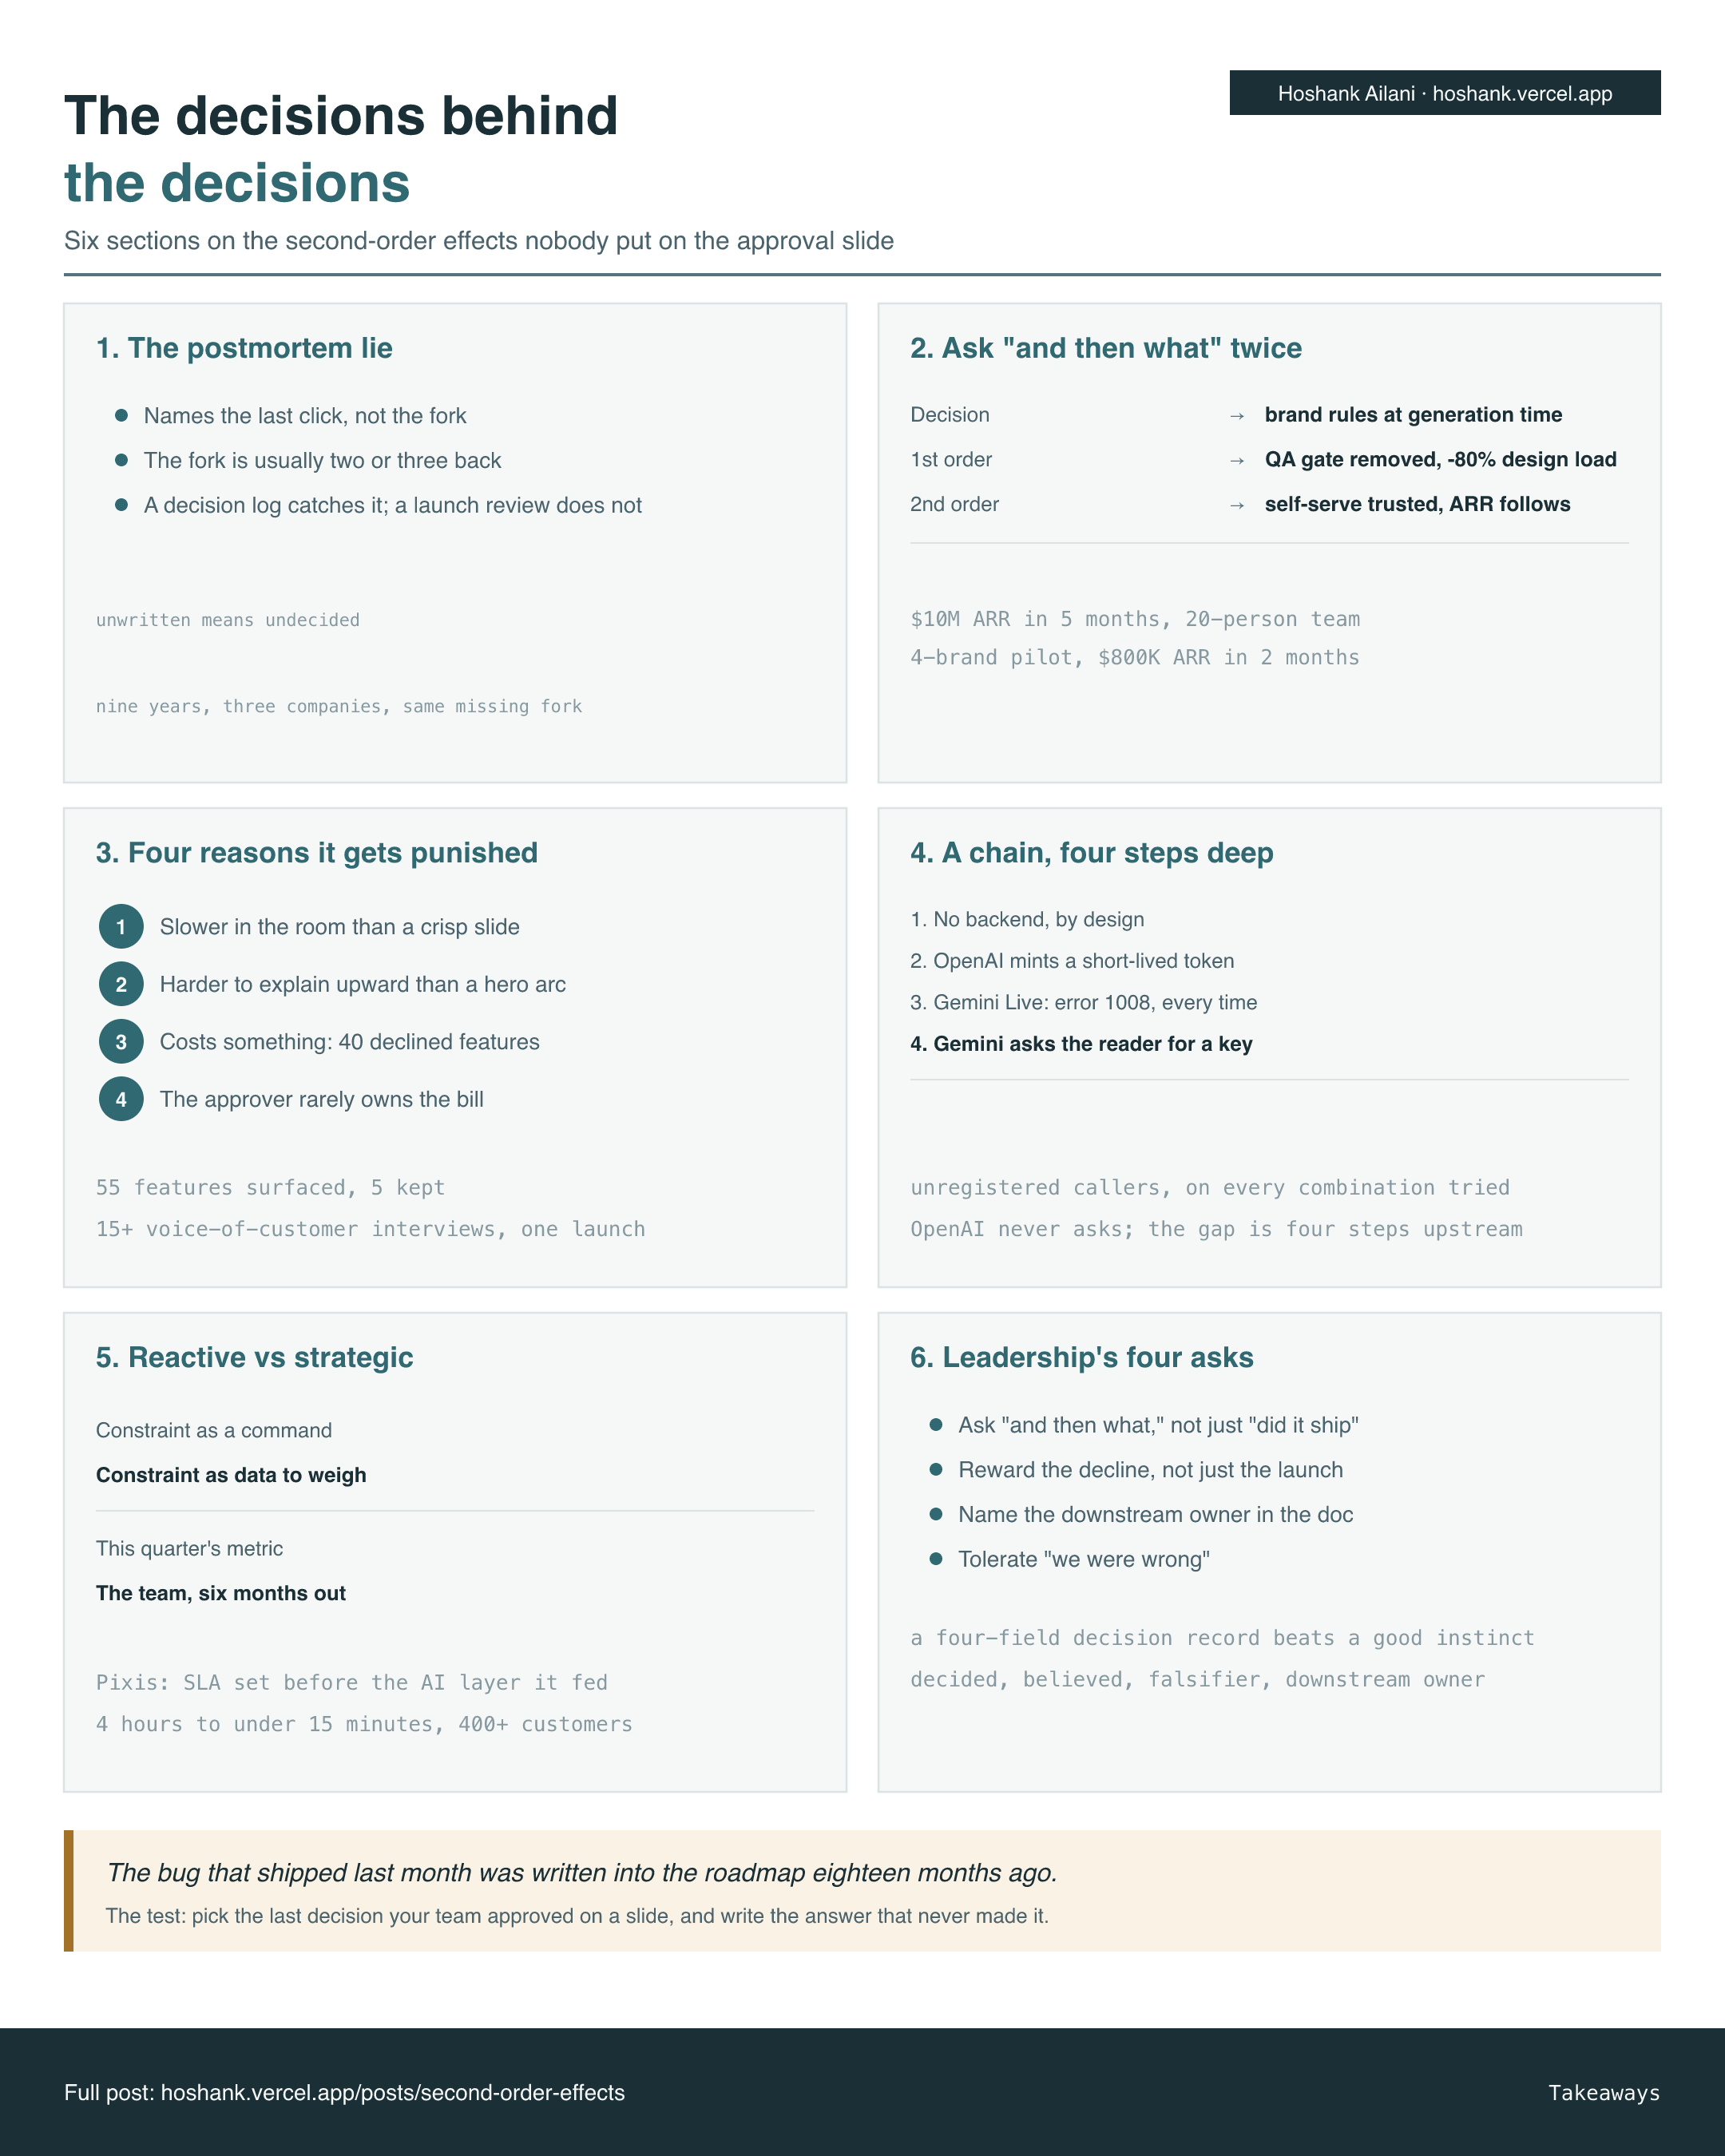
Six panels, one per section. The callout is the thesis, and the test to run on the last decision your team approved without asking what it changes downstream.
Final Words
Pick the last decision your team approved on a thirty-second slide. Write the second-order answer that never made that slide, and check who is holding it now.
Reply and tell me what you found. I am collecting the misses for a follow-up.
Cheers, Hoshank