A test that ships on a coin flip is worse than no test at all.
Every team I have sat inside called itself data-driven: supply-chain platforms at Dell, a 20-person AI creative team at Pixis, the DSP and exchange under InMobi that clock 200M+ devices’ worth of ad events a day. Ask any of them to defend the last split test they shipped on, and the defense collapses into “the number went up.”
That is not evidence. That is a team that needed a decision and found a chart willing to end the argument.
So that’s today’s post.
Today’s Post
Six reasons a split test stops being evidence, and the two questions to ask before you run one.
- Why “we tested it” became permission to stop arguing
- Optimization and innovation need different tools
- Most tests are underpowered before the argument starts
- The calendar kills the read before it arrives
- When to test, and when to think instead
- What leadership has to change for any of this to stick
1. “We tested it” became permission to stop arguing
Experimentation culture started as a corrective. It pushed teams to defend a claim with a number instead of a title.
Somewhere along the way, the ritual replaced the rigor. “We tested it” became a sentence that ends debate, because it sounds scientific whether or not it was.
Watch what gets tested. Button color, copy tweaks, layout variants, argued over for a sprint while the actual value proposition sits unexamined. In that shape, the test does not reduce uncertainty about what to build. It reduces the discomfort of choosing.
The tell is how the result gets used. A number that ends the meeting, with nobody having to argue for a worldview, is theater with a p-value attached.
2. Optimization and innovation need different tools
A/B tests earn their keep inside a narrow class of problem: a stable system, high traffic, and a question you can state as one sentence a new hire understands.
AdRoom, the AI creative product I led the platform team behind at Pixis, runs exactly that kind of test: bulk A/B variants of an ad, same brand, same funnel, same audience, comparing two known executions of the same idea. That is optimization, and a controlled comparison is the right instrument for it.
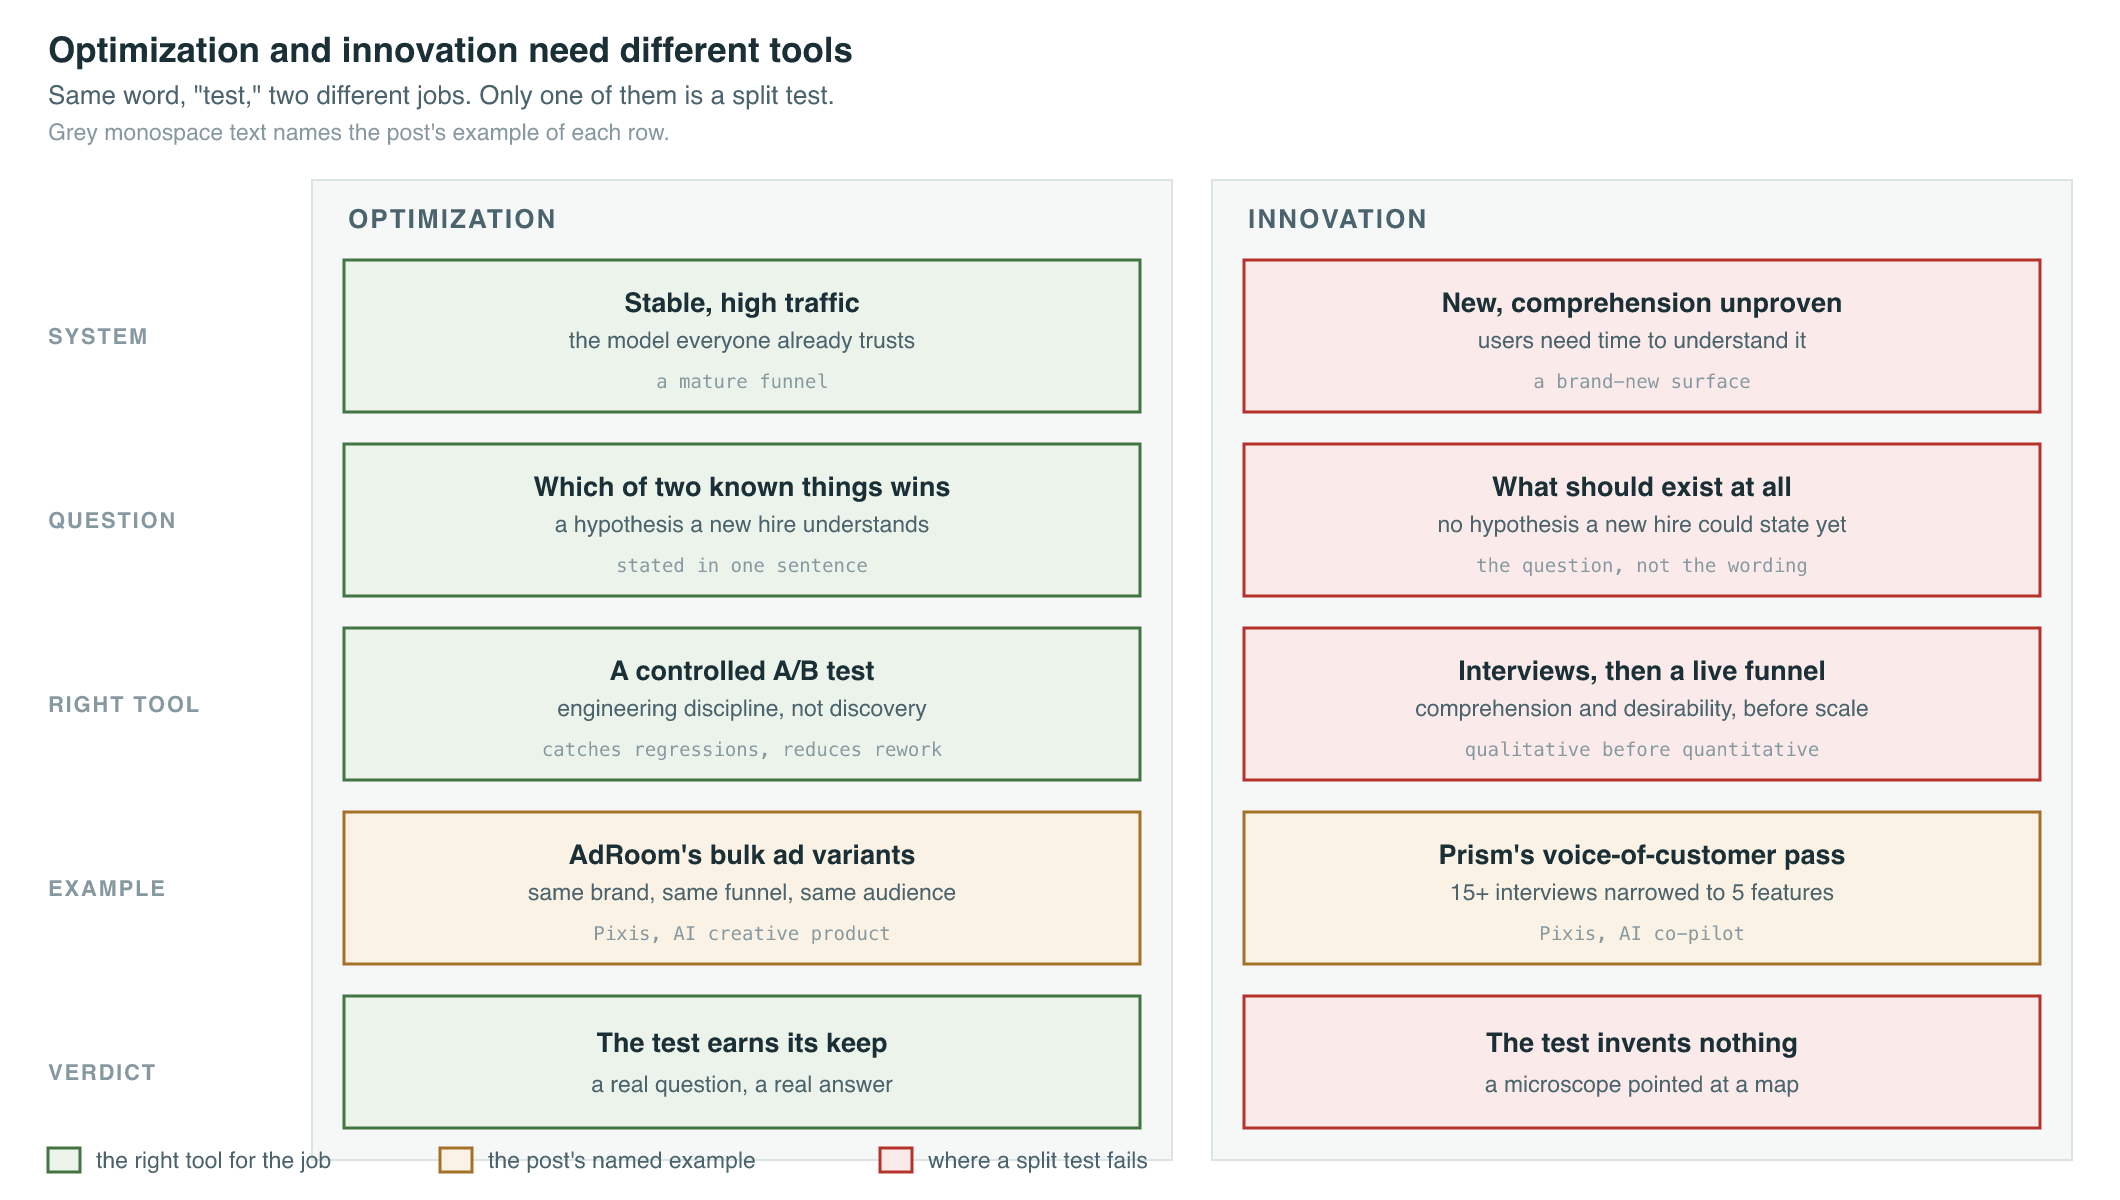
Prism, the AI co-pilot I later led the 15-person team behind, is the other kind of problem: a new surface, unproven comprehension, users who need time to understand what you built. We ran 15+ voice-of-customer interviews before we shipped a single variant, and those interviews narrowed the roadmap to exactly 5 features, not fifty. A split test on a co-pilot nobody understands yet does not answer “does this work.” It answers “which confusing version did fewer people abandon this week,” and that is a different question dressed up as the same one.
My grade for a team that A/B tests its way into a brand-new product surface: 2/10. Talk to fifteen people first.
Using a split test to validate a bet on comprehension is a microscope pointed at a map. The instrument is precise. The job is wrong.
3. Most tests are underpowered before the argument starts
Statistical literacy in product organizations is uneven, and that unevenness does not stop teams from running tests.
Power is the first casualty. The effect size that actually matters to the business is often smaller than what a week of traffic can detect. The test produces a result that is technically a result and practically meaningless.
Peeking is the second. A p-value gets treated like a verdict, but significance is a function of sample size, variance, and how many times you looked. Look often enough and something will cross the line.
Multiple comparisons are the third. Run enough variants, segments, and metrics and something wins by chance. If the process rewards winners, the process will manufacture winners.
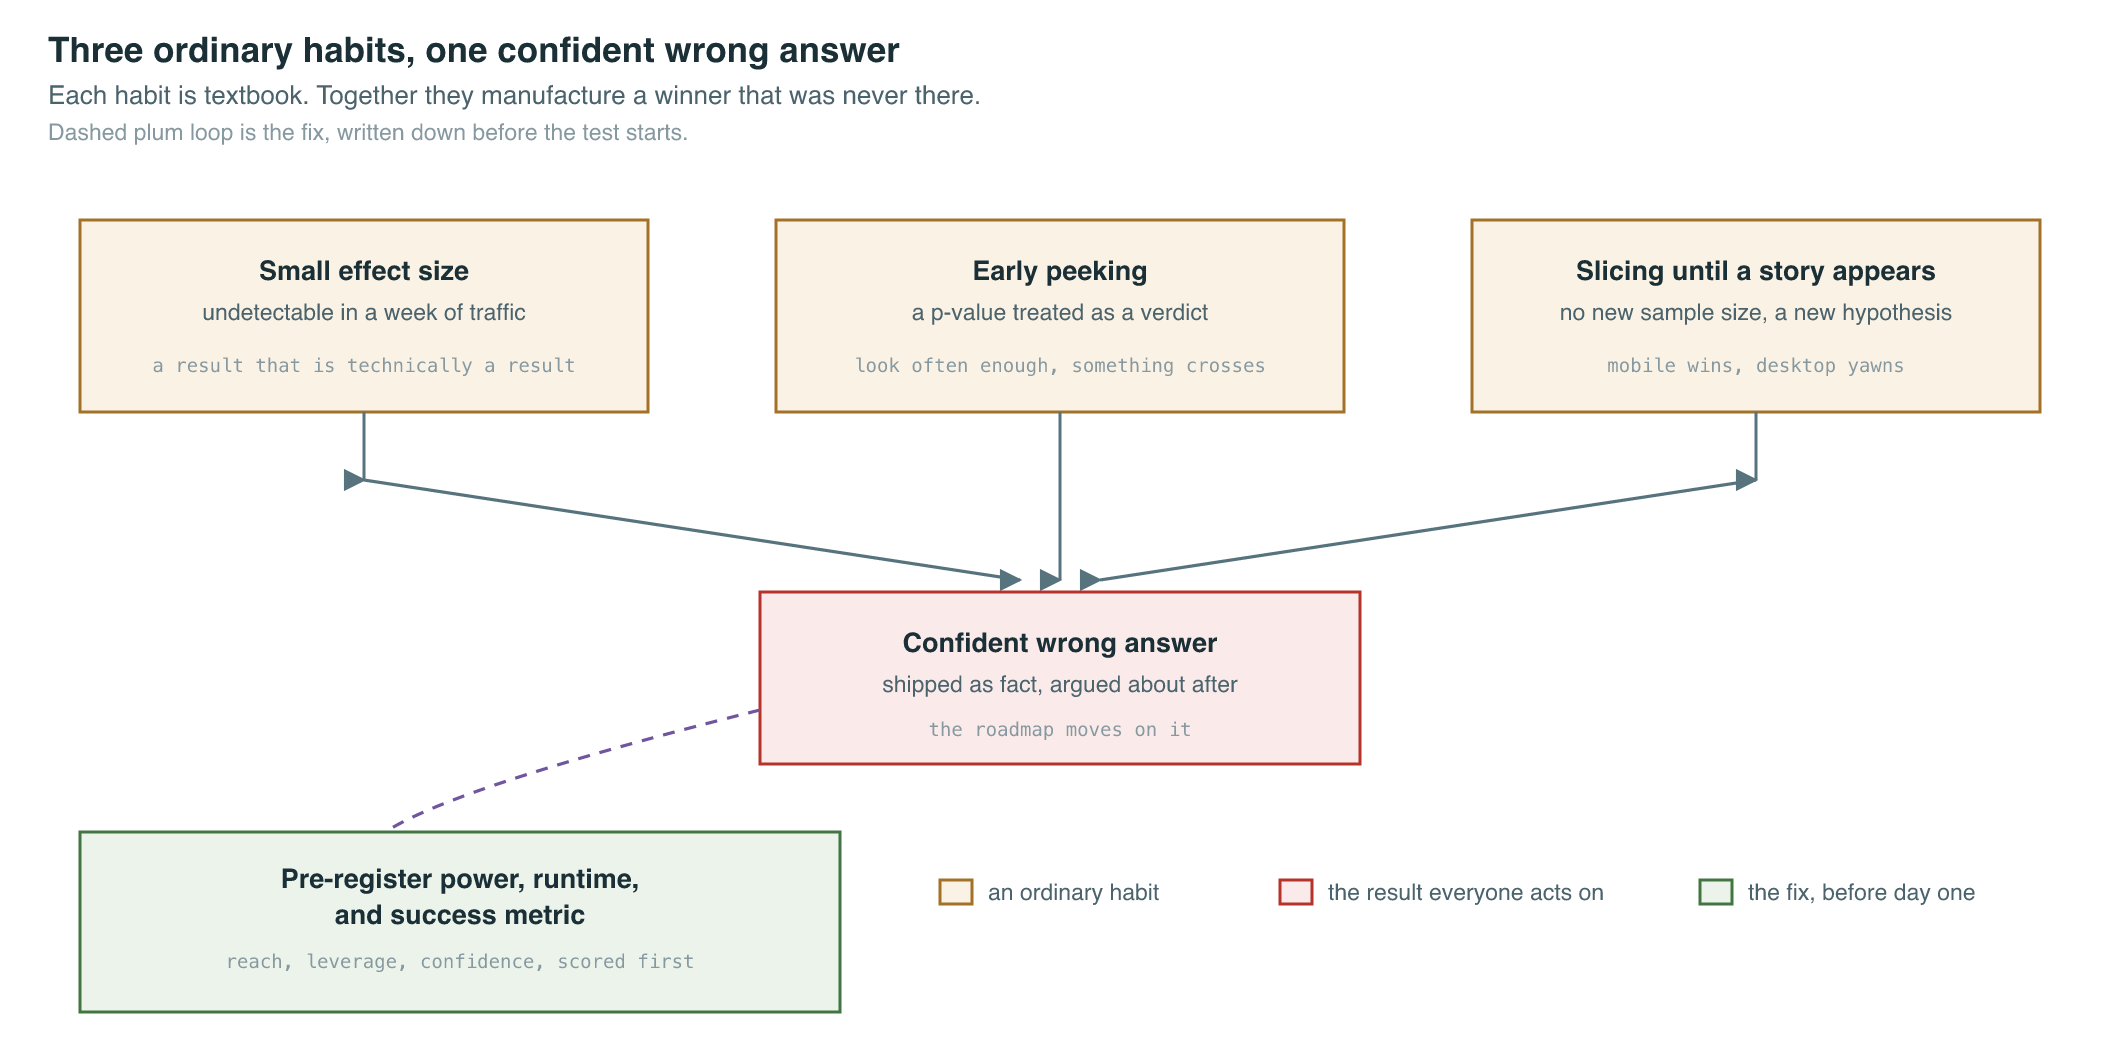
None of this is a secret; it is textbook. The pressure to ship, to show movement, and to publish a win overwhelms the boring work of designing a test that can answer the question it claims to answer.
The Claude Code adoption experiments on this site’s own tree are the boring version done right: six draft specs, each scored on reach, leverage, and confidence before anyone builds, with a run order set in advance instead of picked after the fact. That scoring is what a pre-registered test looks like when nobody is under a launch deadline.
4. The calendar kills the read before it arrives
Teams stop tests early because the calendar demands closure, not because the data is ready to speak.
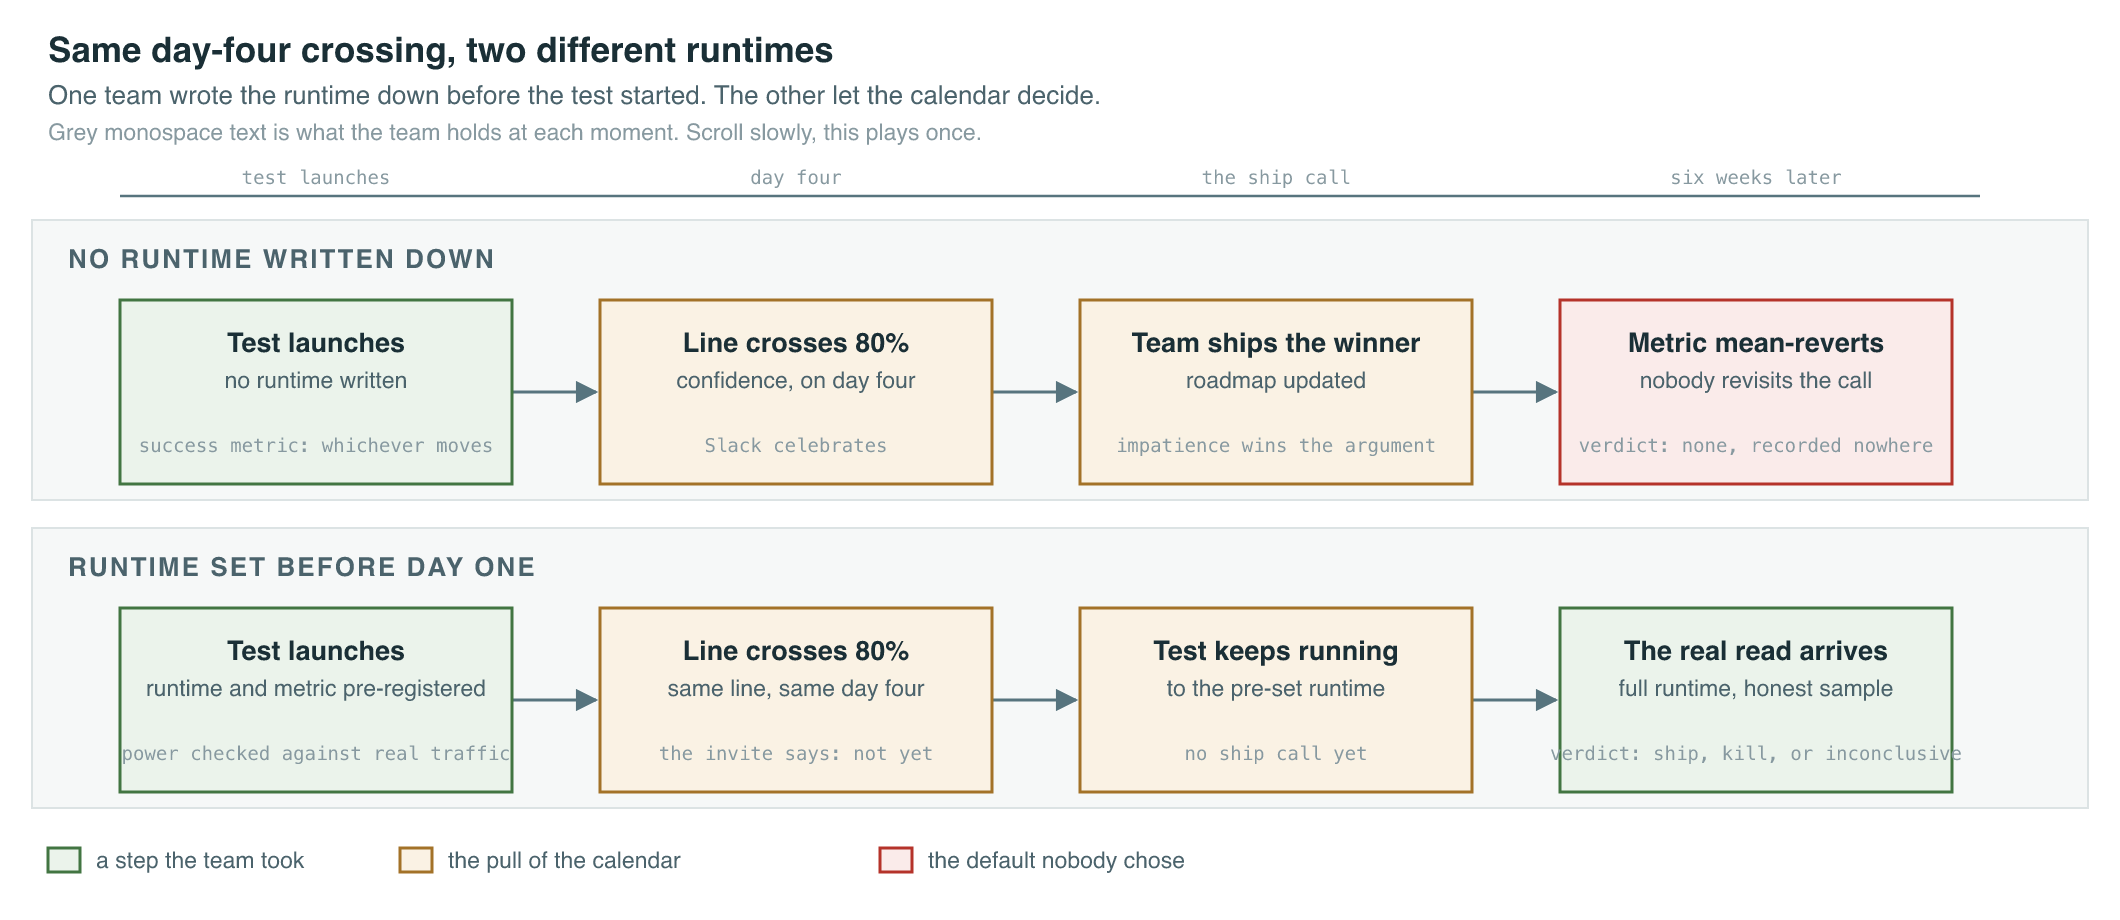
A line crosses a threshold on day four. The team declares a winner. Six weeks later the metric mean-reverts and nobody wants to revisit the decision, because revisiting feels like admitting the ritual failed.
Real experimental discipline includes deciding, in advance, how long the world needs to speak before anyone is allowed to listen. That is a product judgment about the kind of change you made, not a statistical nicety you bolt on after the dashboard moves.
5. When to test, and when to think instead
Use a split test when the system is stable, the question is narrow, and the traffic can support the bar you claim to care about. AdRoom’s variant testing fits; a mature funnel with a small, intentional change fits; a guardrail check while refactoring fits.
Skip it when you are still discovering what should exist. Interviews, prototypes, and a live funnel you are willing to watch closely tell you different things than a split test does, the way Prism’s 15+ interviews told us which 5 features to build before a single variant existed.
Skip it when traffic is low. A small surface cannot manufacture sample size by enthusiasm.
Skip it when you cannot state the hypothesis in one sentence a new hire understands. That is not a testing problem. That is a thinking problem, and no dashboard fixes it.
6. What leadership has to change
An individual PM’s discipline gets one good test. The habit survives only when the organization is built for it.
- Write the runtime down before day one. Not after the line crosses a threshold.
- Separate execution failures from assumption failures at review, so a bug and a wrong bet do not get the same postmortem.
- Reward the inconclusive result. If leadership punishes “no difference,” the team will manufacture a difference.
- Treat post-hoc slices as a new hypothesis, not proof. A slice that wins after the fact earns a second test, not an automatic roadmap slot.
Ad tech solved a version of this years ago: nobody lets an ad network grade its own installs, and the industry built an entire referee category, the MMP, because marking your own homework does not survive contact with money. Product teams mark their own homework every quarter and call it a launch review.
The InMobi close is the clean counter-example, and it never ran a split test. Finance could already see every line of revenue from those 200M+ devices’ worth of daily events; the close moved from 5 days to 12 hours because a target was written down and reviewed against a date, the same discipline this site’s measurement post argues for. Data disciplined a point of view. It did not invent one.
Takeaways
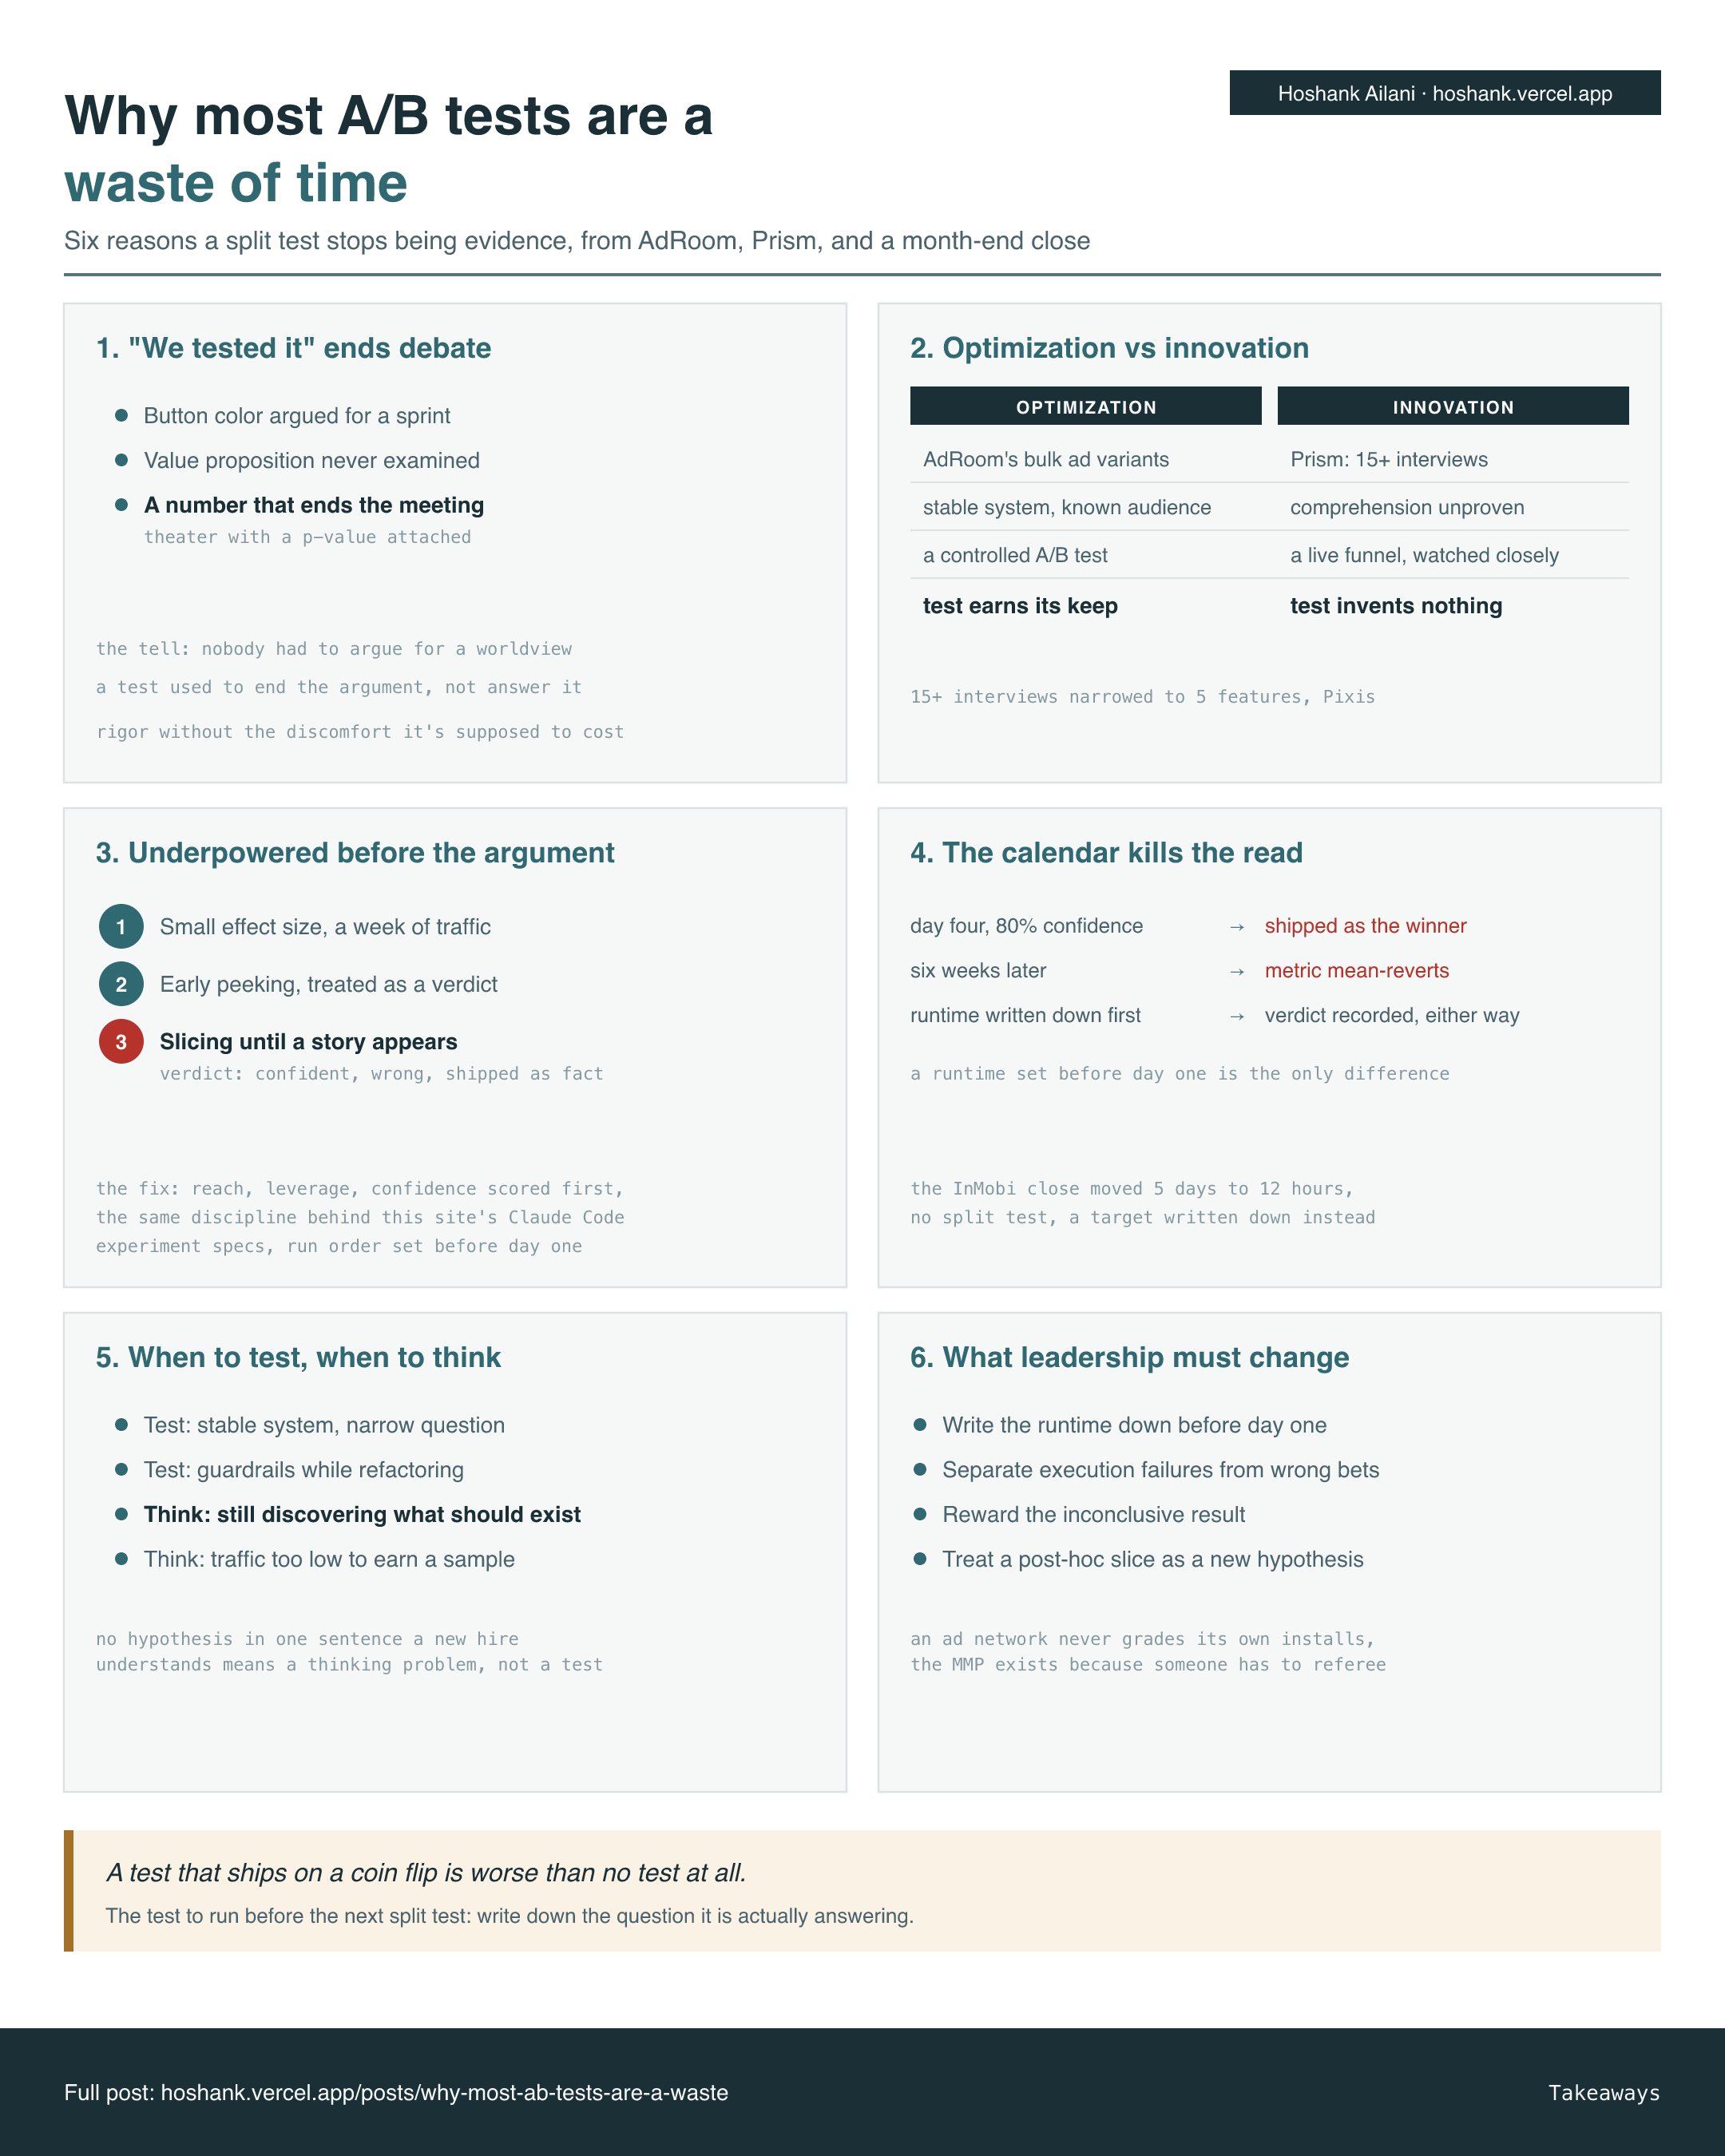
Six panels, one per section. The callout is the test to run before you greenlight the next split test.
Final Words
Most teams have the tooling to run a split test and not the discipline to know when one answers the question. Pick the last test your team shipped on, write down what question it was actually answering, and check whether a stable system with real traffic was underneath it.
Reply and tell me what you found.
Cheers, Hoshank